线性解混得分方法:通过密集的未观察到混得分 DAG

IEEE transactions on neural networks and learning systems
|January 29, 2024

概括
这项研究引入了一种新的方法,可以从观测数据中发现因果关系,即使没有测量的混. 该方法利用独立机制的原则来确定复杂系统中真正的因果关系.
科学领域:
- 因果推理因果推理
- 机器学习 机器学习
- 统计建模 统计建模
背景情况:
- 没有测量的混对从观测数据中发现因果关系构成了重大挑战.
- 基于约束的方法在未观察到的变量广泛影响观察到的变量时遇到困难,导致无法识别的因果关系.
- 现有的方法在高维环境中经常失败,并且存在广泛的未观察到的混.
研究的目的:
- 开发一种方法来发现在存在未测量的混时的因果关系.
- 利用独立机制的原则来分离假效应和因果关系.
- 提出一个可扩展的算法,用于复杂系统的因果发现.
主要方法:
- 利用独立机制的原则来识别未观察到的混杂的统计足迹.
- 应用稀疏线性高斯定向非循环图 (DAG) 模型用于因果结构恢复.
- 开发一个基于得分的调整因果发现算法,与通用解决方案兼容.
主要成果:
- 根据独立机制的原则,证明未观察到的混会留下可检测的统计足迹.
- 表明,一个稀疏的线性高斯式DAG可以从观测数据中大致恢复.
- 拟议的算法可扩展到高维问题,并且对模型假设的偏差具有稳定性.
结论:
- 通过利用独立机制原则,即使存在广泛的未测量混,因果发现也是可行的.
- 开发的算法提供了一个可扩展和强大的解决方案,用于识别复杂的观测数据集中的因果结构.
- 该方法显示了扩展到非线性结构模型的潜力,扩大了其适用性.


相关概念视频
 01:25
Strategies for Assessing and Addressing Confounding
101
Confounding is a critical issue in epidemiological studies, often leading to misleading conclusions about associations between exposures and outcomes. It occurs when the relationship between the exposure and the outcome is mixed with the effects of other factors that influence the outcome. Given that, addressing confounding is of high importance for drawing accurate inferences in research.
Confounding can be addressed at both the design phase of a study and through analytical methods after data...
Confounding can be addressed at both the design phase of a study and through analytical methods after data...
101
 01:27
Confounding in Epidemiological Studies
170
Confounding in statistical epidemiology represents a pivotal challenge, referring to the distortion in the perceived relationship between an exposure and an outcome due to the presence of a third variable, known as a confounder. This variable is associated with both the exposure and the outcome but is not a direct link in their causal chain. Its presence can lead to erroneous interpretations of the exposure's effect, either exaggerating or underestimating the true association. This...
170
 01:21
Friedman Two-way Analysis of Variance by Ranks
197
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
197
 01:24
Confidence Coefficient
7.6K
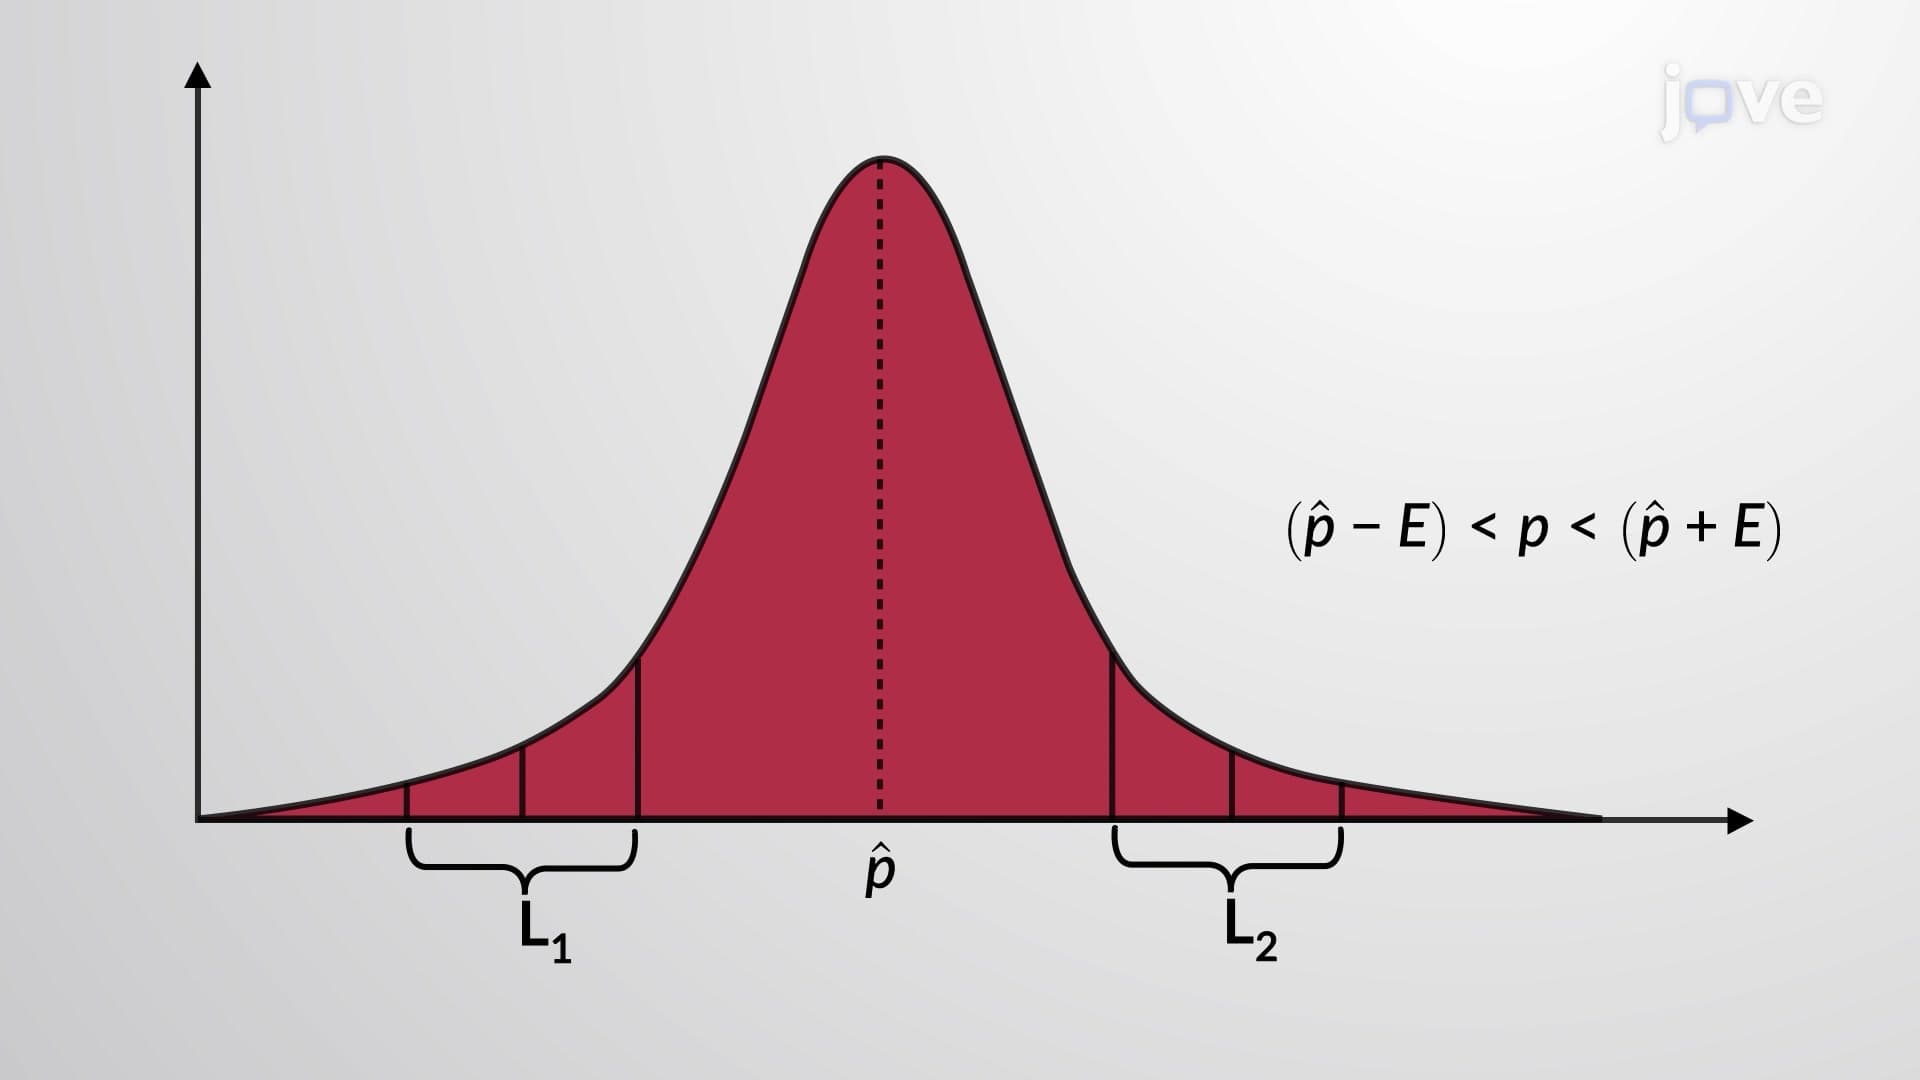
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.6K
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
507
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
507
 01:17
z Scores and Area Under the Curve
10.6K
z scores are the standardized values obtained after converting a normal distribution into a standard normal distribution. A z score is measured in units of the standard deviation. The z score tells you how many standard deviations the value x is above (to the right of) or below (to the left of) the mean, μ. Values of x that are larger than the mean have positive z scores, and values of x that are smaller than the mean have negative z scores. If x equals the mean, then x has a z score of...
10.6K