新的研究用于检测具有随机性的变量之间的复杂关联
相关实验视频
Updated: Jul 4, 2025

06:35
Basics of Multivariate Analysis in Neuroimaging Data
Published on: July 24, 2010
16.9K
Yuwen Du1, Bin Nie1, Jianqiang Du1
1School of Computer, Jiangxi University of Chinese Medicine, Nanchang 330004, China.
Mathematical biosciences and engineering : MBE
|February 2, 2024

概括
这项研究引入了相关性分析 (RVCR-CA) 的新框架,该框架考虑了数据不确定性和分布. 它改善了随机变量之间的关系的识别,优于传统方法.
科学领域:
- 统计 统计 统计 统计
- 数据分析 数据分析
- 机器学习 机器学习
背景情况:
- 传统的相关性分析方法往往忽略了数据的不确定性和分布状态.
- 这种限制阻碍了对变量之间的函数关系的准确识别,特别是那些具有特定分布的变量.
研究的目的:
- 提出一种新的相关性分析框架 (RVCR-CA),用于检测随机变量之间的关联.
- 通过考虑功能关系,不确定性和分布依赖性来增强可变相关性的评估.
主要方法:
- 计算正常化的RMSE以评估功能关系的程度.
- 使用差量测量不确定性.
- 使用copula函数来评估对随机变量与分布的依赖.
- 将这些指标结合起来,使用加权的总和来得出最终的相关系数 (R).
主要成果:
- 拟议的RVCR-CA方法在评估特定分布的变量之间的相关性方面表现出卓越的表现.
- 与传统方法相比,对UCI和合成数据集的实验显示了更全面的评估能力.
- 该框架有效地识别了连接,即使对于没有明确的功能关系的变量.
结论:
- RVCR-CA框架为相关性分析提供了更强大,更全面的方法.
- 它准确地测量了具有特定分布和不确定的数据的变量之间的相关性.
- 这种方法增强了对复杂数据集中的关系的理解.
相关概念视频
 01:13
Randomized Experiments
6.9K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.9K
 01:09
Random Variables
12.0K
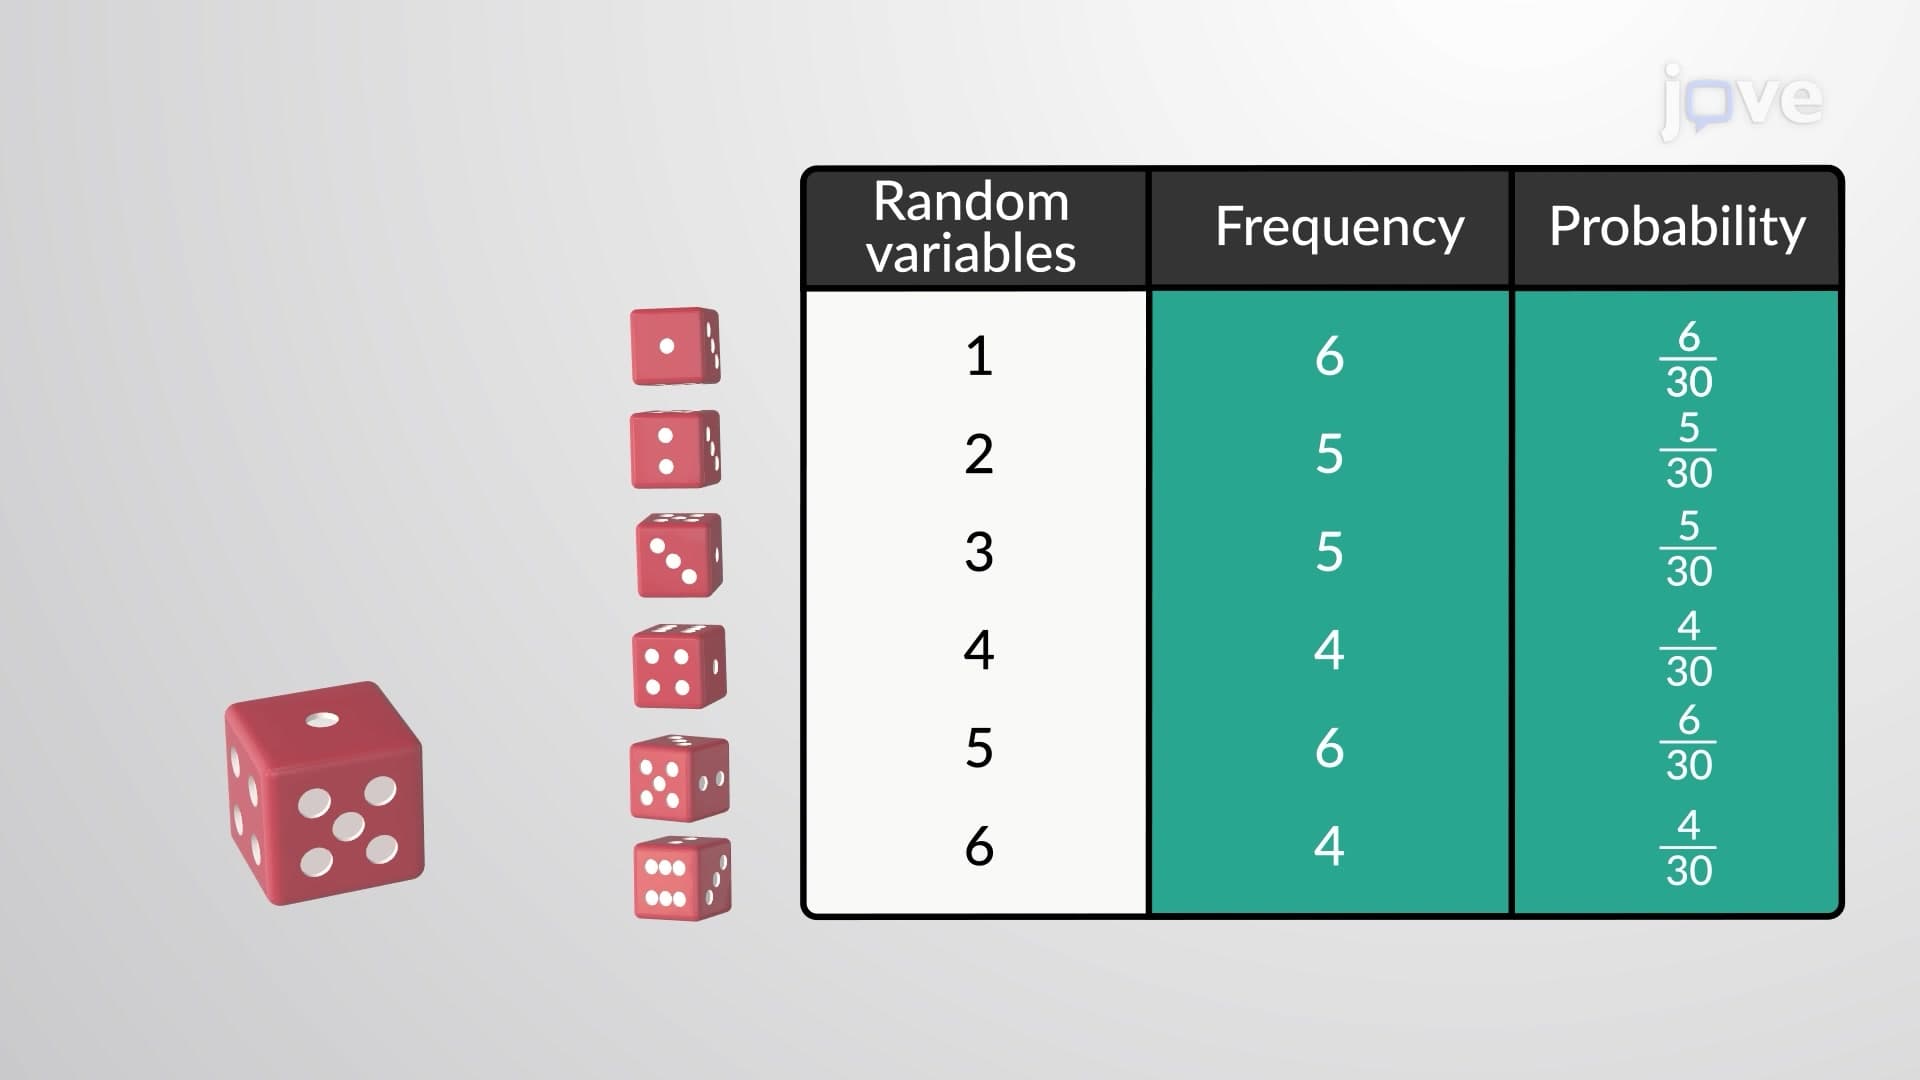
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
12.0K
 01:17
Wald-Wolfowitz Runs Test II
244
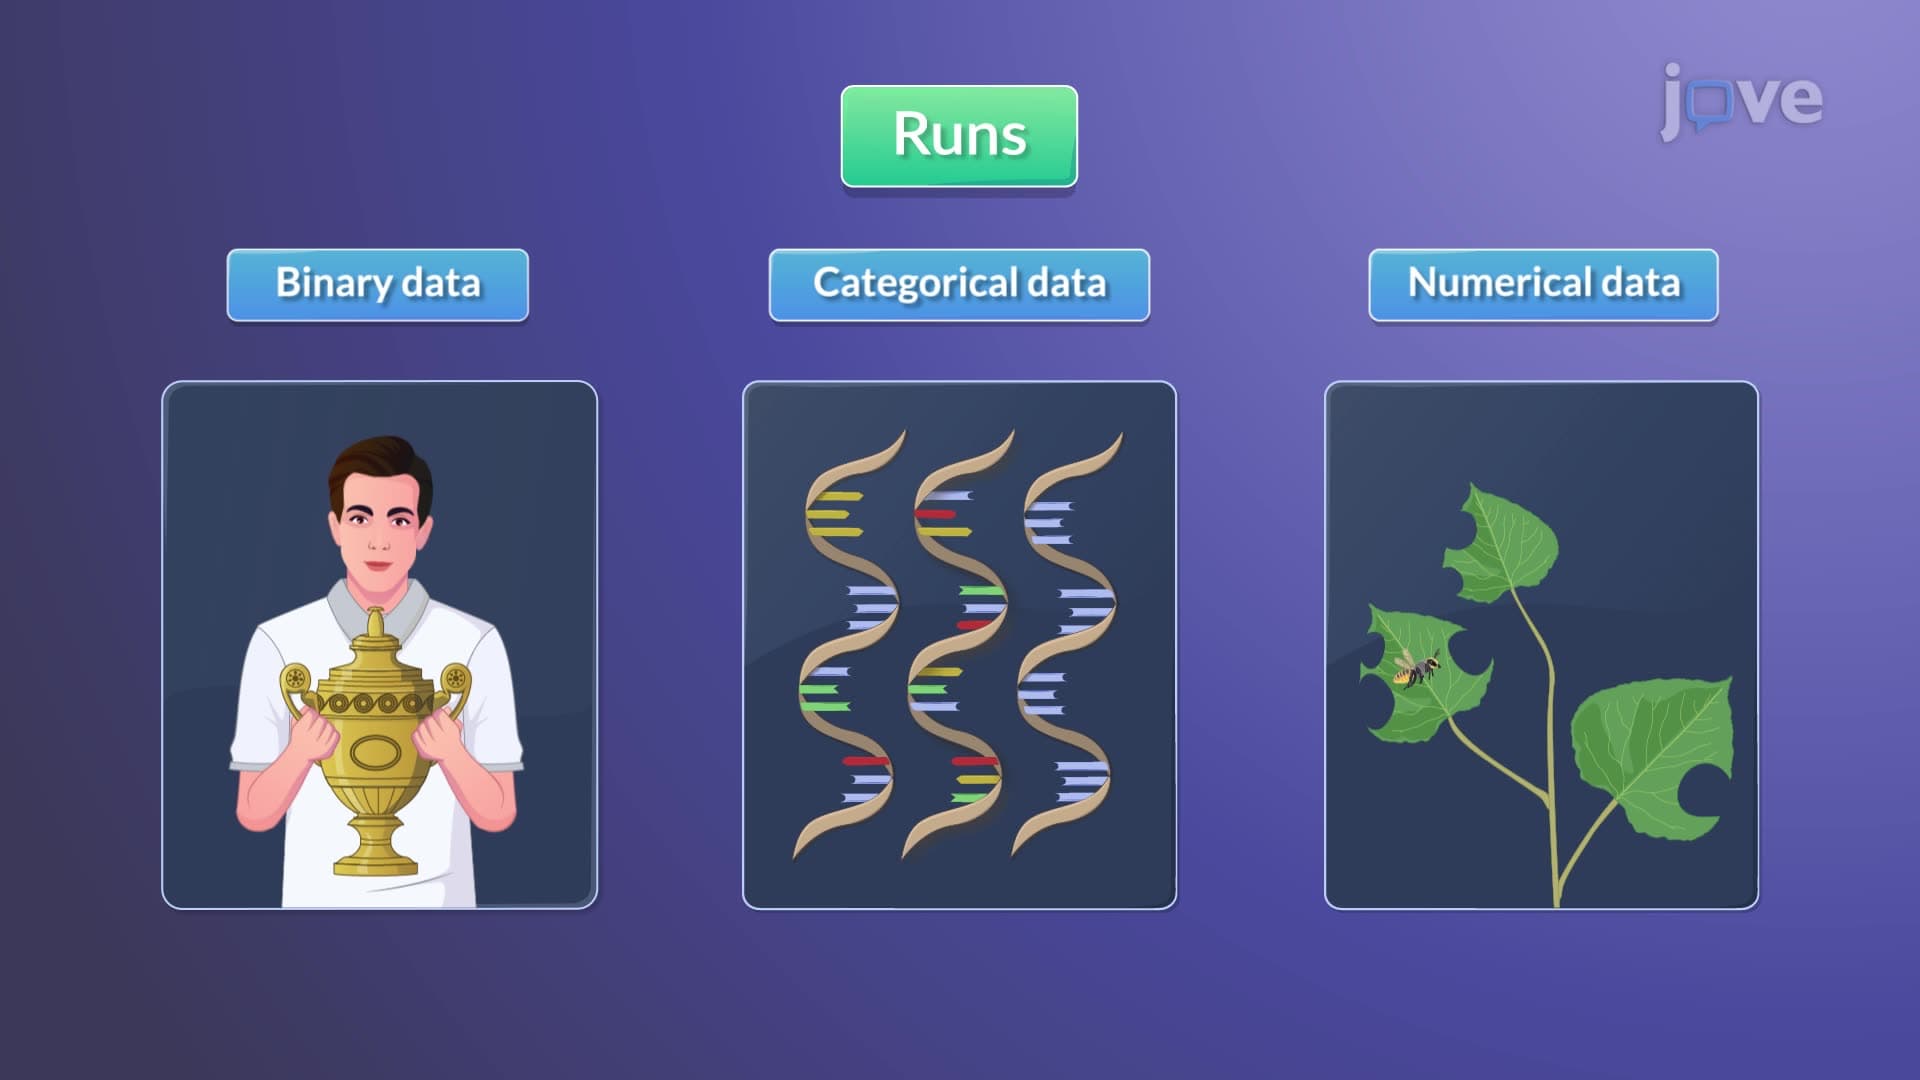
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
244
 02:01
Group Design
8.9K
The most basic experimental design involves two groups: the experimental group and the control group. The two groups are designed to be the same except for one difference— experimental manipulation. The experimental group gets the experimental manipulation—that is, the treatment or variable being tested—and the control group does not. Since experimental manipulation is the only difference between the experimental and control groups, we can be sure that any differences between...
8.9K
 01:17
Wald-Wolfowitz Runs Test I
648
The Wald-Wolfowitz test, also known as the runs test, is a nonparametric statistical test used to assess the randomness of a sequence of two different types of elements (e.g., positive/negative values, successes/failures). It examines whether the order of the elements in a sequence is random or if there is a pattern or trend present. This nonparametric test applies to any ordered data despite the population and sample data distribution, even if a higher sample size is available.
The test works...
The test works...
648
 01:16
Unusual Results
3.2K
Unusual results are those that have a very low chance of occurring. Unusual results can be identified using probabilities and the range rule of thumb. In problems involving probability, unusual results can be observed in 2 instances – an unusually high number of successes or an unusually low number of successes.
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
3.2K