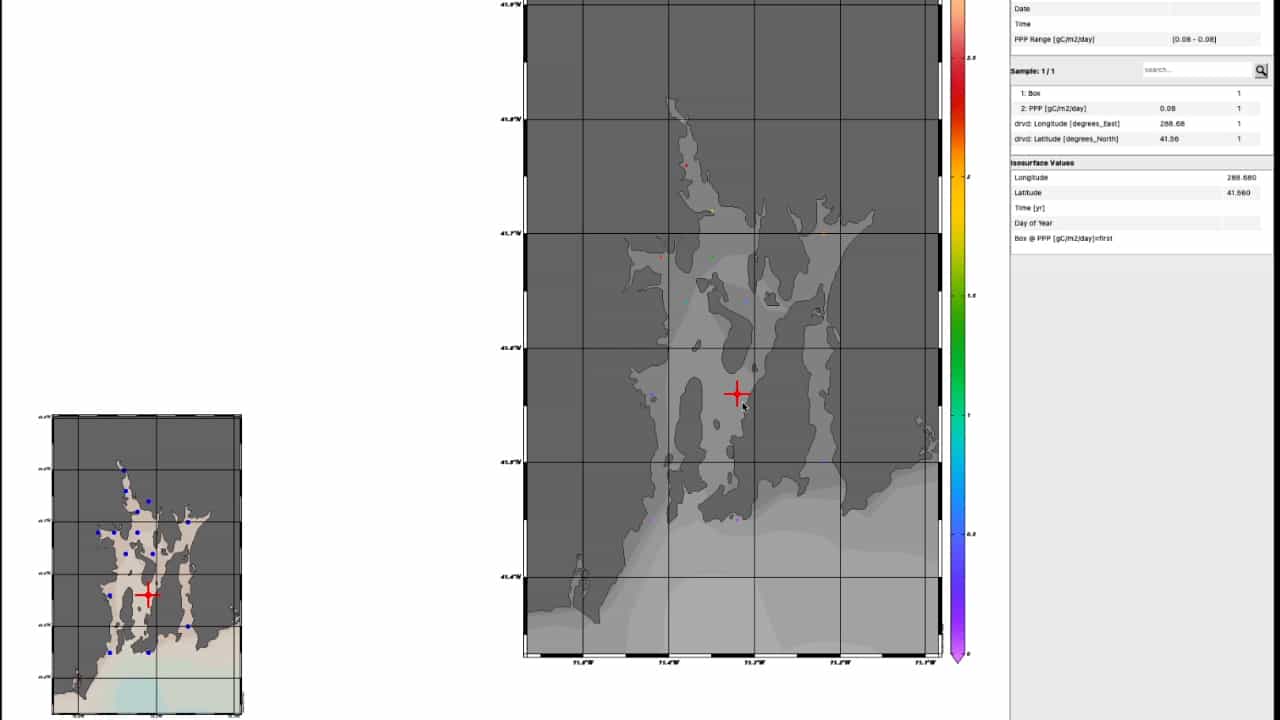

评估贝叶斯地缘统计预测在切萨皮克湾的物理障碍的性能
M R Desjardins1, B J K Davis2,3, F C Curriero2
1Spatial Science for Public Health Center, Department of Epidemiology, Johns Hopkins Bloomberg School of Public Health, Baltimore, MD, USA. mdesjar3@jhu.edu.
Environmental monitoring and assessment
|February 12, 2024

概括
贝叶斯地缘统计模型准确地预测了切萨皮克湾的盐度,超过了传统方法. 这些模型更好地捕捉了基于水的距离和不确定性,这对于河口水质监测至关重要.
科学领域:
- 环境科学 环境科学
- 地质统计学 在地质统计学
- 统计建模 统计建模
背景情况:
- 切萨皮克湾的水质通过固定站进行广泛监测.
- 地理统计模型从监测数据中预测水质指标.
- 比起频率主义方法,贝叶斯式方法在推断和不确定性量化方面具有优势.
研究的目的:
- 比较贝叶斯地缘统计模型 (静止和屏障INLA) 与普通的Kriging用于切萨皮克湾的盐度预测.
- 根据使用交叉验证的预测准确度和精度来评估模型性能.
- 评估欧几里德式与非欧几里德式距离测量在河口环境中的适用性.
主要方法:
- 实施的静止和屏障集成嵌套拉普拉斯近似 (INLA) 地统模型.
- 使用普通战争作为基准频率的地缘统计模型.
- 对所有模型进行了交叉验证,使用2019年切萨皮克湾盐度数据超过四个月.
主要成果:
- 与普通战争相比,贝叶斯INLA模型表现出更高的性能.
- 观察到更好的预测准确度,特别是在切萨皮克湾的支流.
- 非欧几里德模型有效地纳入了基于水的距离,并改进了不确定性表征.
结论:
- 贝叶斯地缘统计模型,特别是非欧几里德的方法,对于河口盐度预测非常有效.
- 这些方法提供了更准确的水质评估和不确定性量化.
- 进一步的研究可以探索屏障INLA模型在更复杂的水生系统中的有效性.
相关概念视频
 01:17
Design Example: Analyzing Capacity Contours for Flood Risk Assessment
47
Flood risk assessment involves careful planning and analysis to ensure the safety of communities near water retention structures. Capacity contours are a vital tool in this process, as they illustrate the potential spread of water at specific levels in a given area. In the context of building a bund across a small valley, these contours play a critical role in evaluating the safety of nearby residential areas.In this example, the bund is intended to store stormwater in the valley. The engineers...
47
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:16
Estimating Population Mean with Known Standard Deviation
8.3K
To construct a confidence interval for a single unknown population mean μ, where the population standard deviation is known, we need sample mean as an estimate for μ and we need the margin of error. Here, the margin of error (EBM) is called the error bound for a population mean (abbreviated EBM). The sample mean is the point estimate of the unknown population mean μ.
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate +...
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate +...
8.3K
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
433
Parametric survival analysis models survival data by assuming a specific probability distribution for the time until an event occurs. The Weibull and exponential distributions are two of the most commonly used methods in this context, due to their versatility and relatively straightforward application.
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
433
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K