

根据旅行方式对可访问性和家庭旅行频率的联合分析
Abhilash C Singh1, Ahmadreza Faghih Imani2, Aruna Sivakumar1
1Urban Systems Lab and Centre for Transport Studies, Imperial College London, London SW7 2AZ, United Kingdom.
Transportation research. Part A, Policy and practice
|March 11, 2024

概括
家庭旅行行为是复杂的. 这项研究表明,住宅可访问性和旅行频率是相互关联的,影响了选择汽车,交通,自行车和步行旅行的选择.
科学领域:
- 城市规划 城市规划
- 运输 地理 交通 地理
- 行为经济学是一种行为经济学.
背景情况:
- 了解家庭旅行模式对于有效的城市规划和交通管理至关重要.
- 现有的研究往往独立地对待可访问性和旅行频率,可能忽视了复杂的相互依存关系.
研究的目的:
- 在多种旅行方式中调查住宅可访问性和家庭旅行频率之间的内生关系.
- 区分可访问性对旅行行为的直接和间接影响,考虑观察到的行为差异.
- 分析外部变量对可访问性水平和旅行频率的影响.
主要方法:
- 使用2016年交通运输明天调查 (TTS) 数据对多变量有序探针模型系统的估计.
- 该模型考虑了影响旅行决策的观察和未观察因素的依赖性.
- 对八个结果变量进行了分析,这些变量与四种模式的可访问性和旅行频率有关:汽车,交通,自行车和步行.
主要成果:
- 住宅可访问性和家庭出行频率之间存在强烈的相关性.
- 证实了可访问性对旅行频率的直接影响,挑战了更简单的模型.
- 观察到汽车可访问性和交通旅行之间的互补性,以及交通可访问性和汽车旅行之间的替代性,表明交通用户之间的住宅社区不和.
- 拥有优质交通服务的地点并不总是与居民更高的交通旅行量相关.
结论:
- 可访问性和按模式的行程频率不是独立的选择,而是构成一个捆绑的决定.
- 可访问性和旅行频率之间的关联 (错误相关性) 和方向效应需要一个整体的方法来理解旅行行为.
- 调查结果表明,城市规划策略应该考虑可访问性和旅行模式选择的综合性.
相关概念视频
 01:17
Probability Histograms
11.5K
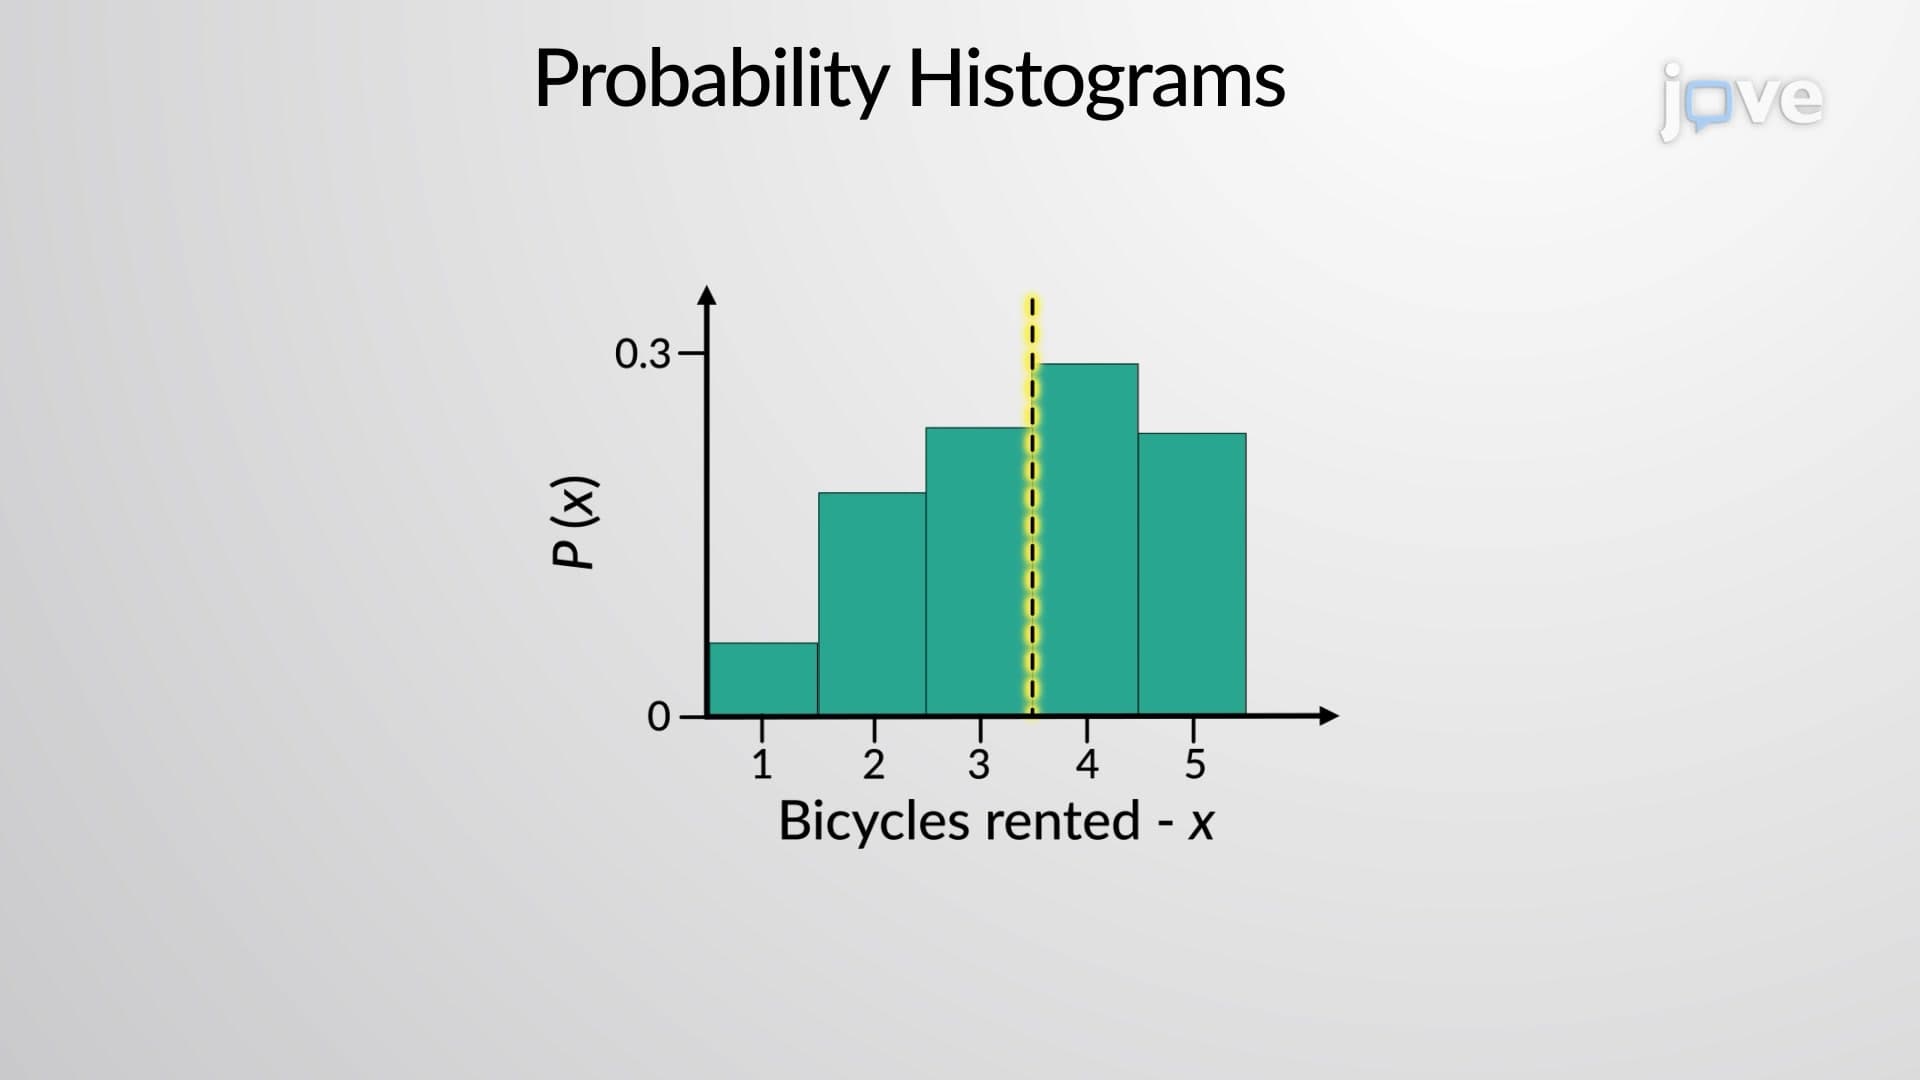
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
11.5K
 01:05
Noncompartmental Analysis: Mean Residence Time
140
According to statistical moment theory, mean residence time (MRT) is an important measure in pharmacokinetics. MRT can be defined as the expected mean of a probability density function distribution. It provides valuable insights into drug disposition in the body.
After the administration of a drug through intravenous bolus injection, the drug molecules are distributed throughout the body and remain there for varying periods. The MRT represents the average time these drug molecules stay in the...
After the administration of a drug through intravenous bolus injection, the drug molecules are distributed throughout the body and remain there for varying periods. The MRT represents the average time these drug molecules stay in the...
140
 01:14
Relative Frequency Histogram
5.5K
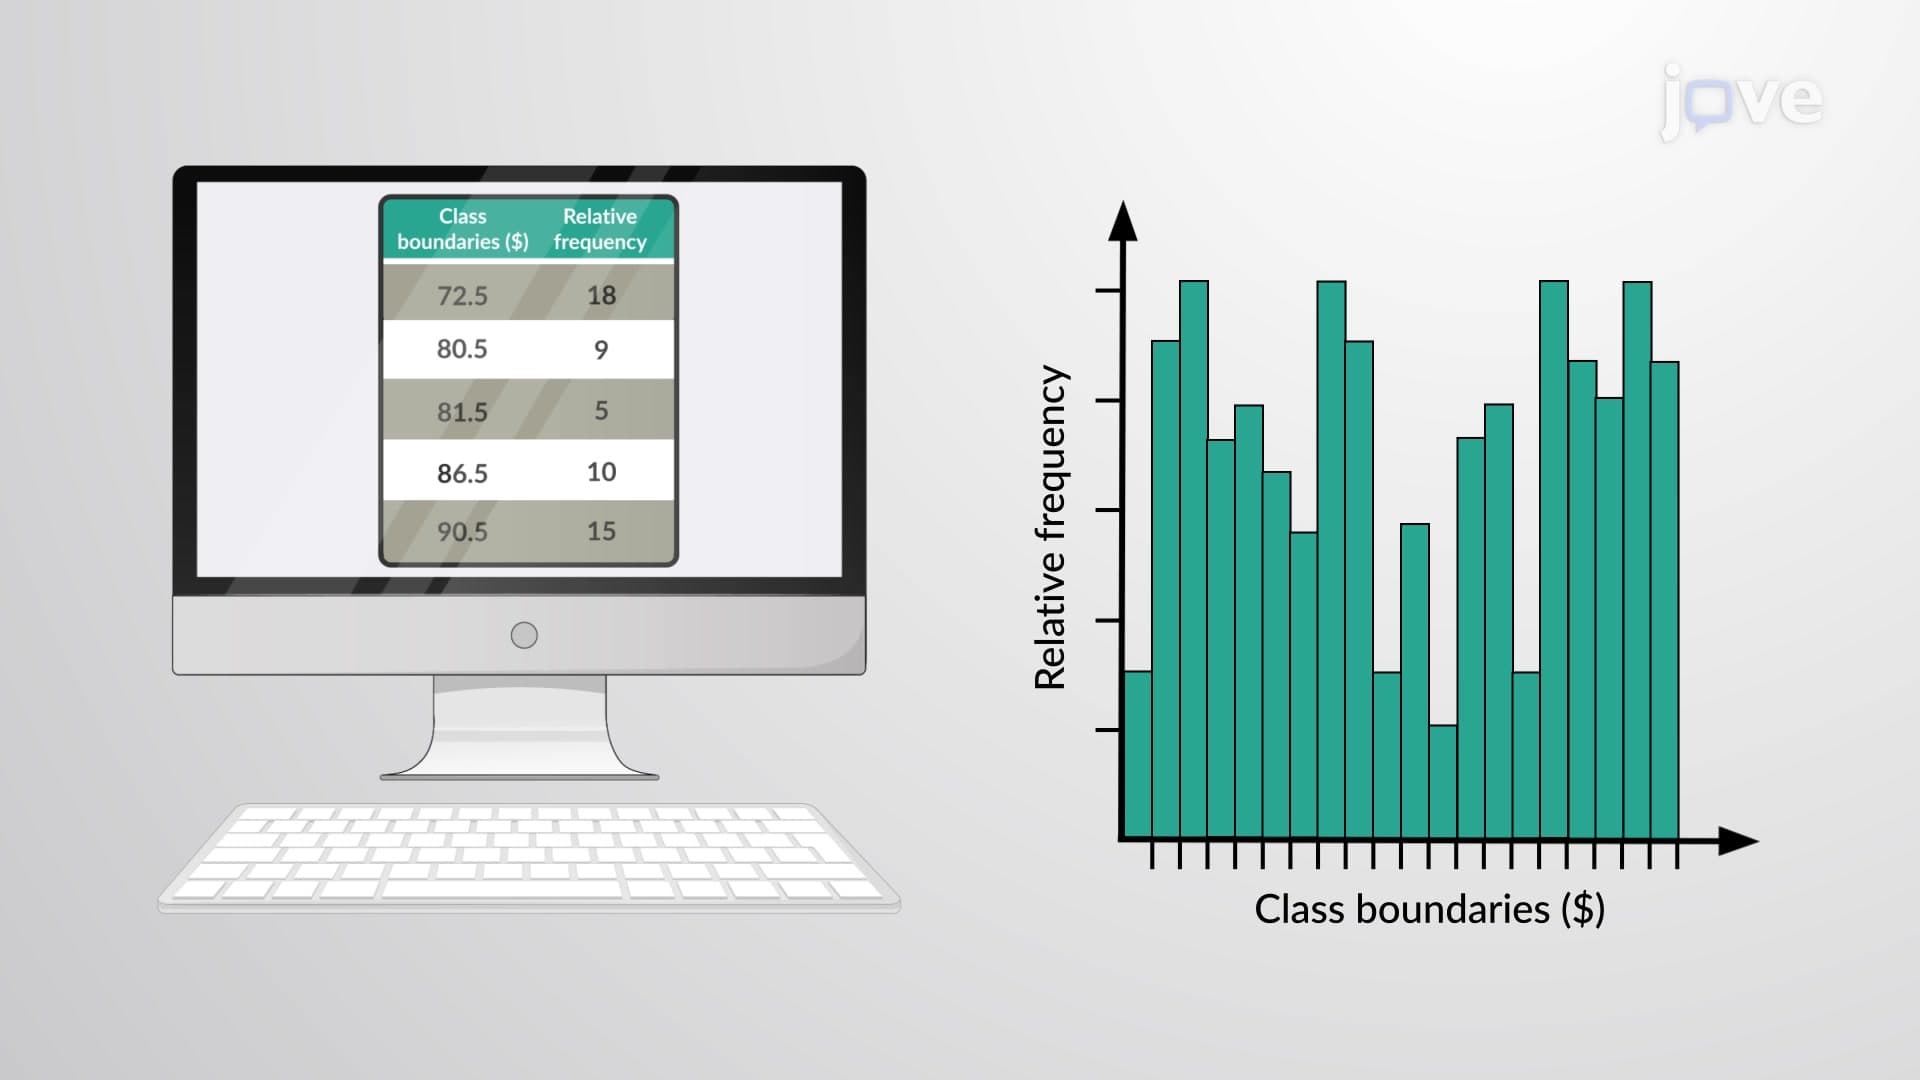
The relative frequency depicts the proportion of data points that have each value. The frequency tells the number of data points that have each value. Like the histogram, a relative frequency histogram also has the same shape with a horizontal scale (the x-axis), but the vertical scale (the y-axis) is marked with relative frequencies (percentages of the whole) instead of actual frequencies. A relative frequency histogram is a graphical representation of a frequency distribution where the...
5.5K
 00:55
Relative Frequency Distribution
10.9K
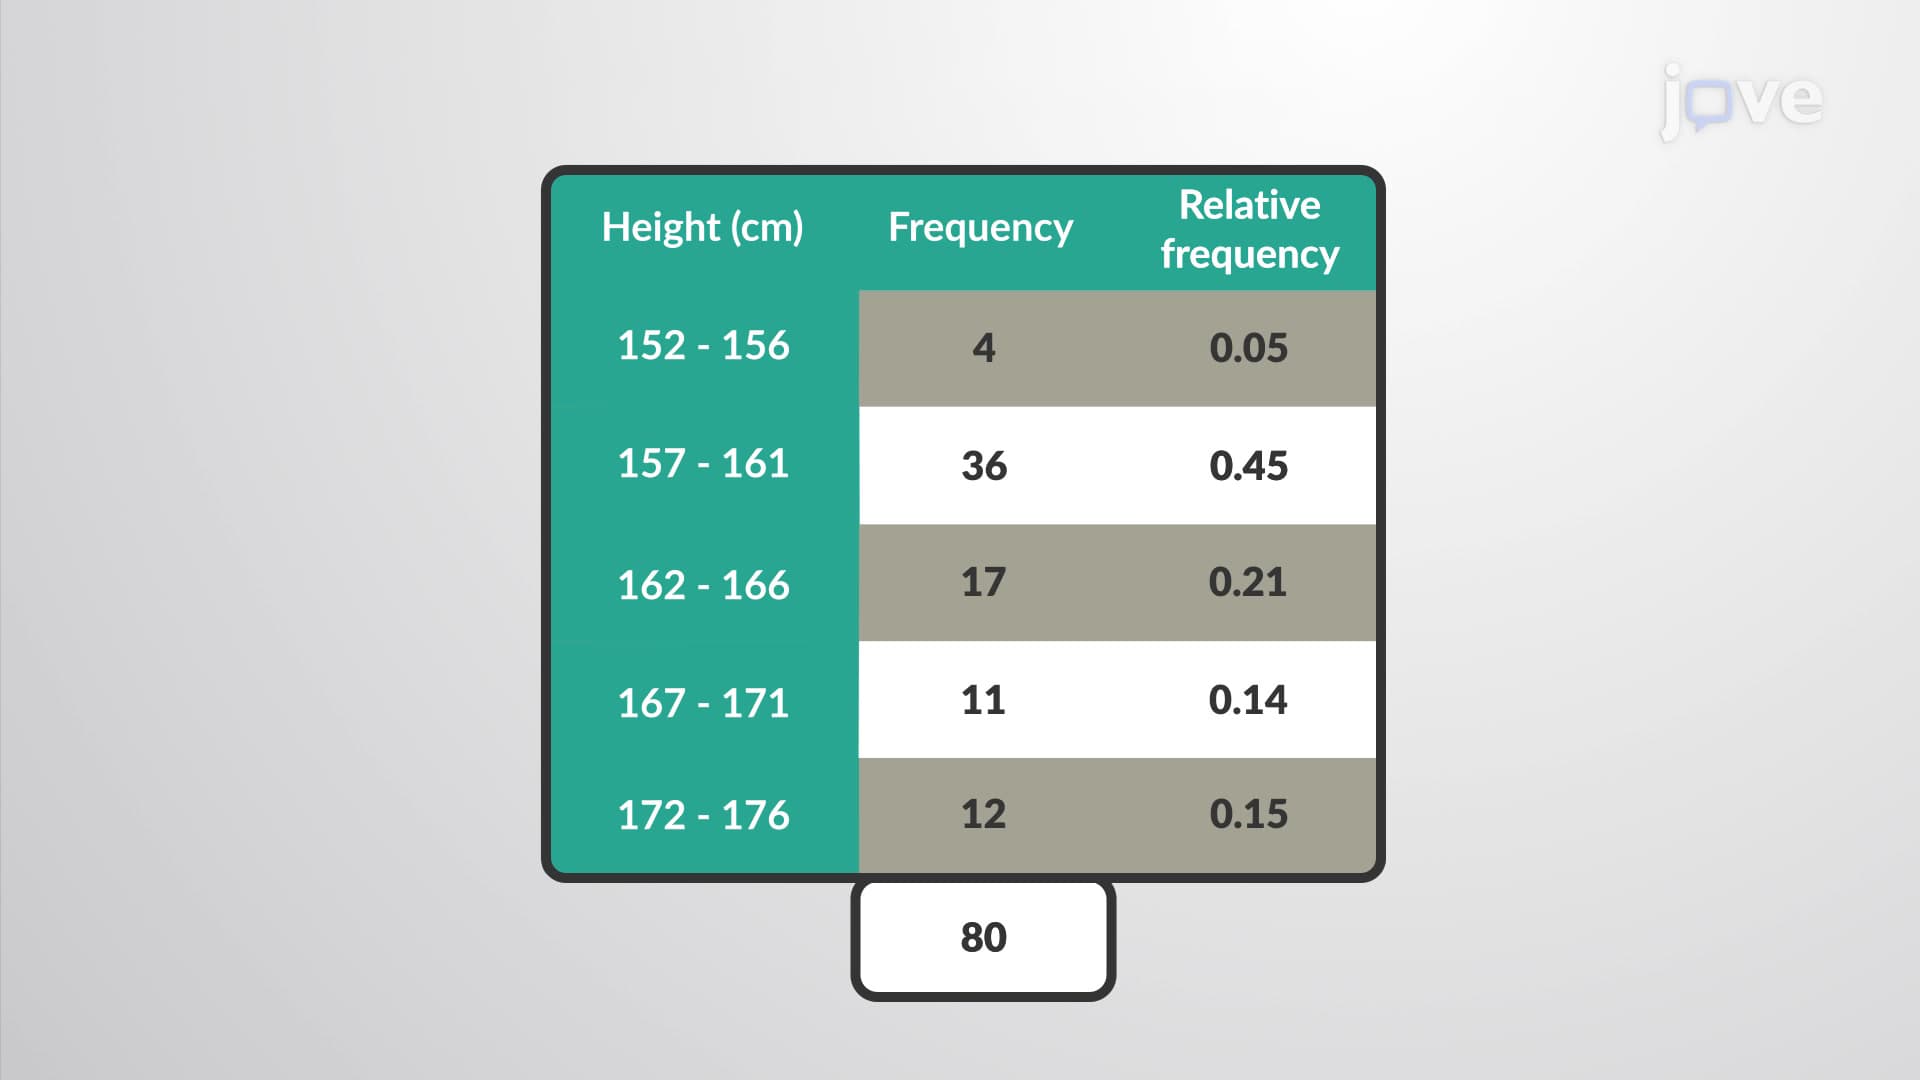
A relative frequency distribution is the proportion or fraction of times a value occurs in a data set. To find the relative frequencies, one can divide each frequency by the total number of data points in the sample. It is very similar to a regular frequency distribution, except that instead of reporting how many data values fall in a class, a relative frequency distribution reports the fraction of data values that fall in a class. These fractions or proportions are called relative frequencies...
10.9K
 01:21
Friedman Two-way Analysis of Variance by Ranks
194
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
194
 01:07
What is a Mode?
18.8K
The mode is one of the commonly used measures of a central tendency. It is defined as the most frequent value in a data set.
There can be more than one mode in a data set if multiple values have the same highest frequency. For instance, suppose that the Statistics exam scores of 20 students are: 50; 53; 59; 59; 63; 63; 72; 72; 72; 72; 72; 76; 78; 81; 83; 84; 84; 84; 90; 93. Here, the mode is 72, as it occurs most frequently, five times.
A data set with two modes is called bimodal. For example,...
18.8K