

在英格兰中部15个城市的每小时PM2.5趋势的趋势属性预测,应用优化的机器学习功能选择
1DWA Energy Limited, Lincoln, United Kingdom.
Journal of environmental management
|March 13, 2024

概括
这项研究使用机器学习预测每小时的颗粒物 (PM2.5),使用LASSO和支持矢量回归模型显示准确的短期预测 (0-3小时). 长期预测 (6-12小时) 需要进一步细化以提高准确性.
科学领域:
- 环境科学 环境科学
- 大气化学 大气化学
- 数据科学数据科学数据科学
背景情况:
- 从2018年到2022年,分析了英格兰中部15个城市的每小时颗粒物物质 (PM2.5) 趋势.
- 与2020-2022年相比,2018-2019年观察到较高的年平均PM2.5值和标准偏差.
- 城市背景和城市交通站点表现出一致的背景和峰值分布.
研究的目的:
- 为了证明从单变PM2.5数据的趋势属性的实用性,用于可靠的短期每小时预测.
- 为记录PM2.5趋势的区域差异提供洞察力.
- 开发和评估用于PM2.5预测的监督机器学习模型.
主要方法:
- 从前12小时的PM2.5数据中提取了15个趋势属性.
- 四个监督机器学习 (SML) 模型被用来预测PM2.5度,提前13小时.
- 采用了使用五个优化器和一个过拟合指示器的新功能选择程序.
主要成果:
- 拉索和支持向量回归模型获得了最佳性能,预测时间最长3小时 (t0-t+3) 的平均平均误差 (MAE) 为~1-3μg/m3.
- 这些模型没有显示过的迹象,正如一个基于交叉验证的指标所表明的那样.
- 未来6-12小时的预测显示MAE较高 (~3-4μg/m3),并倾向于低估极端PM2.5峰值.
结论:
- 提取的PM2.5趋势属性可以有效地用于短期每小时预测.
- 拉索和支向量回归为在不久的将来 (0-3小时) 提供可靠的PM2.5预测.
- 需要进一步改进模型,以提高PM2.5预测超过6小时的准确性.
相关概念视频
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:17
Precipitation and Co-precipitation
1.8K
Precipitation and coprecipitation methods can be used to separate a mixture of ions in a solution. In qualitative inorganic analysis, ions that form sparingly soluble precipitates with the same reagent are separated based on the differences in solubility products. For example, consider the separation of Cu(II) and Fe(II) ions by precipitation as insoluble sulfides. First, copper(II) sulfide is precipitated by the addition of acidic H2S, where the dissociation of H2S is suppressed. Adding H2S...
1.8K
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:12
Precipitation Processes
446
The experimental conditions in a gravimetric analysis should be optimized to maximize the particle size and purity of the obtained precipitate. Ideally, the concentration of the precipitating reagent should be low with effective stirring to maintain low relative supersaturation for the growth of large crystals. In homogeneous precipitation, the precipitant is slowly generated by a chemical reaction in the solution to avoid local reagent excesses. For example, urea decomposes gradually to...
446
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:07
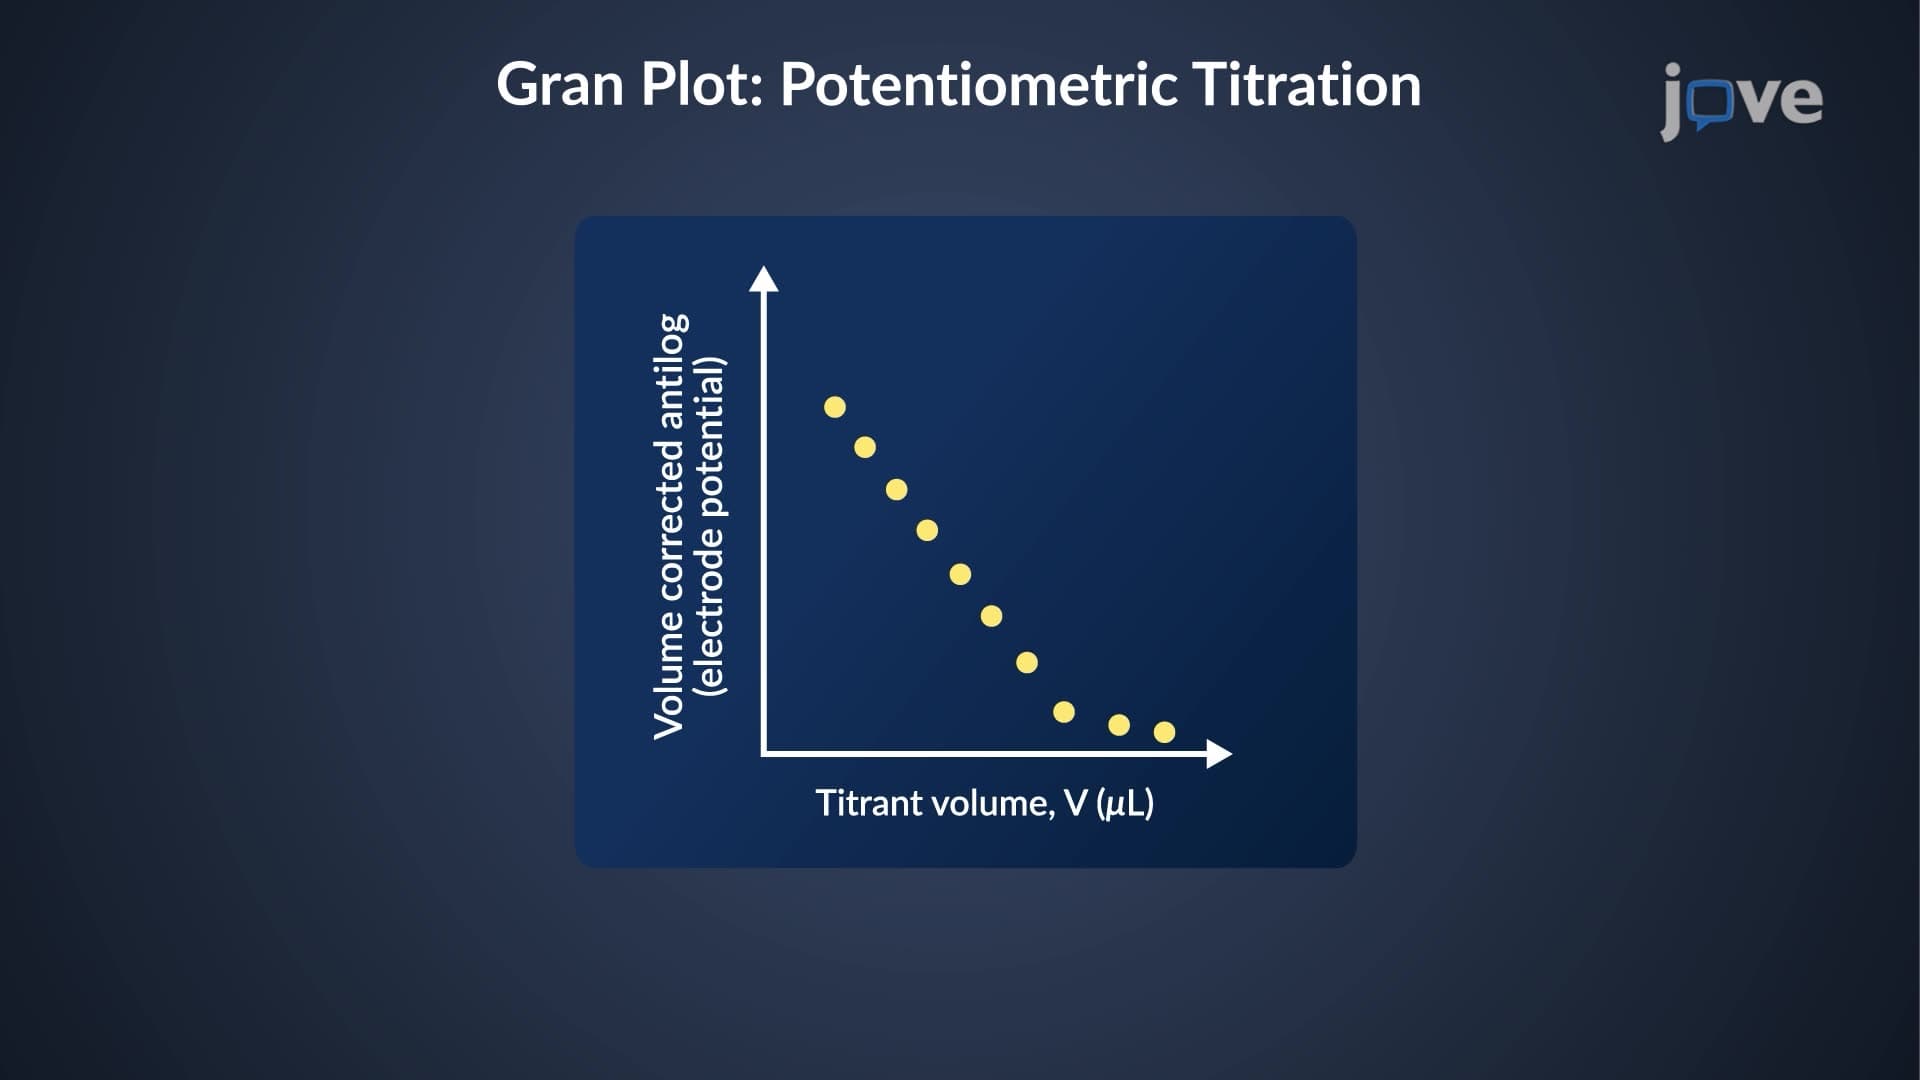
End Point Prediction: Gran Plot
322
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
322