
贝叶斯估计的Kullback-Leibler分歧的分类系统使用Dirichlet先验的混合物
Francesco Camaglia1, Ilya Nemenman2, Thierry Mora1
1Laboratoire de physique de l'École normale supérieure, CNRS, PSL University, Sorbonne Université and Université de Paris, 75005 Paris, France.
Physical review. E
|March 16, 2024

概括
我们开发了一个贝叶斯估计器用于统计差异,比如库尔巴克-莱布勒差异,以准确地比较复杂过程中的数据分布,即使样本大小小.
科学领域:
- 计算统计学 计算统计学
- 数据分析 数据分析
- 可能性理论概率理论.
背景情况:
- 从复杂的过程中比较数据分布在生物学,工程学和经济学中至关重要.
- 统计差异量化分布之间的差异,但经验估计是具有挑战性的,特别是小或稀疏的数据集.
- 现有的方法往往无法准确地估计对具有许多类别的离散计数数据的差异.
研究的目的:
- 开发一个强大的贝叶斯估计器,用于两个概率分布之间的库尔巴克-莱布勒分歧.
- 为了扩展这个贝叶斯的方法来估计二次赫林格分歧.
- 与现有技术相比,评估拟议的估计器的性能.
主要方法:
- 开发了一个贝叶斯估计器,利用在概率分布上的迪里克莱特先验的混合物.
- 将估计器应用于两个不同的例子:来自迪里克莱特分布的概率和来自马尔科夫链的随机字符串.
- 扩展了方法,以适应二次赫林格分歧.
主要成果:
- 为库尔巴克-莱布勒分歧提出的贝叶斯估计器表现出卓越的性能.
- 平方赫林格分歧的扩展估计器也超过了传统方法.
- 对于具有更多类别和更高分歧值的数据集,观察到更好的准确性.
结论:
- 贝叶斯方法提供了一个更可靠的方法来估计从有限的分类样本的统计差异.
- 这种技术比实证方法具有显著的优势,特别是对于小样本大小和高维数据.
- 开发的估计器增强了识别不同科学领域复杂数据分布之间的相似性和差异的能力.

相关概念视频
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
491
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
491
 01:15
Binomial Probability Distribution
10.7K
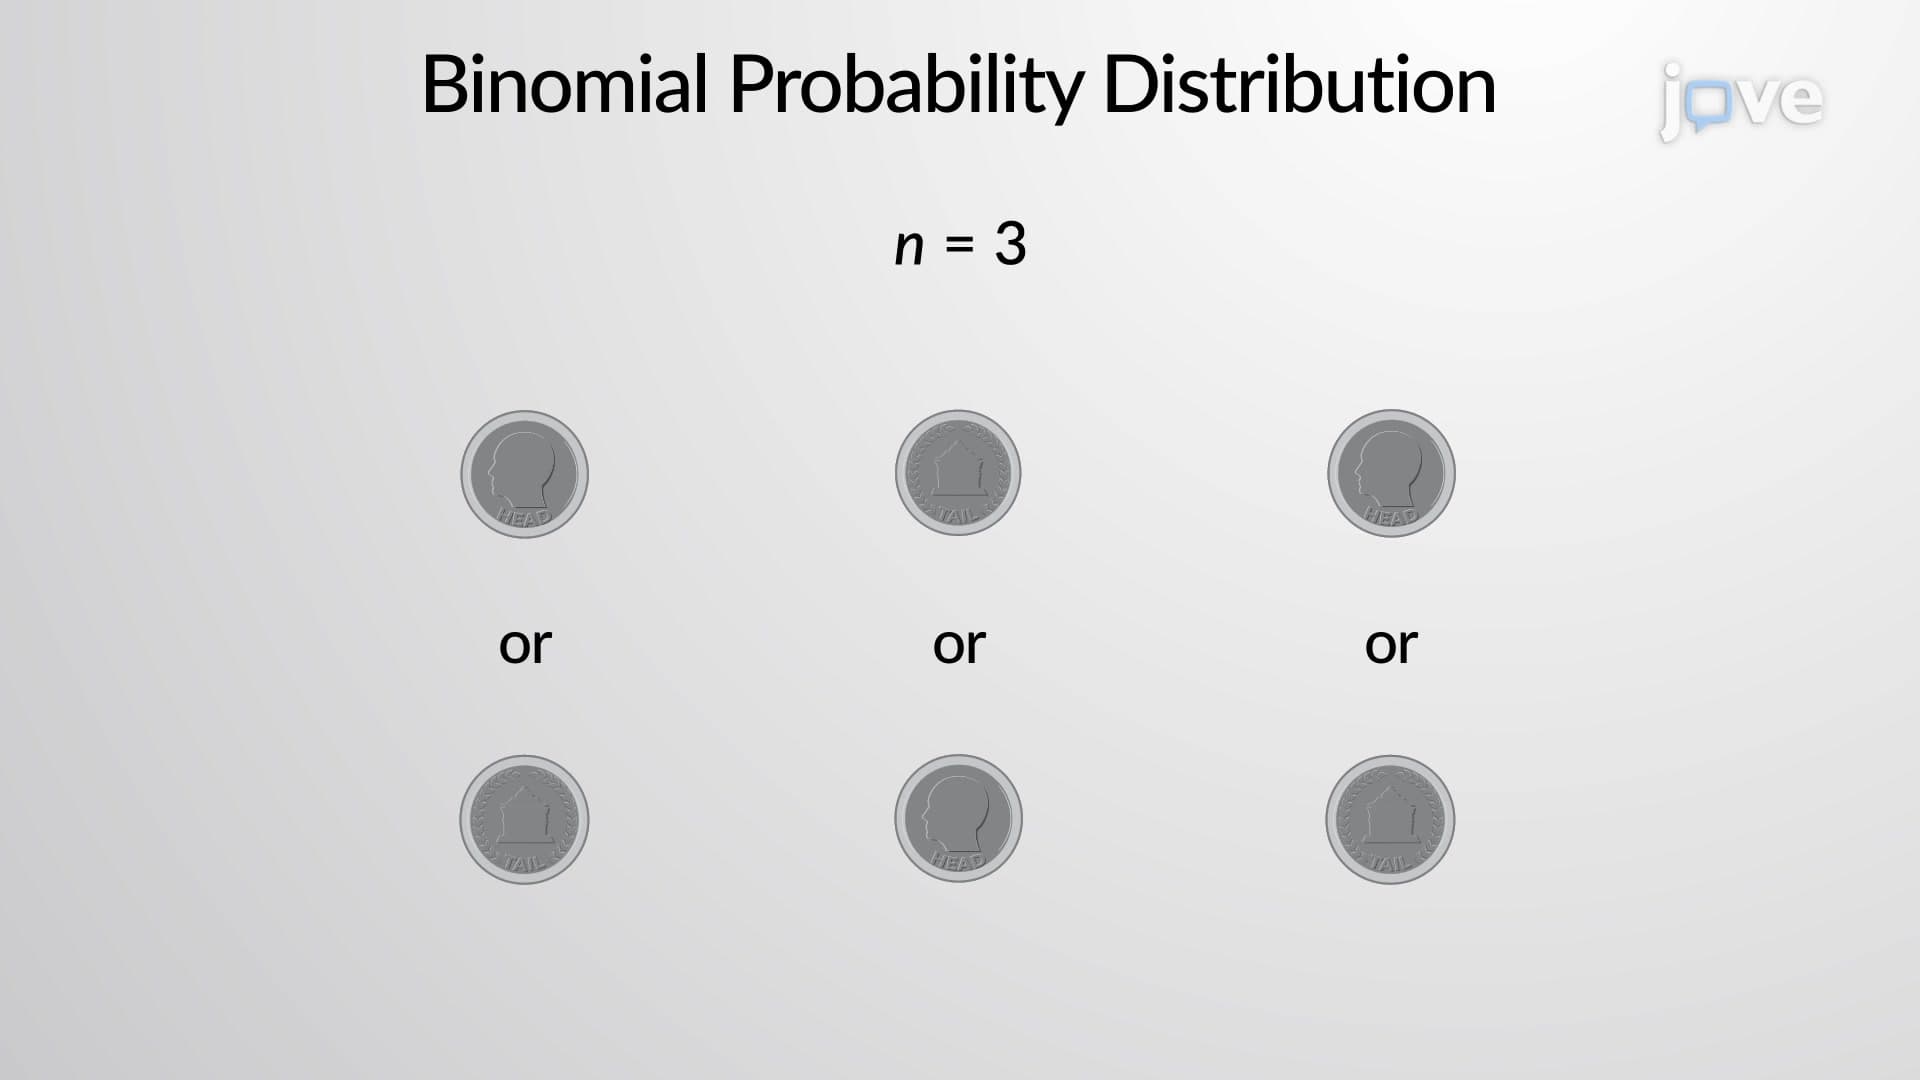
A binomial distribution is a probability distribution for a procedure with a fixed number of trials, where each trial can have only two outcomes.
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
10.7K
 01:26
Distributions to Estimate Population Parameter
4.1K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
4.1K
 01:32
Probability Distributions
7.0K
The probability of a random variable x is the likelihood of its occurrence. A probability distribution represents the probabilities of a random variable using a formula, graph, or table. There are two types of probability distribution– discrete probability distribution and continuous probability distribution.
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
7.0K
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
69
Pharmacokinetic models are mathematical constructs that represent and predict the time course of drug concentrations in the body, providing meaningful pharmacokinetic parameters. These models are categorized into compartment, physiological, and distributed parameter models.
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
69
 01:11
How Data are Classified: Categorical Data
32.7K
A variable, usually notated by capital letters such as X and Y, is a characteristic or measurement that can be determined for each member of a population. Data are the actual values of variables. They may be numbers, or they may be words. Datum is a single value.
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
32.7K