从嵌入式中提取交叉刻板印象:开发和验证灵活交叉刻板印象提取程序
Tessa E S Charlesworth1, Kshitish Ghate2, Aylin Caliskan3
1Kellogg School of Management, Northwestern University, Evanston, IL 60208, USA.
PNAS nexus
|March 20, 2024

概括
本研究引入了灵活交叉刻板印象提取 (FISE) 来分析性别,种族和阶级等社会身份如何在日常语言中交叉. 它揭示了占主导地位的刻板印象和相关的特征,突出了大型文本体中的偏见.
科学领域:
- 计算社会科学 计算社会科学
- 自然语言处理自然语言处理.
- 社会语言学 社会语言学
背景情况:
- 性别,种族和阶级等社会认同不是孤立地经历的,而是相互交叉的.
- 了解这些交叉点如何以大规模的语言表现,对于社会科学研究至关重要.
- 现有的方法很难在庞大的文本数据中有效量化交叉刻板印象.
研究的目的:
- 开发和验证一种新的计算方法,灵活的交叉刻板印象提取 (FISE),用于分析日常语言中的交叉刻板印象.
- 量化与各种性别,种族和阶级的交叉点相关的刻板印象的频率和性质.
- 揭示关于社会群体身份的语言使用中的偏见和模式.
主要方法:
- 灵活交叉刻板印象提取 (FISE) 程序的开发.
- 将FISE应用于词嵌入 (GloVe,BERT) 训练在大型英语互联网文本大体上.
- 根据地面真相验证职业人口统计学和特征形容词关联的分析.
主要成果:
- FISE成功地与职业人口统计学保持一致,验证了其方法.
- 表现出显著的人类中心主义和种族中心主义,其中"白人+男性"与59%的特征相关,而"黑人+女性"与5%相关.
- 交叉群体,特别是那些涉及"富人"的群体,与更频繁的,积极的,温暖的,有能力的和主导的特征有关.
结论:
- FISE提供了一种透明和有效的工具,用于量化大型文本体中的交叉刻板印象.
- 这些发现揭示了普遍的偏见,并突出了基于交叉的社会身份的特质的差异性归因.
- 这项工作为未来研究交叉身份及其在语言中的新兴特性建立了基础设施.
相关概念视频
 02:16
Stereotype Content Model
14.7K
The Stereotype Content Model (SCM) was first proposed by Susan Fiske and her colleagues (Fiske, Cuddy, Glick & Xu, 2002; see also Fiske, 2012 and Fiske, 2017). The SCM specifies that when someone encounters a new group, they will stereotype them based on two metrics: warmth—or that group’s perceived intent, and how likely they are to provide help or inflict harm—and competence—or their ability to carry out that objective. Depending on the warmth-competence...
14.7K
 00:56
Extraction: Advanced Methods
446
Metal ions can be separated from one another by complexation with organic ligands–the chelating agent– to form uncharged chelates. Here, the chelating agent must contain hydrophobic groups and behave as a weak acid, losing a proton to bind with the metal. Since most organic ligands used in this process are insoluble or undergo oxidation in the aqueous phase, the chelating agent is initially added to the organic phase and extracted into the aqueous phase. The metal-ligand complex is...
446
 02:09
Stereotype Threat and Self-fulfilling Prophecies
37.6K
When we hold a stereotype about a person, we have expectations that he or she will fulfill that stereotype. A self-fulfilling prophecy is an expectation held by a person that alters his or her behavior in a way that tends to make it true. When we hold stereotypes about a person, we tend to treat the person according to our expectations. This treatment can influence the person to act according to our stereotypic expectations, thus confirming our stereotypic beliefs. Research by Rosenthal and...
37.6K
 02:55
Stereotypes, Prejudice, and Discrimination
90.2K
Humans are very diverse and although we share many similarities, we also have many differences. The social groups we belong to help form our identities (Tajfel, 1974). These differences may be difficult for some people to reconcile, which may lead to prejudice toward people who are different. Prejudice is a negative attitude and feeling toward an individual based solely on one’s membership in a particular social group (Allport, 1954; Brown, 2010). Prejudice is common against people who...
90.2K
 01:14
Extraction: Partition and Distribution Coefficients
2.4K
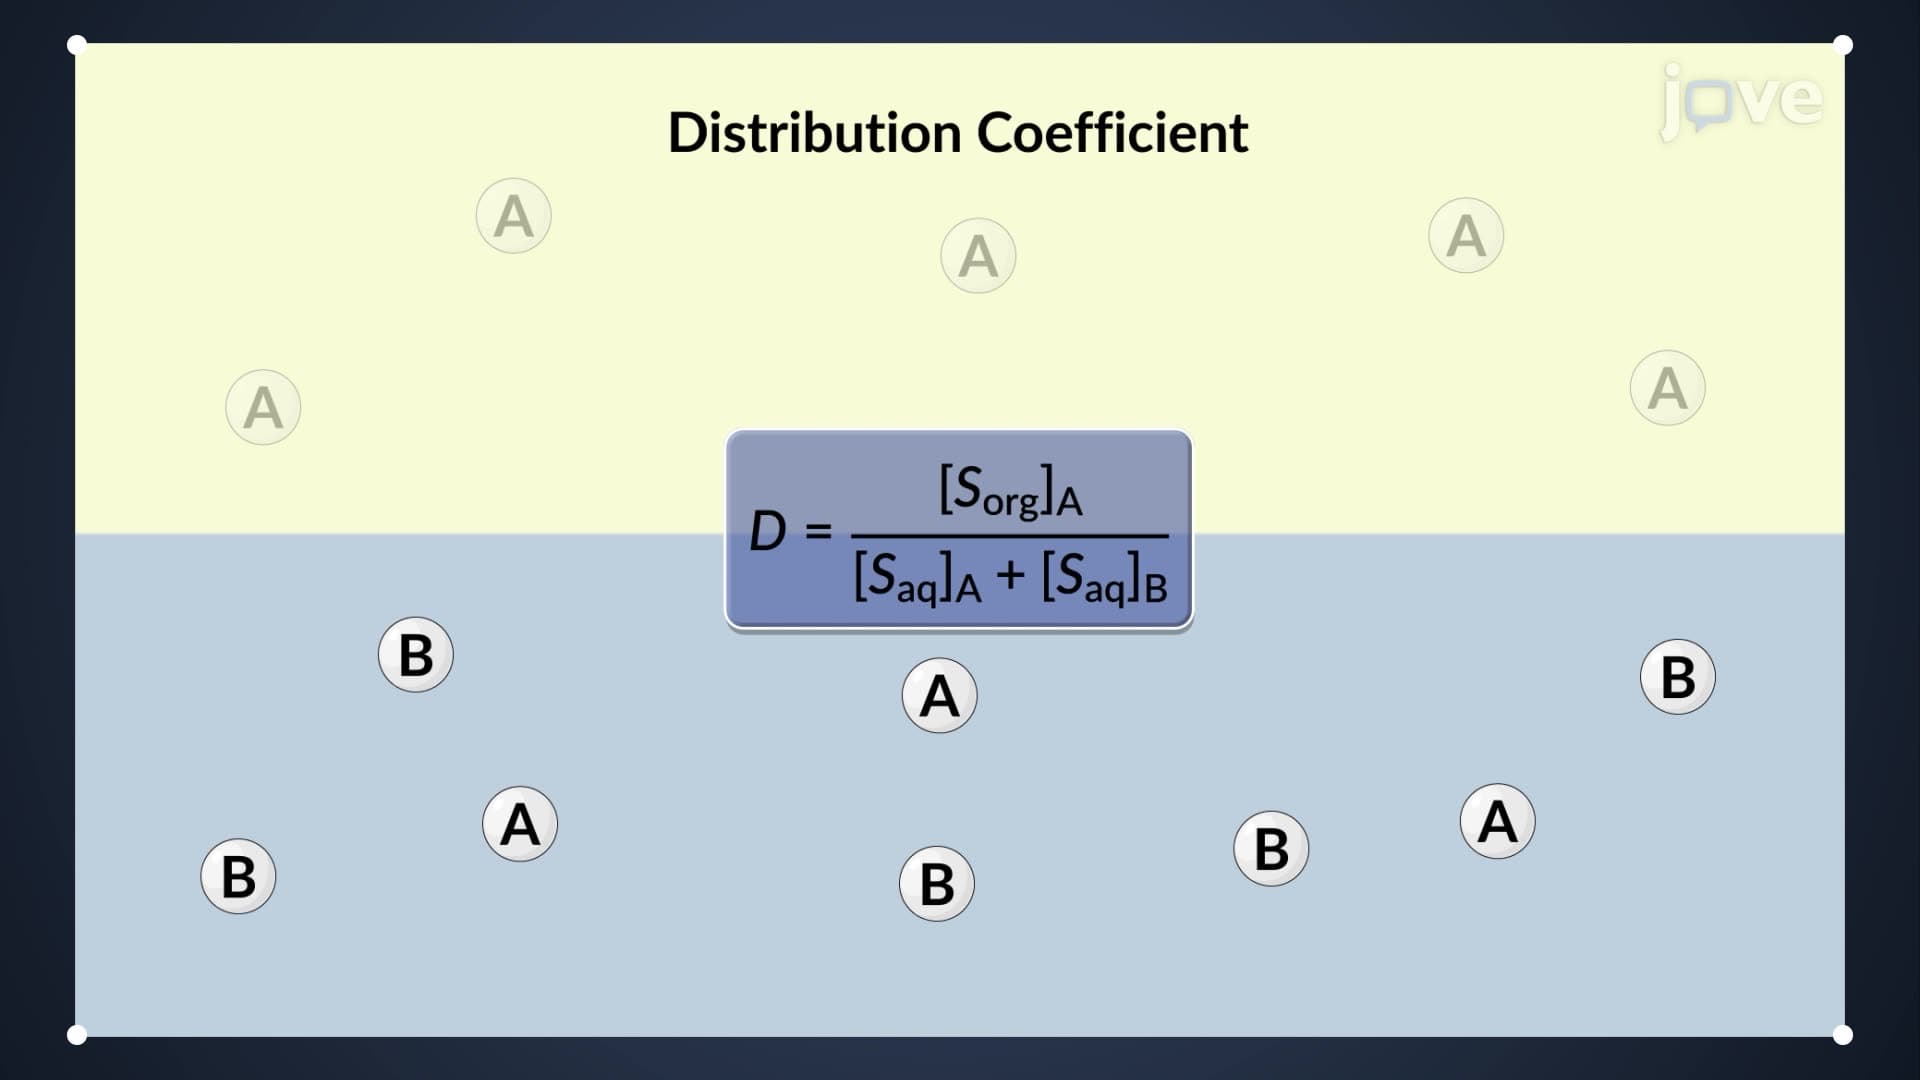
The distribution law or Nernst's distribution law is the law that governs the distribution of a solute between two immiscible solvents. This law, also known as the partition law, states that if a solute is added to the mixture of two immiscible solvents at a constant temperature, the solute is distributed between the two solvents in such a way that the ratio of solute concentrations in the solvents remains constant at equilibrium.
For extracting a solute from an aqueous phase into an...
For extracting a solute from an aqueous phase into an...
2.4K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.6K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.6K