基于美国地区和STEM学科的学术职位性别差异的比较分析
Danielle J Galvin1, Susan C Anderson1, Chelsi J Marolf1
1Department of Biology, University of South Dakota, Vermillion, South Dakota, United States of America.
PloS one
|March 20, 2024

概括
一项对20,000多个学术科学,技术,工程和数学 (STEM) 职位的研究揭示了性别差距的区域差异. 山区拥有最少的女性任职职位,而东北中部和太平洋地区拥有最多的女性.
科学领域:
- 科学社会学科学社会学
- 高等教育研究 高等教育研究
- 在STEM中的性别研究.
背景情况:
- 尽管美国劳动力在性别平等方面取得了进展,但在学术科学,技术,工程和数学 (STEM) 职位上仍然存在显著的性别差距.
- 这种差异在专职学术角色中最为明显,这表明随着女性在学术职业阶段的进步,差距越来越大.
- 美国各地政策,文化和政治的区域差异表明,STEM学术界的性别差距可能存在地理差异.
研究的目的:
- 调查地理区域是否以及如何影响女性在大学STEM学术位中的比例.
- 评估全国范围内女性在教师和终身职位STEM角色中的代表性的区域差异.
主要方法:
- 分析了美国各地大学STEM部门的2万多个教师和终身职位.
- 美国不同地理区域中STEM学术角色中女性比例的比较.
主要成果:
- 在所有地区,男性在任期和教师STEM职位上都占比较高.
- 观察到显著的区域差异:山区的女性占职位比例最低.
- 东北中部和太平洋地区的女性占STEM职位比例最高.
结论:
- 地理区域是美国学术STEM领域内性别分布的一个因素.
- 国家/地方政策,区域代表和指导的差异可能导致观察到的区域差异.
- 了解性别平等的区域促进者对于促进STEM学术界女性包容性机会至关重要.
相关概念视频
 01:30
Socioemotional Experience and Gender Development
29
Social-emotional experiences and cultural influences play significant roles in shaping gender development. During middle childhood, from ages 6 to 11, peer groups become dominant in reinforcing gender norms. Children in this age group often align with same-gender peer groups, which actively encourage behaviors that conform to traditional gender roles. For instance, boys may be discouraged from engaging in activities perceived as feminine, reinforcing culturally dictated norms about masculinity...
29
 02:16
Stereotype Content Model
14.7K
The Stereotype Content Model (SCM) was first proposed by Susan Fiske and her colleagues (Fiske, Cuddy, Glick & Xu, 2002; see also Fiske, 2012 and Fiske, 2017). The SCM specifies that when someone encounters a new group, they will stereotype them based on two metrics: warmth—or that group’s perceived intent, and how likely they are to provide help or inflict harm—and competence—or their ability to carry out that objective. Depending on the warmth-competence...
14.7K
 01:07
Multiple Bar Graph
5.1K
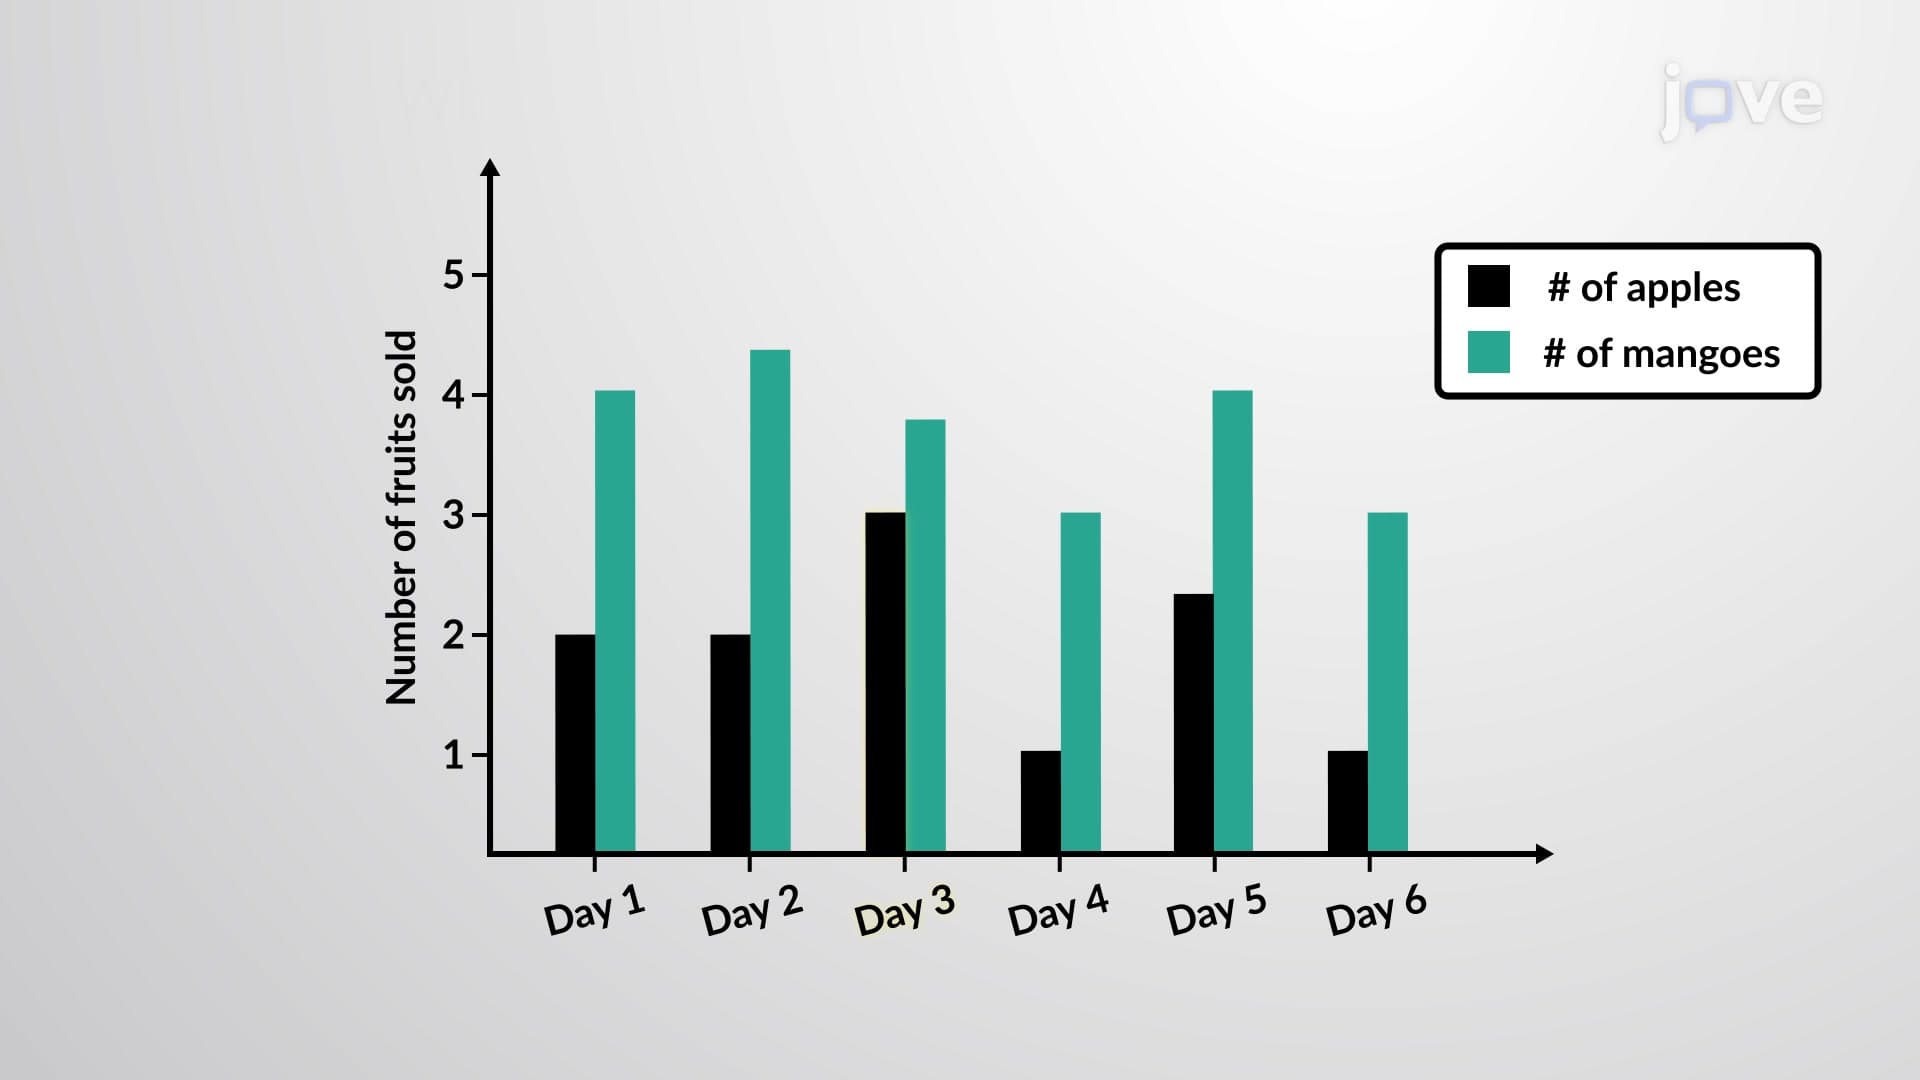
As the name suggests, a multiple bar graph is the same as a bar graph but has multiple bars to depict relationships between different data values. One can include as many parameters as possible. However, each parameter must have the same unit of measurement.
Each bar or column in the multiple bar graph represents a data value. These graphs are used primarily in interrelating two or more sets of data. The categories of different kinds of data are listed along the horizontal or x-axis, whereas...
Each bar or column in the multiple bar graph represents a data value. These graphs are used primarily in interrelating two or more sets of data. The categories of different kinds of data are listed along the horizontal or x-axis, whereas...
5.1K
 02:55
Stereotypes, Prejudice, and Discrimination
90.2K
Humans are very diverse and although we share many similarities, we also have many differences. The social groups we belong to help form our identities (Tajfel, 1974). These differences may be difficult for some people to reconcile, which may lead to prejudice toward people who are different. Prejudice is a negative attitude and feeling toward an individual based solely on one’s membership in a particular social group (Allport, 1954; Brown, 2010). Prejudice is common against people who...
90.2K
 01:14
Wilcoxon Signed-Ranks Test for Median of Single Population
127
The Wilcoxon signed-rank test for the median of a single population is a nonparametric test used to evaluate whether the median of a population differs from a specified value. Unlike parametric tests, it does not require data to follow a normal distribution, making it suitable for non-normal or small samples. The test begins by calculating the difference (d) between each observation and the hypothesized median. The absolute values of these differences are ranked in ascending order, with ties...
127
 01:21
Friedman Two-way Analysis of Variance by Ranks
194
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
194