

使用带有条件随机字段的图形卷积网络进行个性化驱动基因预测
Pi-Jing Wei1, An-Dong Zhu1, Ruifen Cao2
1Information Materials and Intelligent Sensing Laboratory of Anhui Province, Institutes of Physical Science and Information Technology, Anhui University, 111 Jiulong Road, Hefei 230601, China.
Biology
|March 27, 2024

概括
鉴定个别癌症驱动基因是由于瘤异质性至关重要的. 新的PDGCN方法有效地整合了多omics数据和网络特征,以精确定位罕见和常见的驱动基因,改进个性化癌症研究.
科学领域:
- 基因组学就是基因组学.
- 计算生物学 计算生物学
- 癌症研究 癌症研究
背景情况:
- 癌症是一种由遗传变异驱动的异质性疾病.
- 目前的驱动基因发现方法主要集中在人口层面的分析上.
- 发现个体水平的驱动基因是必不可少的,但由于高瘤异质性而具有挑战性.
研究的目的:
- 开发一种高效的计算方法来识别个体水平的癌症驱动基因.
- 改进现有的癌症患者驱动基因发现方法.
主要方法:
- 提出了PDGCN (使用图形卷积网络识别患者级驱动基因) 方法.
- 综合多omics数据 (突变,表达,甲基化,副本数) 和基因特征.
- 使用Node2vec进行网络结构提取,并使用GCN与CRF进行预测.
主要成果:
- 在癌症基因组图谱 (TCGA) 的上皮层癌症 (ACC) 和染色恐惧症 (KICH) 数据集上,PDGCN表现出卓越的性能.
- 成功识别了经常发生突变的,罕见的候选基因和新的生物标志物驱动基因.
- 检测到的基因在生存和丰富分析中显示出显著的结果,验证了它们的重要性.
结论:
- PDGCN是识别个体级驱动基因的有效工具.
- 该方法通过利用多omics和网络数据来推进个性化癌症驱动基因发现.
- 研究结果强调了发现新生物标志物和治疗点的潜力.
相关概念视频
 01:07
End Point Prediction: Gran Plot
321
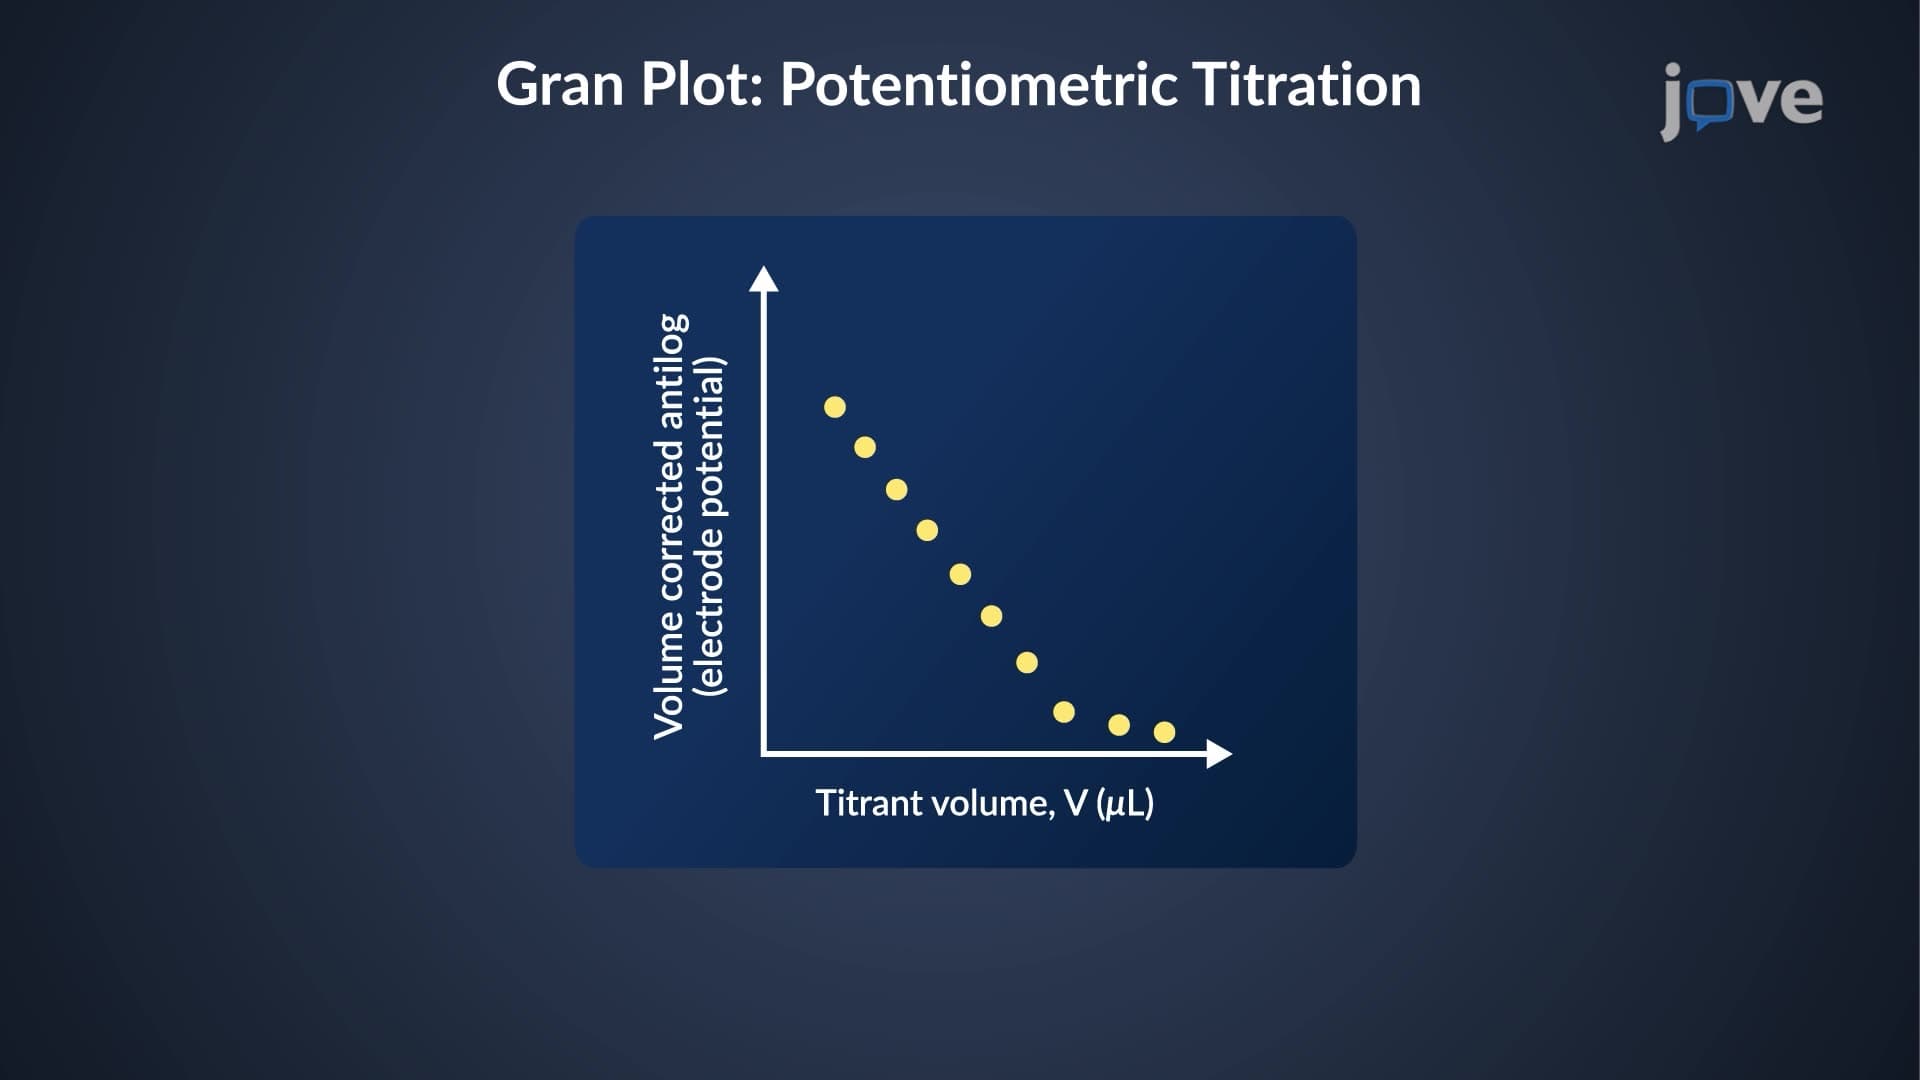
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
321
 02:07
Improving Translational Accuracy
10.3K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
10.3K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:25
Neural Circuits
1.2K
Neural circuits and neuronal pools are two of the main structures found in the nervous system. Neural circuits are networks of neurons that work together to carry out a specific task or process. They consist of interconnected neurons and glial cells, which provide structural and metabolic support.
Neuronal pools are collections of nerve cells with similar functions and interact through chemical and electrical signals. These pools include both interneurons (the central neural circuit nodes that...
Neuronal pools are collections of nerve cells with similar functions and interact through chemical and electrical signals. These pools include both interneurons (the central neural circuit nodes that...
1.2K
 03:33
Genetic Drift
39.7K
Natural selection—probably the most well-known evolutionary mechanism—increases the prevalence of traits that enhance survival and reproduction. However, evolution does not merely propagate favorable traits, nor does it always benefit populations.
39.7K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K