一条通往更简单模型的道路从噪音开始
Lesia Semenova1, Harry Chen1, Ronald Parr1
1Department of Computer Science, Duke University.
Advances in neural information processing systems
|April 5, 2024

概括
更杂的数据集会导致更大的Rashomon集,其中许多模型表现同样好. 这解释了为什么更简单的模型往往与杂杂数据上的复杂模型相匹配,影响医疗保健和刑事司法等领域.
科学领域:
- 机器学习 机器学习
- 数据科学数据科学数据科学
- 统计建模 统计建模
背景情况:
- 拉什蒙集包括在数据集上具有相似性能的模型.
- 拉沙蒙比率量化了假设空间内的属于拉沙蒙集的模型比例.
- 经常在各种领域的表格数据中观察到较大的Rashomon比率,包括刑事司法,医疗保健和金融,这引发了关于模型简单性与复杂性的问题.
研究的目的:
- 调查大拉沙蒙比率流行的根本原因.
- 提出一个机制,将数据生成和分析师的选择与Rashomon比率大小联系起来.
- 解释为什么更简单的模型可以在某些数据集上实现与复杂模型相比的准确性.
主要方法:
- 在模型培训期间分析数据生成过程和分析师决策之间的相互作用.
- 通过经验分析证明数据集噪声对Rashomon比率大小的影响.
- 引入和研究"模式多样性"作为衡量Rashomon集合内预测差异的指标.
主要成果:
- 更杂的数据集显然会导致更大的Rashomon比率.
- 图案多样性倾向于随着标签噪声的增加而增加,与较大的Rashomon集相关联.
- 拟议的机制提供了对数据特征和模型性能变化之间的关系的洞察.
结论:
- 数据噪声和分析师的选择显著影响了Rashomon集的大小.
- 了解这些因素有助于解释更简单的模型在复杂,杂的数据集上的有效性.
- 这些发现对应用机器学习中的模型选择和解释有影响.
相关概念视频
 01:20
Random and Systematic Errors
10.9K
Scientists always try their best to record measurements with the utmost accuracy and precision. However, sometimes errors do occur. These errors can be random or systematic. Random errors are observed due to the inconsistency or fluctuation in the measurement process, or variations in the quantity itself that is being measured. Such errors fluctuate from being greater than or less than the true value in repeated measurements. Consider a scientist measuring the length of an earthworm using a...
10.9K
 01:09
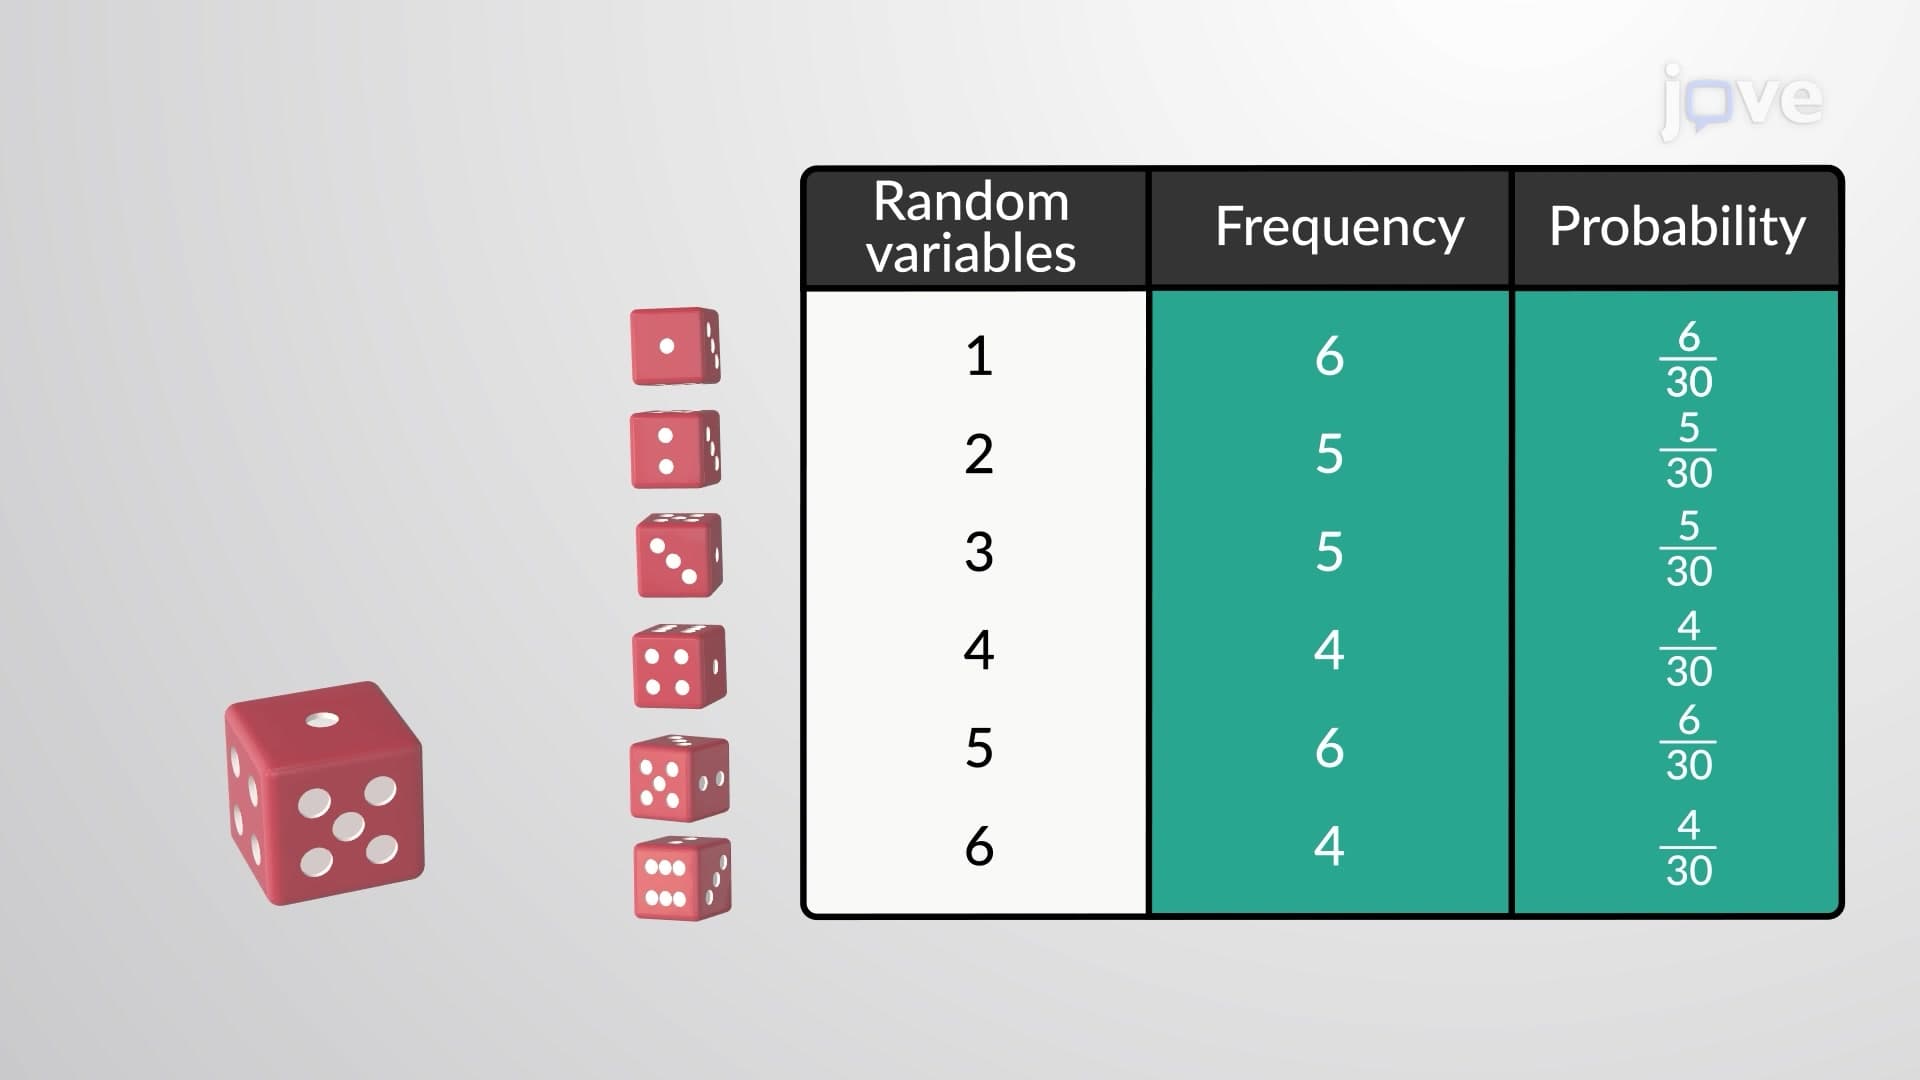
Random Variables
11.8K
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
11.8K
 01:13
Randomized Experiments
6.9K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.9K
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
53
Mechanistic models play a crucial role in algorithms for numerical problem-solving, particularly in nonlinear mixed effects modeling (NMEM). These models aim to minimize specific objective functions by evaluating various parameter estimates, leading to the development of systematic algorithms. In some cases, linearization techniques approximate the model using linear equations.
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
53
 00:59
Propagation of Uncertainty from Random Error
681
An experiment often consists of more than a single step. In this case, measurements at each step give rise to uncertainty. Because the measurements occur in successive steps, the uncertainty in one step necessarily contributes to that in the subsequent step. As we perform statistical analysis on these types of experiments, we must learn to account for the propagation of uncertainty from one step to the next. The propagation of uncertainty depends on the type of arithmetic operation performed on...
681
 01:04
Random Error
882
Random or indeterminate errors originate from various uncontrollable variables, such as variations in environmental conditions, instrument imperfections, or the inherent variability of the phenomena being measured. Usually, these errors cannot be predicted, estimated, or characterized because their direction and magnitude often vary in magnitude and direction even during consecutive measurements. As a result, they are difficult to eliminate. However, the aggregate effect of these errors can be...
882