

多层网络中节点标签的可解释性预测:组织中营业额预测的案例研究
1HUN-REN-PE Complex Systems Monitoring Research Group, University of Pannonia, Veszprém, Hungary. gadar.laszlo@mk.uni-pannon.hu.
Scientific reports
|April 19, 2024

概括
预测员工流动对于企业来说至关重要. 这项研究使用社交网络分析和机器学习准确预测营业额,同时保持模型可解释性,提供对员工保留因素的见解.
科学领域:
- 社交网络分析 社交网络分析
- 机器学习 机器学习
- 组织行为 组织行为
背景情况:
- 员工流动对组织构成重大挑战.
- 决策支持工具通常依赖于网络模型来获得洞察力.
- 了解员工 attrition 的驱动因素对于保留策略至关重要.
研究的目的:
- 开发一个准确的员工流动率预测模型.
- 确保分类模型的可解释性.
- 识别和解释员工流动背后的各种原因.
主要方法:
- 利用多层社交网络数据,包括协作和绩效感知.
- 使用特征工程和决策树来识别关键的预测变量.
- 应用随机森林与SMOTE用于预测和SHAP值用于解释性.
主要成果:
- 确定了对员工周转率具有高预测能力的关键变量.
- 量化了不同因素对个人营业额预测的贡献.
- 基于SHAP值的集群解释,以揭示戒烟的细微原因.
结论:
- 使用社交网络数据可以实现准确的员工流动率预测.
- SHAP值提高了复杂预测模型的可解释性.
- 该方法为影响员工留守的组织因素提供了可操作的见解.
更多相关视频
 06:37
Author Spotlight: Addressing Technical and Subjective Challenges in Measuring Classroom Attention
Published on: December 15, 2023
3.7K
 12:27
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
7.0K
相关概念视频
 01:19
Survival Tree
84
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
84
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:07
End Point Prediction: Gran Plot
318
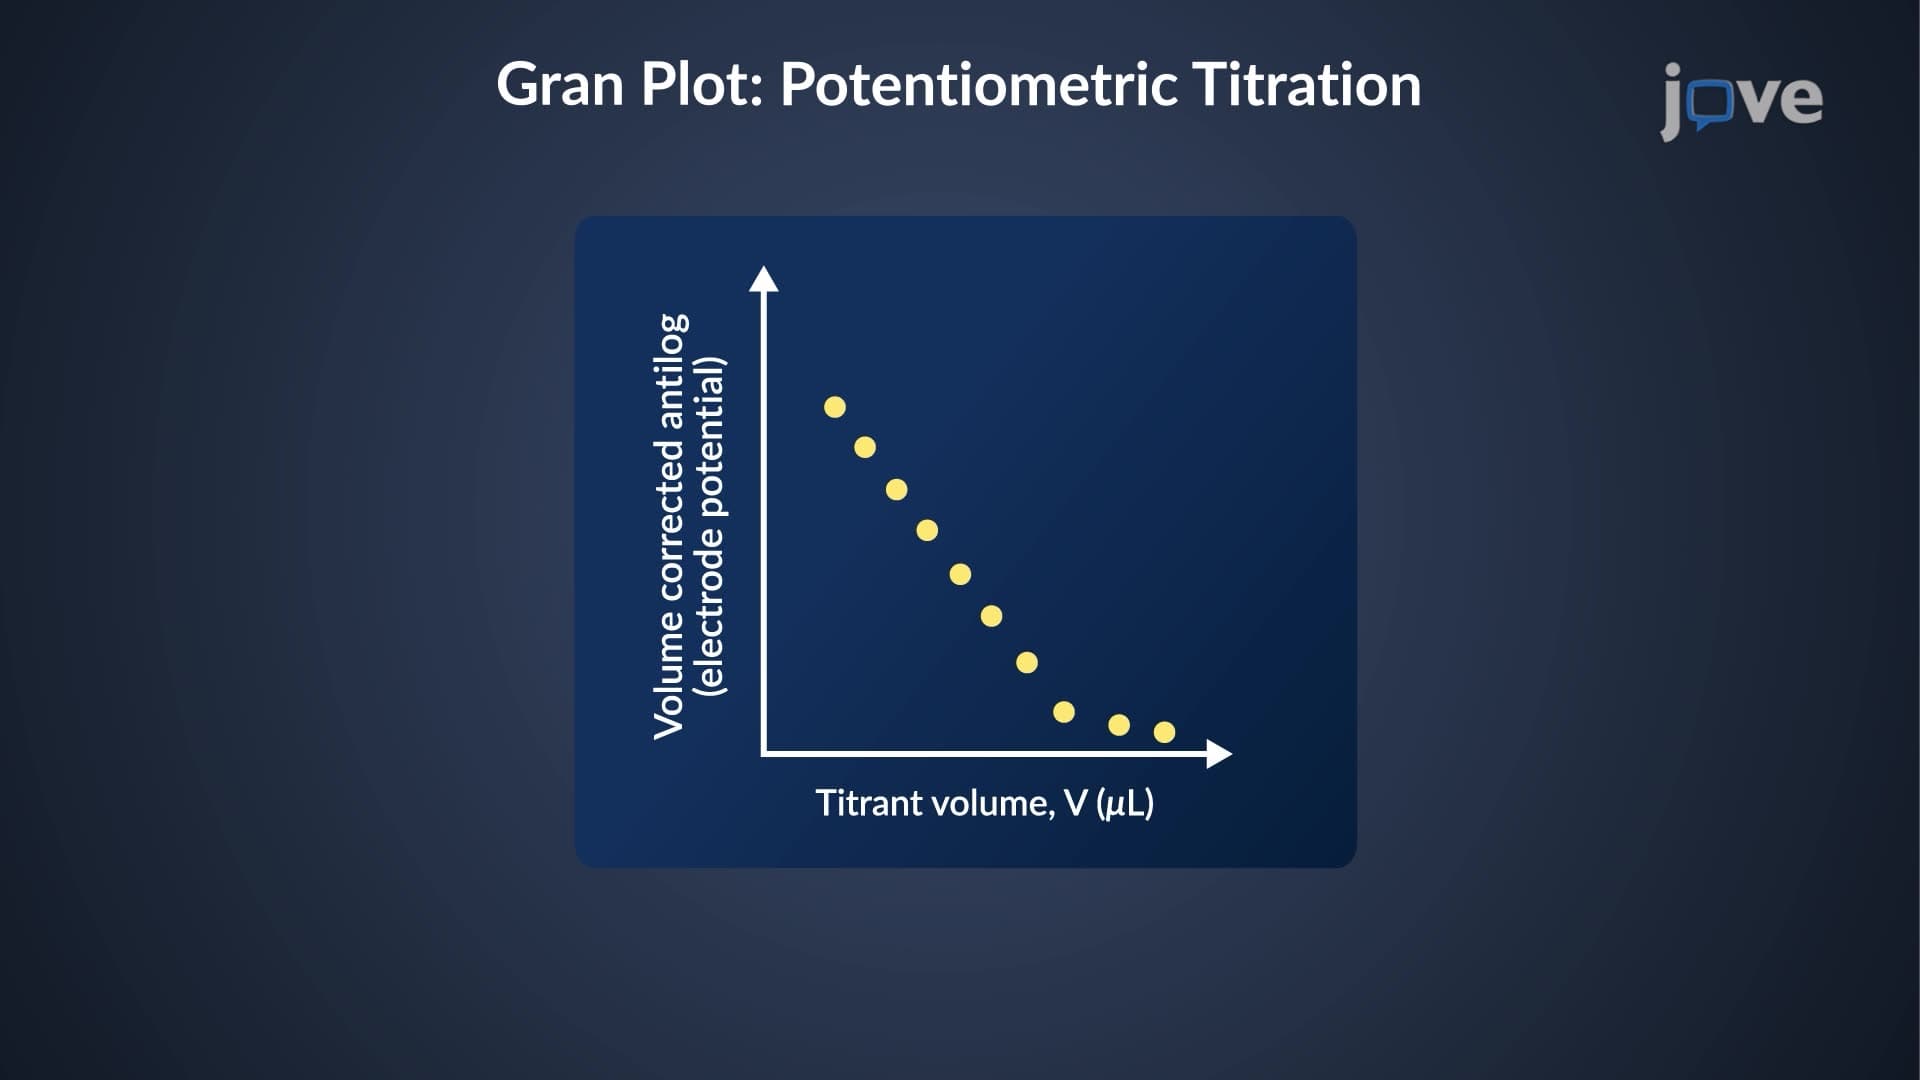
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
318
 01:12
Hindsight Biases
3.4K
Hindsight bias leads you to believe that the event you just experienced was predictable, even though it really wasn’t. In other words, you knew all along that things would turn out the way they did. Can you relate this to the phrase "Hindsight is 20/20" now?
3.4K
 01:08
Outliers and Influential Points
4.0K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.0K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K