
通过深度支持向量回归理解城市地区PM2.5空气污染的差异
Yuling Xia1, Teague McCracken2, Tong Liu2
1School of Mathematics, Southwest Jiaotong University, Sichuan province Chengdu 611756, China.
Environmental science & technology
|May 3, 2024

概括
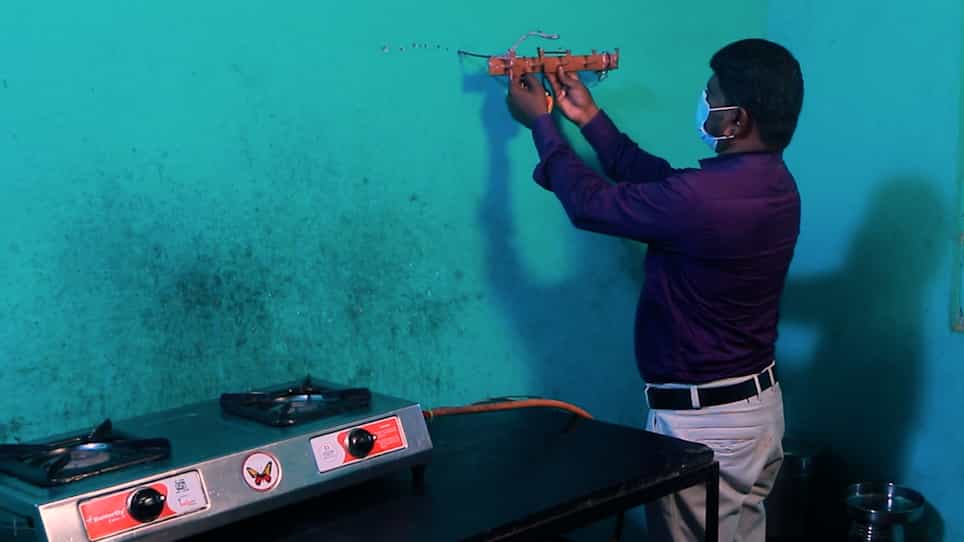
这项研究引入了深度支向量回归 (DSVR) 来准确预测城市中的微颗粒物 (PM2.5) 污染. 视频录像系统有效地捕捉了污染.
科学领域:
- 环境科学 环境科学
- 城市规划 城市规划
- 数据科学数据科学数据科学
背景情况:
- 微细颗粒物 (PM2.5) 显著影响城市公共卫生和生活质量.
- 现有的PM2.5预测模型往往无法考虑空间溢出效应和数据复杂性,导致不准确.
- 了解PM2.5差异对于城市可持续性和健康管理至关重要.
研究的目的:
- 通过结合空间溢出效应,开发一个先进的模型来预测城市地区的PM2.5差异.
- 通过解决传统模型的局限性来提高PM2.5空间预测的准确性.
- 增强对PM2.5在不同城市地区之间的联系和变异的理解.
主要方法:
- 提出了一个深度支持向量回归 (DSVR) 模型,以城市区域作为图形,以网格中心为节点.
- 利用自然和人类活动特征来初始化节点表示.
- 采用基于随机扩散的深度学习和随机步行来量化本地和非本地PM2.5溢出效应.
- 应用预测学习使用封装溢出效应的特征向量.
主要成果:
- 与纽约北部地区的传统和非溢出模型相比,DSVR模型的预测性能优越.
- 在PM2.5激增期间,DSVR达到R平方值高达0.729.
- 无溢出模型的DSVR性能比非溢出模型高2.5至5.7倍,传统的空间度量模型高2.2至4.6倍.
结论:
- 该DSVR模型在了解城市环境中的PM2.5空气污染差异方面取得了重大进展.
- 这种方法为PM2.5预测提供了一种新的方法,可以考虑溢出效应和数据非线性.
- 这些发现支持制定针对城市空气质量管理和公共卫生保护的有针对性的干预措施.
更多相关视频
相关概念视频
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:13
Mean Absolute Deviation
2.6K
The mean absolute deviation is also a measure of the variability of data in a sample. It is the absolute value of the average difference between the data values and the mean.
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
2.6K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:23
Sampling Plans
181
Sampling is a crucial step in analytical chemistry, allowing researchers to collect representative data from a large population. Common sampling methods include random, judgmental, systematic, stratified, and cluster sampling.
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...
181