
DiSMVC:一个多视图图协作学习框架,用于测量疾病相似性
Hang Wei1, Lin Gao1, Shuai Wu1
1School of Computer Science and Technology, Xidian University, Xi'an, Shaanxi 710126, China.
Bioinformatics (Oxford, England)
|May 8, 2024

概括
我们开发了DiSMVC,这是一种新的计算方法,通过整合多分子调节来测量疾病相似性. 这种方法增强了对疾病关联的理解,并有助于生物标志物的发现.
科学领域:
- 计算生物学是一种计算生物学.
- 生物信息学是一种生物信息学.
- 基因组学就是基因组学.
背景情况:
- 了解疾病关联对于识别生物标志物和药物点至关重要.
- 现有的疾病相似性的计算方法缺乏生物解释性和效率,因为对多分子调节的考虑有限.
研究的目的:
- 提出DiSMVC,一种用于测量疾病相似性的新计算方法.
- 提高疾病关联模式捕获的生物解释性和效率.
主要方法:
- DiSMVC使用了一个监督图表协作框架.
- 它通过交叉视图对比学习整合了基因和miRNA关联,用于疾病表示.
- 疾病相似性是使用关联模式联合学习与表型数据计算的.
主要成果:
- DiSMVC有效地提取疾病对的歧视性特征.
- 该方法在预测疾病关联方面优于现有的最先进的方法.
- 实验结果证明了DiSMVC对分子解释性的潜力.
结论:
- DiSMVC为预测疾病关联提供了一种有前途的方法.
- 与以前的计算工具相比,该方法提供了增强的分子解释性.
- DiSMVC有助于更深入地了解疾病的病理机制.
更多相关视频

相关概念视频
 01:17
Classification of Illness
7.5K
The meaning of illness is individualized to each person who experiences an alteration in health. In contrast, disease is a medical term indicating a pathological change in the structure and function of the body or mind. It is a condition that has specific symptoms and boundaries.
An illness is a response to a disease in which the person's level of functioning is changed compared with a previous level. The general classification of illness includes acute and chronic.
Acute illness is severe...
An illness is a response to a disease in which the person's level of functioning is changed compared with a previous level. The general classification of illness includes acute and chronic.
Acute illness is severe...
7.5K
 01:26
Principles of Disease Surveillance
91
Disease surveillance is the systematic collection, analysis, and interpretation of health data essential to the planning, implementation, and evaluation of public health practice. This process integrates data dissemination to entities responsible for preventing and controlling disease, injury, and disability. Surveillance systems provide crucial information for action, helping public health authorities make informed decisions to manage and prevent outbreaks, ensure public safety, optimize...
91
 01:25
Statistical Methods for Analyzing Epidemiological Data
363
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
363
 01:21
Causality in Epidemiology
395
Causality or causation is a fundamental concept in epidemiology, vital for understanding the relationships between various factors and health outcomes. Despite its importance, there's no single, universally accepted definition of causality within the discipline. Drawing from a systematic review, causality in epidemiology encompasses several definitions, including production, necessary and sufficient, sufficient-component, counterfactual, and probabilistic models. Each has its strengths and...
395
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
68
Pharmacokinetic models are mathematical constructs that represent and predict the time course of drug concentrations in the body, providing meaningful pharmacokinetic parameters. These models are categorized into compartment, physiological, and distributed parameter models.
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
68
 01:07
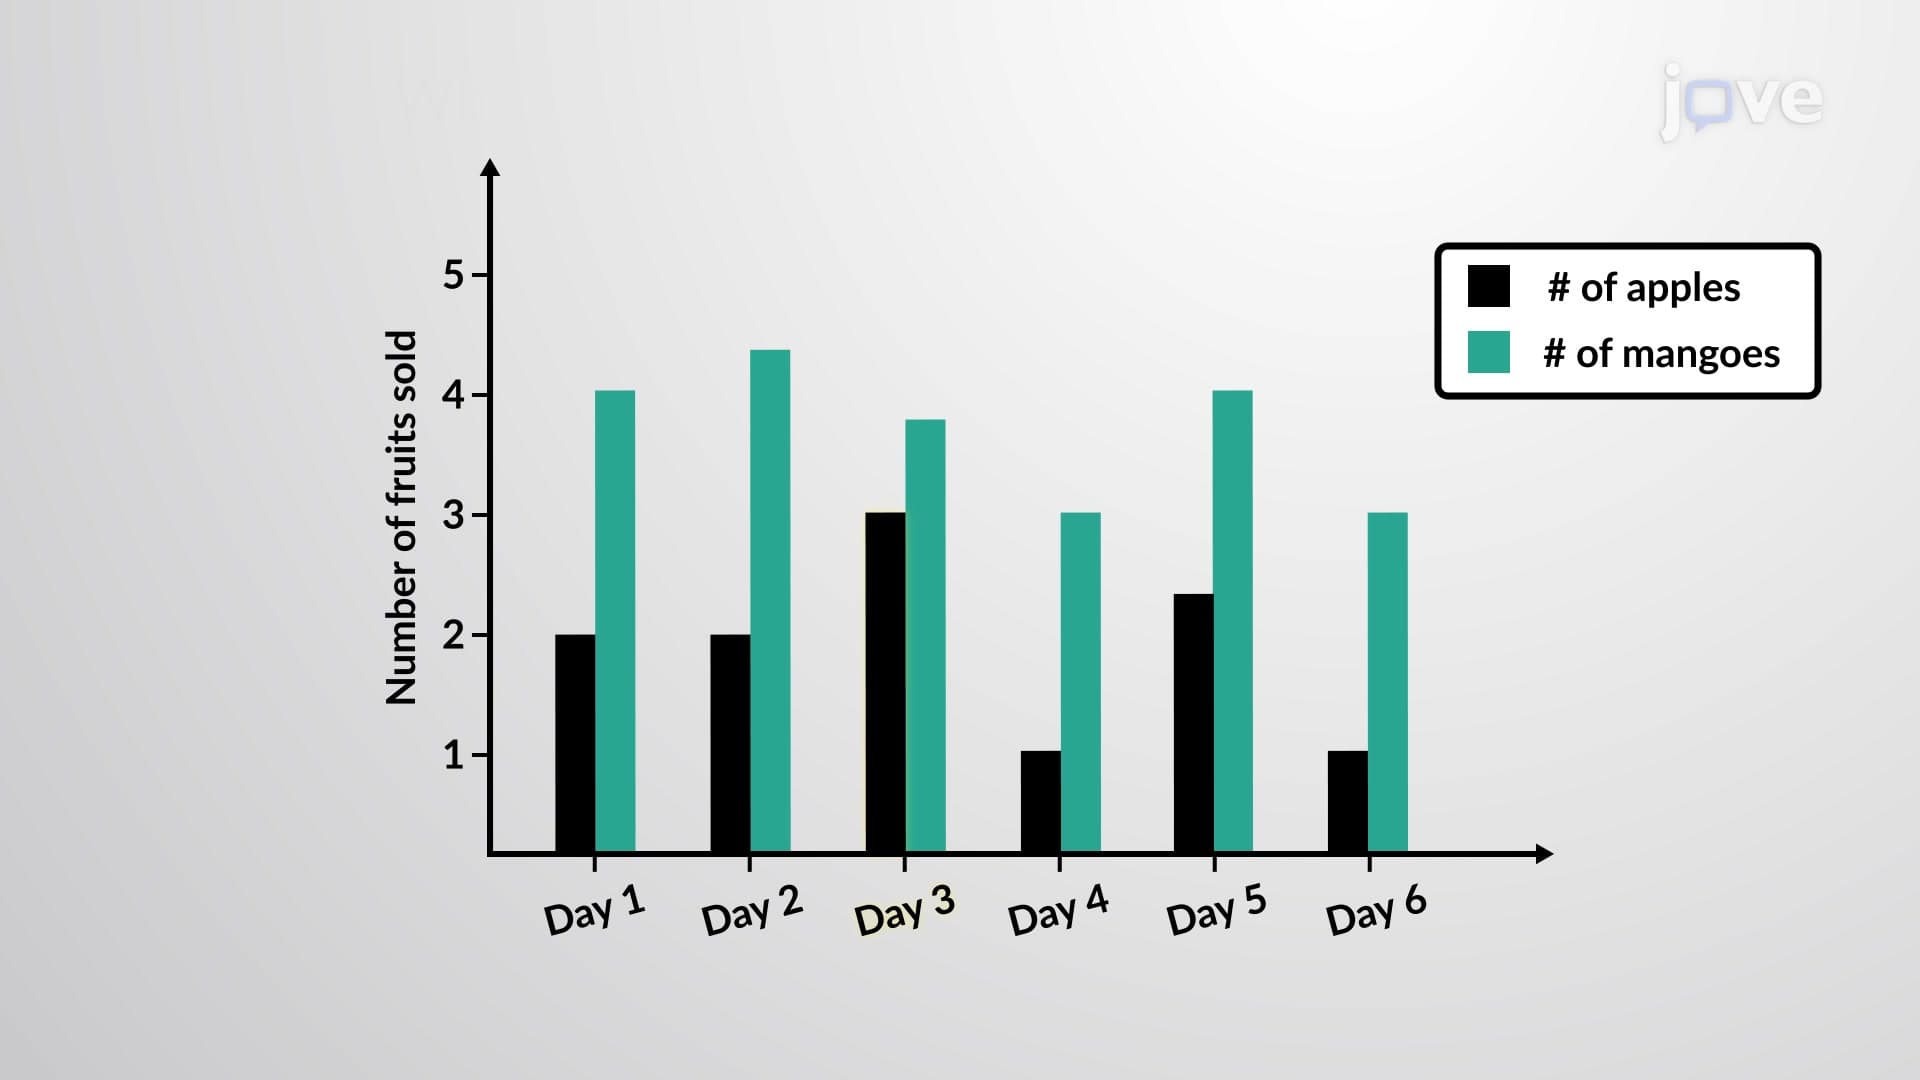
Multiple Bar Graph
5.1K
As the name suggests, a multiple bar graph is the same as a bar graph but has multiple bars to depict relationships between different data values. One can include as many parameters as possible. However, each parameter must have the same unit of measurement.
Each bar or column in the multiple bar graph represents a data value. These graphs are used primarily in interrelating two or more sets of data. The categories of different kinds of data are listed along the horizontal or x-axis, whereas...
Each bar or column in the multiple bar graph represents a data value. These graphs are used primarily in interrelating two or more sets of data. The categories of different kinds of data are listed along the horizontal or x-axis, whereas...
5.1K