
农村转型是否影响农村收入不平等? 来自孟加拉国跨地区小组数据分析的见解
Al Amin Al Abbasi1, Subrata Saha1, Ismat Ara Begum2
1Department of Agribusiness and Marketing, Bangladesh Agricultural University, Mymensingh, 2202, Bangladesh.
Heliyon
|May 10, 2024

概括
农村转型最初增加了收入不平等,但长期减少了收入不平等. 政府的社会安全网显著减少了孟加拉国的农村收入不平等.
科学领域:
- 农业经济学 农业经济学
- 发展经济学 发展经济学
- 农村社会学 农村社会学
背景情况:
- 农村转型对于改善农村生计和就业至关重要.
- 了解其对收入不平等的影响对于政策制定至关重要.
研究的目的:
- 调查农村转型对孟加拉农村收入不平等的影响.
- 分析农村转型指标与收入不平等之间的关系.
主要方法:
- 利用来自孟加拉国的全国代表性家庭收入和支出调查数据.
- 使用吉尼系数来衡量农村收入不平等.
- 应用非线性回归来分析农村转型指标 (高价值农业,非农业就业) 与收入不平等之间的关系.
主要成果:
- 农村收入不平等与高价值农业产出和非农业就业份额有正相关.
- 观察到一个反转的U形关系:不平等最初随着变化而上升,然后下降.
- 与家庭教育支出,农业租活动和汇款发现了积极的相关性.
结论:
- 农村转型对收入不平等的影响是复杂的,具有长期的均衡效应.
- 政府的社会安全网计划有效地减少了孟加拉国的农村收入不平等.

相关概念视频
 01:08
Outliers and Influential Points
4.0K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.0K
 01:06
Skewness
11.0K
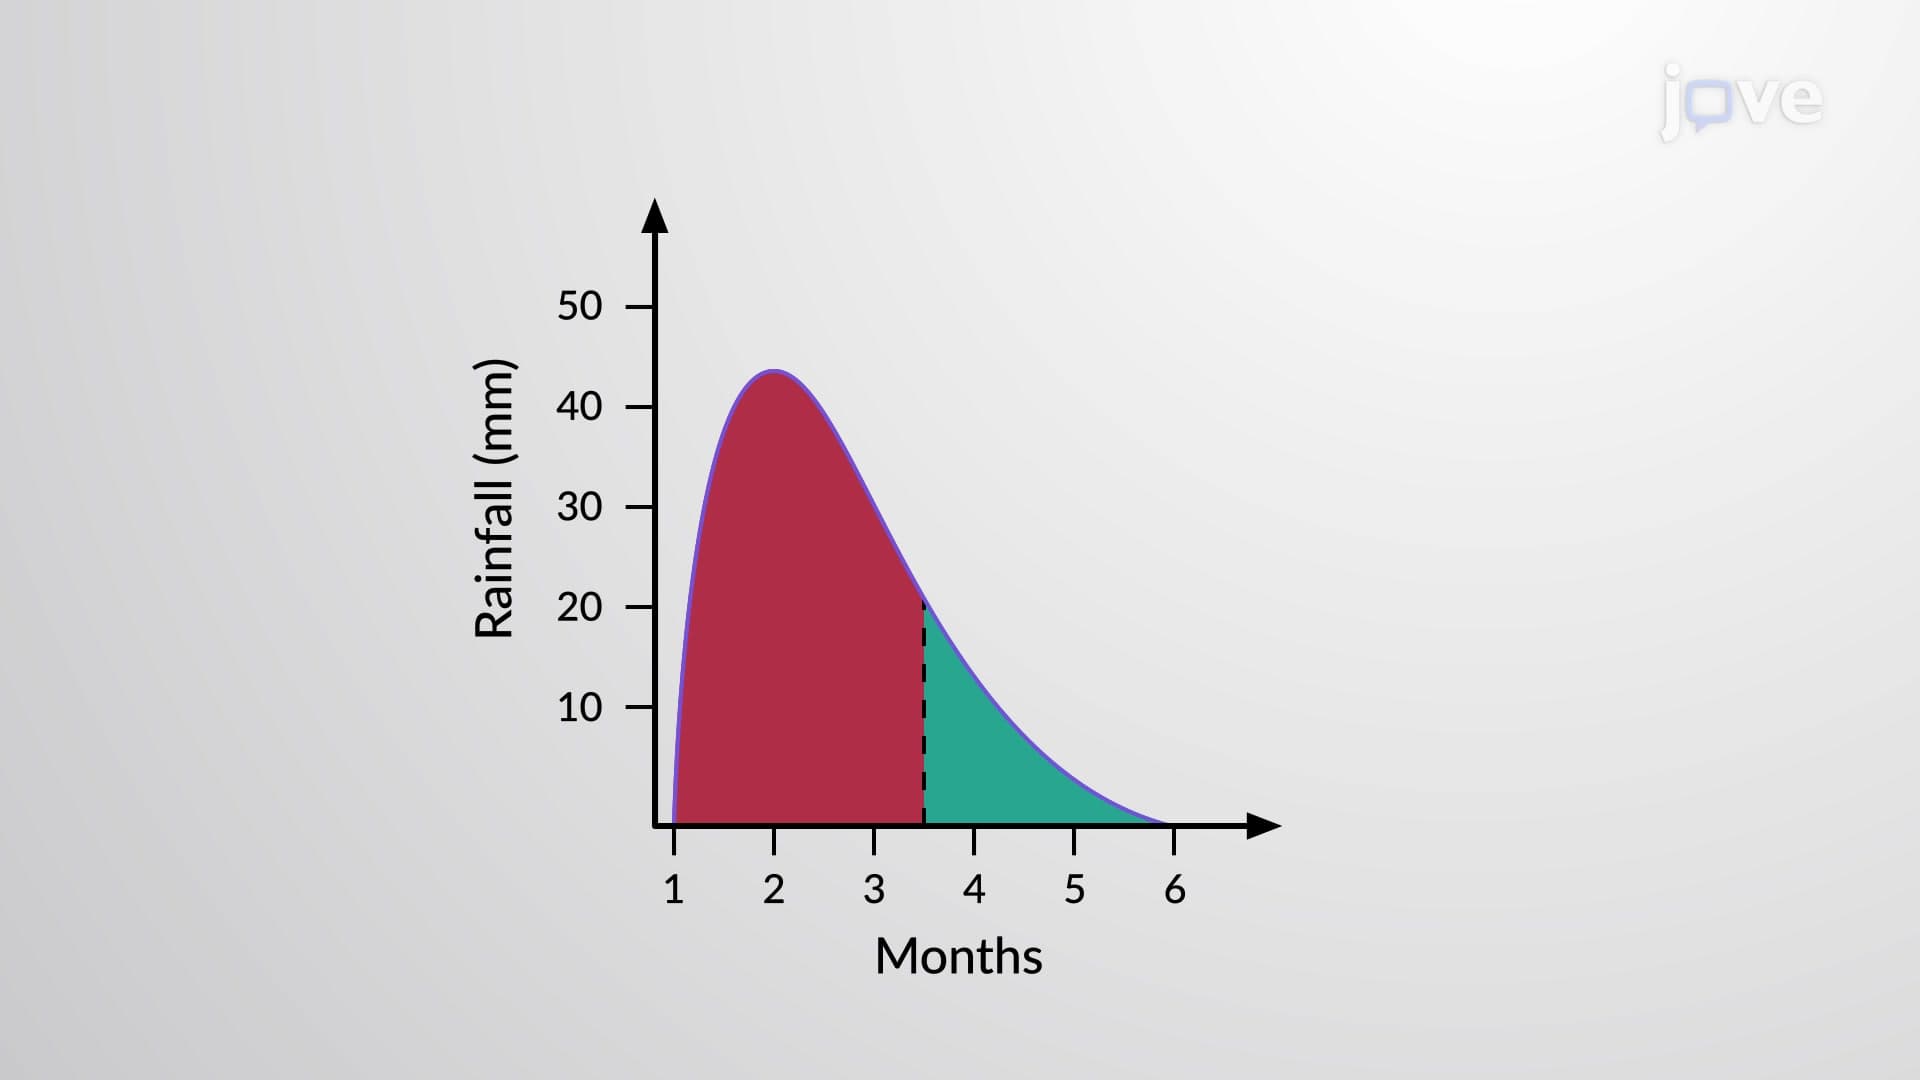
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
11.0K
 01:50
Cross-Sectional Research
11.3K
In cross-sectional research, a researcher compares multiple segments of the population at the same time. If they were interested in people's dietary habits, the researcher might directly compare different groups of people by age. Instead of following a group of people for 20 years to see how their dietary habits changed from decade to decade, the researcher would study a group of 20-year-old individuals and compare them to a group of 30-year-old individuals and a group of 40-year-old...
11.3K
 01:20
Cluster Sampling Method
11.9K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
11.9K
 01:14
Extraction: Partition and Distribution Coefficients
2.4K
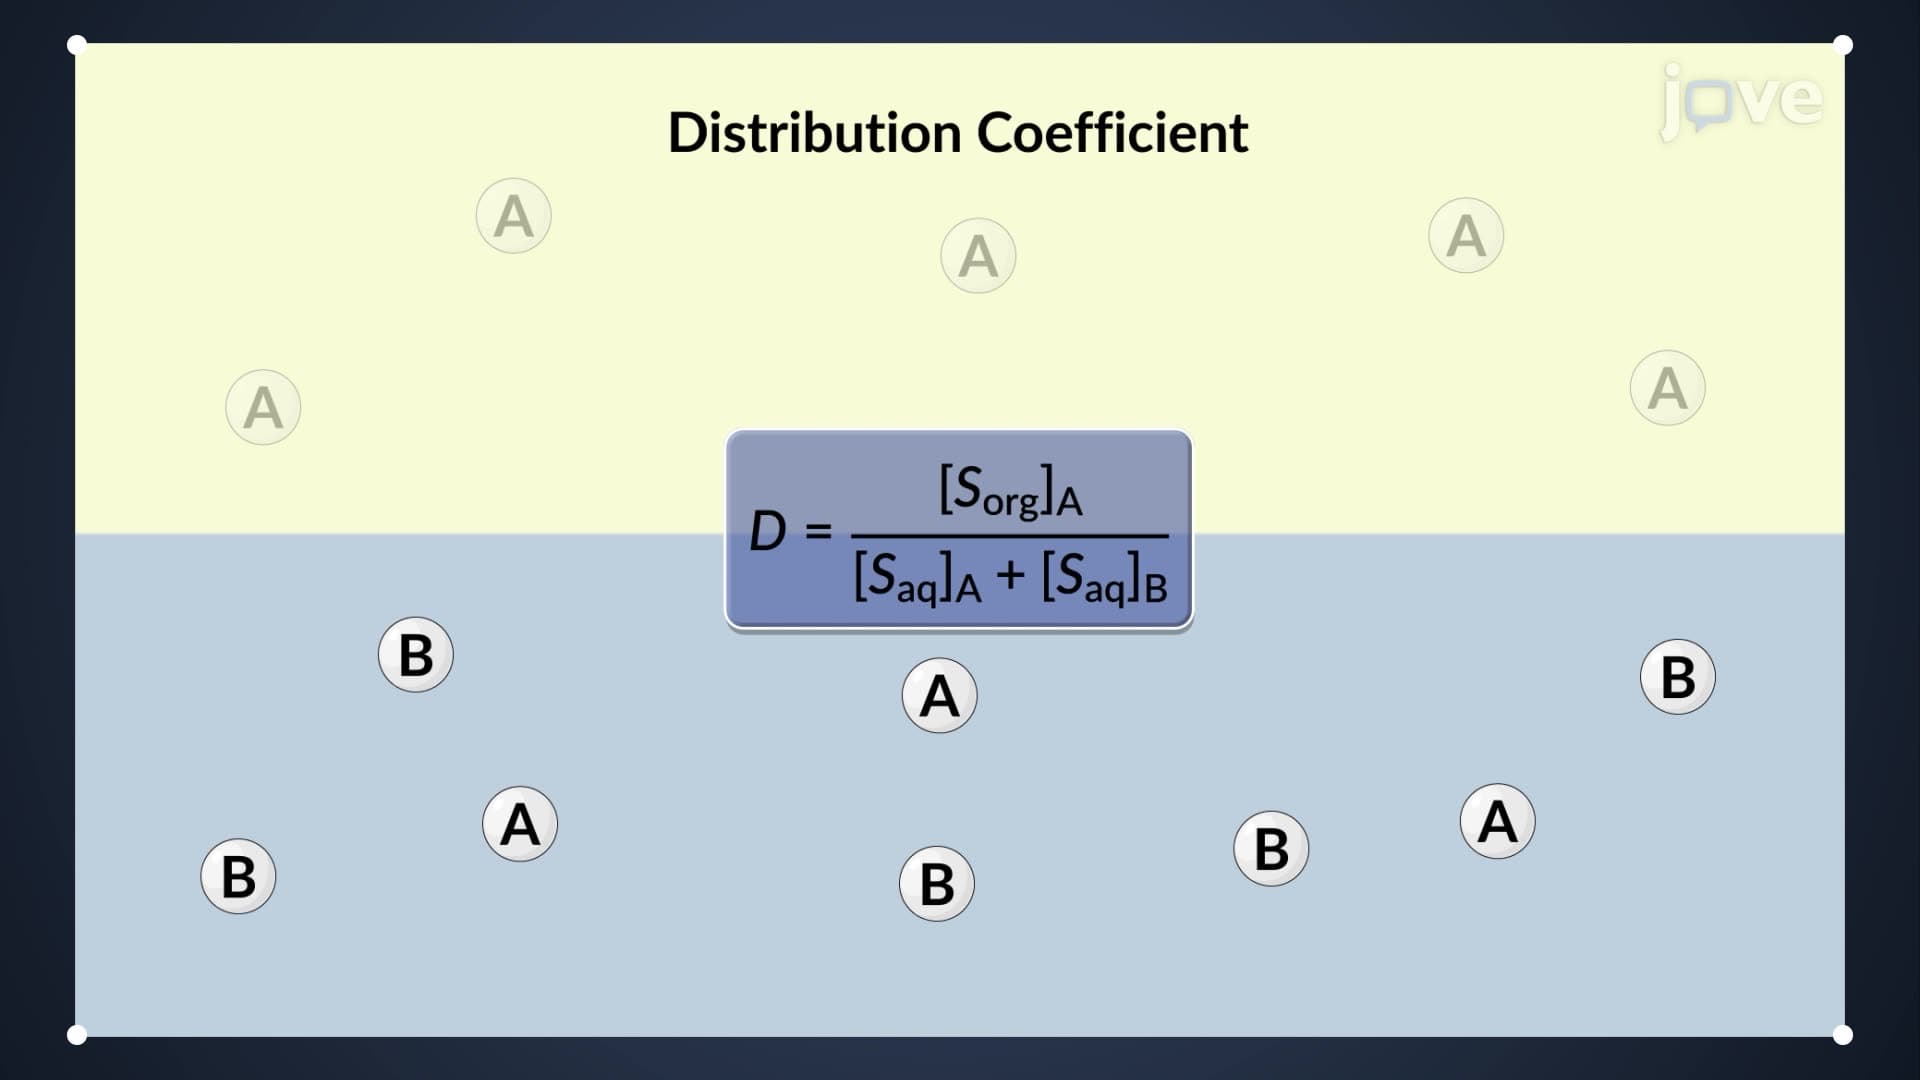
The distribution law or Nernst's distribution law is the law that governs the distribution of a solute between two immiscible solvents. This law, also known as the partition law, states that if a solute is added to the mixture of two immiscible solvents at a constant temperature, the solute is distributed between the two solvents in such a way that the ratio of solute concentrations in the solvents remains constant at equilibrium.
For extracting a solute from an aqueous phase into an...
For extracting a solute from an aqueous phase into an...
2.4K
 01:21
Friedman Two-way Analysis of Variance by Ranks
186
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
186