

选择无效的仪器以改善两个样本总结数据的门德尔随机化
Ashish Patel1, Francis J DiTraglia2, Verena Zuber3
1MRC Biostatistics Unit, University of Cambridge.
The annals of applied statistics
|May 13, 2024

概括
门德尔随机化 (MR) 使用遗传变异推断因果关系. 本研究引入了一种专注的仪器选择方法,以最大限度地降低平均平方误差,即使使用潜在的无效仪器,提高因果效应估计.
科学领域:
- 遗传学 遗传学 是一个
- 流行病学 流行病学
- 统计遗传学 统计遗传学
背景情况:
- 门德尔随机化 (MR) 对于估计风险因素和疾病之间的因果关系至关重要.
- 仪器选择是MR的基础,在仪器有效性和统计能力之间存在潜在的权衡.
- 大型全基因组关联研究 (GWAS) 提供了大量的遗传变异,使最佳仪器选择变得复杂.
研究的目的:
- 为孟德尔随机化 (MR) 开发一种"专注"的仪器选择方法,最大限度地减少估计的非对称平均平方误差.
- 提出一种新的策略,用于构建MR中选择后估计器的置信区间,解决潜在的覆盖损失.
- 在实证应用中评估最佳仪器选择策略,包括脂质药物标验证和维生素D效应研究.
主要方法:
- 开发了一种"专注"的仪器选择方法,以尽量减少MR因果效应估计的平均平方误差.
- 提出了一种新的方法,用于构建选择后因果效应估计器的置信区间,以保持非对称覆盖范围.
- 将这些方法应用于现实数据,以验证脂质药物标和评估维生素D对各种结果的影响.
主要成果:
- "聚焦"仪器选择方法有效地将因果效应估计的平均平方误差降到最低.
- 拟议的信任区间策略在许多软弱和潜在无效工具的环境中提供了强大的覆盖范围.
- 经验应用表明,最佳的仪器选择包括许多潜在的无效仪器,而不仅仅是少数生物学上合理的仪器.
结论:
- 在MR中最优的仪器选择,特别是许多软弱和潜在无效的仪器,涉及偏差和差异之间的平衡.
- "聚焦"仪器选择方法和相关的置信区间策略在复杂的遗传关联环境中提供了改进的因果推理.
- 调查结果挑战了对少数"有效"仪器的排他性依赖,主张包括更多的仪器来提高精度.

相关概念视频
 01:13
Randomized Experiments
6.9K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.9K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
38
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
38
 01:21
Friedman Two-way Analysis of Variance by Ranks
186
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
186
 01:18
One-Way ANOVA
7.9K
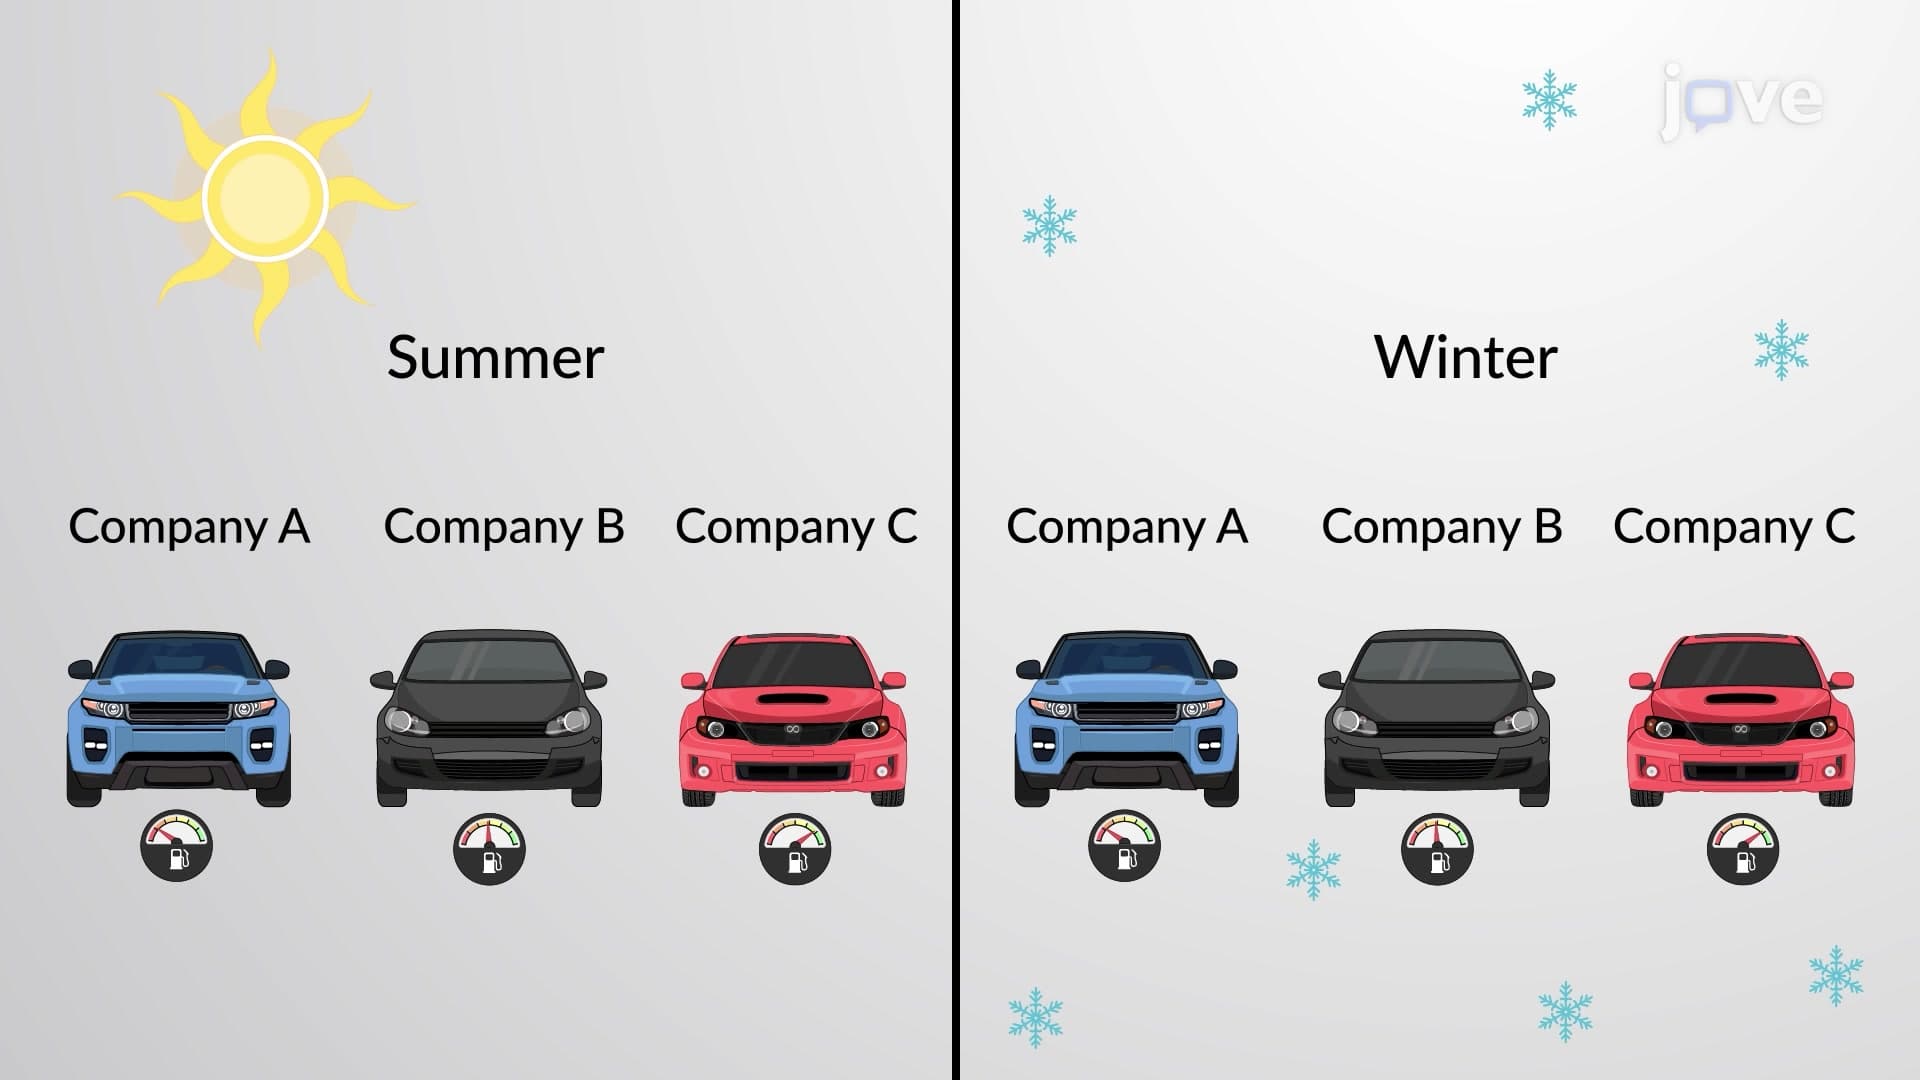
One-way ANOVA analyzes more than three samples categorized by one factor. For example, it can compare the average mileage of sports bikes. Here, the data is categorized by one factor - the company. However, one-way ANOVA cannot be used to simultaneously compare the sample mean of three or more samples categorized by two factors. An example of two factors would be sports bikes from different companies driven in different terrains, such as a desert or snowy landscape. Here, two-way ANOVA is used...
7.9K
 01:15
One-Way ANOVA: Equal Sample Sizes
3.3K
One-Way ANOVA can be performed on three or more samples with equal or unequal sample sizes. When one-way ANOVA is performed on two datasets with samples of equal sizes, it can be easily observed that the computed F statistic is highly sensitive to the sample mean.
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
3.3K
 01:15
One-Way ANOVA: Unequal Sample Sizes
5.8K
One-way ANOVA can be performed on three or more samples of unequal sizes. However, calculations get complicated when sample sizes are not always the same. So, while performing ANOVA with unequal samples size, the following equation is used:
5.8K