
自主监督的3D语义表示学习,用于视觉和语言导航

概括
本研究引入了一个新的视觉语言导航 (VLN) 框架,该框架使用3D语义数据与RGB图像一起. 这种方法通过创建详细的3D环境表示,显著提高了导航性能.
科学领域:
- 机器人技术 机器人技术 机器人技术
- 计算机视觉 计算机视觉
- 人工智能的人工智能
背景情况:
- 目前的视觉语言导航 (VLN) 方法主要依赖于RGB图像,忽视了有价值的3D语义环境数据.
- 整合3D语义信息可以为更强大的导航提供更丰富的环境理解.
研究的目的:
- 开发一个新的VLN框架,有效地将3D语义信息纳入导航过程.
- 通过利用全面的环境表示来提高导航准确性和效率.
主要方法:
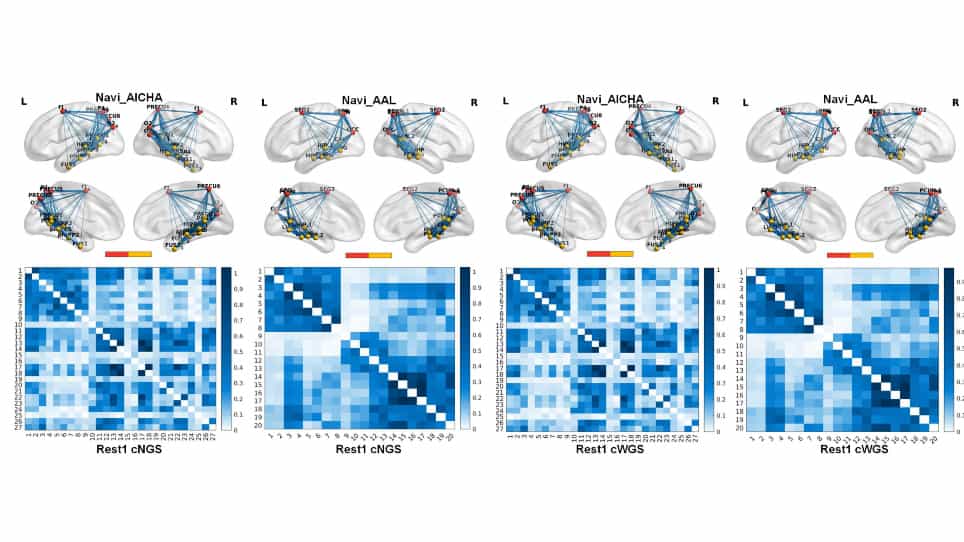
- 一个自主监督的训练方案,使用voxel级的3D语义重建来构建详细的3D语义表示.
- 一个借口任务,涉及区域查询以识别特定3D区域内的对象.
- 一个基于LSTM的导航模型,在3D语义表示上进行训练,通过交叉模式蒸策略增强,以合并RGB和3D语义特征.
主要成果:
- 拟议的框架成功地将3D语义数据集成到VLN任务中.
- 交叉模式蒸有效地合并RGB和3D语义特征,提高模型性能.
- 对R2R和R4R数据集的评估表明,在VLN任务中显著提高了性能.
结论:
- 整合3D语义信息对于推进视觉和语言导航至关重要.
- 开发的框架为更智能,更准确的机器人导航系统提供了一个有希望的方法.
- 未来的工作可以探索3D重建和跨模式融合技术的进一步改进.

相关概念视频
 01:15
Depth Perception and Spatial Vision
631
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
631
 01:24
Vision
53.2K
Vision is the result of light being detected and transduced into neural signals by the retina of the eye. This information is then further analyzed and interpreted by the brain. First, light enters the front of the eye and is focused by the cornea and lens onto the retina—a thin sheet of neural tissue lining the back of the eye. Because of refraction through the convex lens of the eye, images are projected onto the retina upside-down and reversed.
53.2K