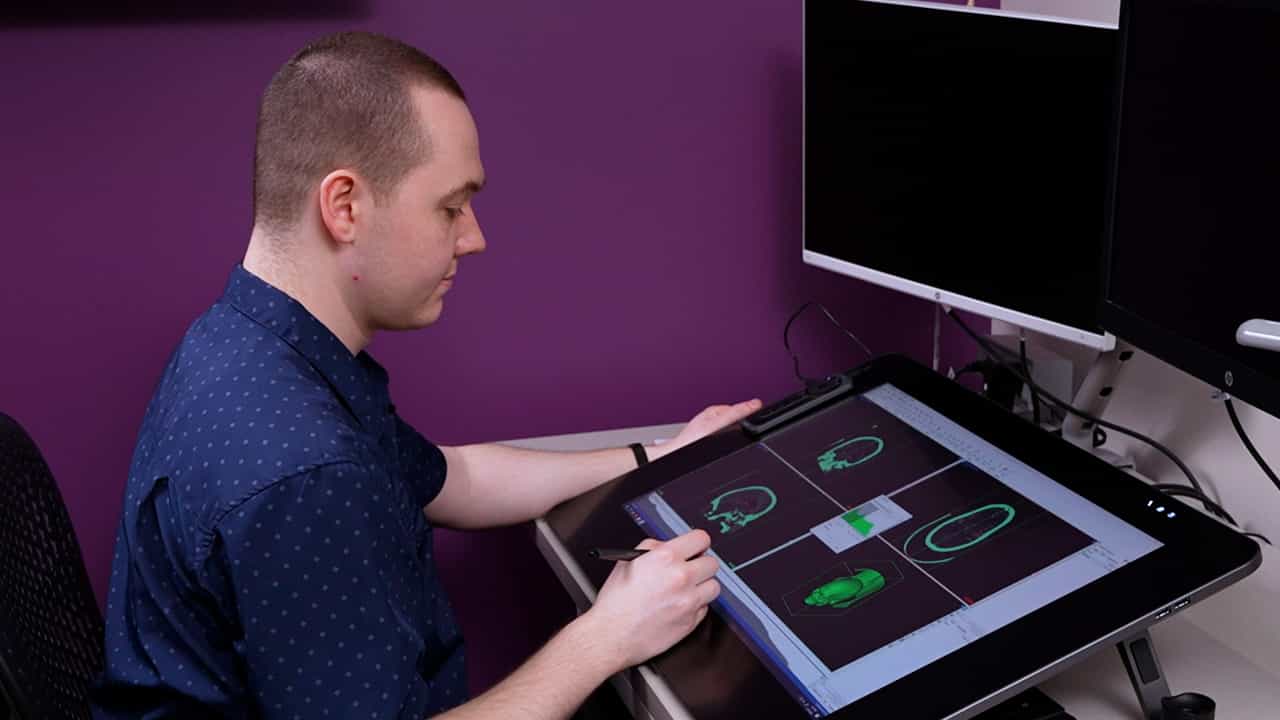

通过场景图知识推进外科VQA
Kun Yuan1,2,3, Manasi Kattel4,5, Joël L Lavanchy5
1University of Strasbourg, CNRS, INSERM, ICube, UMR7357, Strasbourg, France. kyuan@unistra.fr.

概括
这项研究引入了一个新的外科视觉问题答案 (VQA) 数据集和模型,SSG-VQA,通过结合场景图知识来增强外科计算机视觉,以提高准确性和推理.
科学领域:
- 计算机视觉 计算机视觉
- 人工智能的人工智能
- 医疗信息学 医疗信息学
- 手术数据科学手术数据科学
背景情况:
- 现代手术室需要先进的手术内支持系统.
- 手术数据科学正在扩展到视频分析之外,以整合自然语言处理.
- 当前的外科视觉问题答案 (VQA) 系统面临着数据集偏差和有限的场景意识推理的挑战.
研究的目的:
- 通过结合场景图知识来推进外科VQA.
- 为了解决手术VQA数据集中的问题条件偏差.
- 开发一个具有增强场景意识推理能力的外科VQA模型.
主要方法:
- 使用细分和检测模型创建了一个基于手术场景图的新型数据集 (SSG-VQA).
- 手术场景图是用仪器和解剖学的空间和动作信息来构建的.
- 提出了一个新的VQA模型,SSG-VQA-Net,具有嵌入场景的交互模块,用于通过交叉注意力集成几何场景知识.
主要成果:
- 与现有的数据集相比,SSG-VQA数据集更复杂,多样化,具有几何基础,不偏见,并且以行动为导向.
- 与现有方法相比,SSG-VQA-Net在各种问题类型和复杂性方面表现出卓越的表现.
- 缺乏现场知识被认为是当前手术VQA系统对复杂查询的主要局限性.
结论:
- 整合几何场景特征显著提高了手术VQA模型的性能.
- 当前手术VQA模型的瓶在于学习编码的表示,而不是序列解码.
- SSG-VQA数据集作为评估模型场景理解和推理能力的基准.

相关概念视频
 01:24
Vision
53.1K
Vision is the result of light being detected and transduced into neural signals by the retina of the eye. This information is then further analyzed and interpreted by the brain. First, light enters the front of the eye and is focused by the cornea and lens onto the retina—a thin sheet of neural tissue lining the back of the eye. Because of refraction through the convex lens of the eye, images are projected onto the retina upside-down and reversed.
53.1K
 01:26
Visual System
571
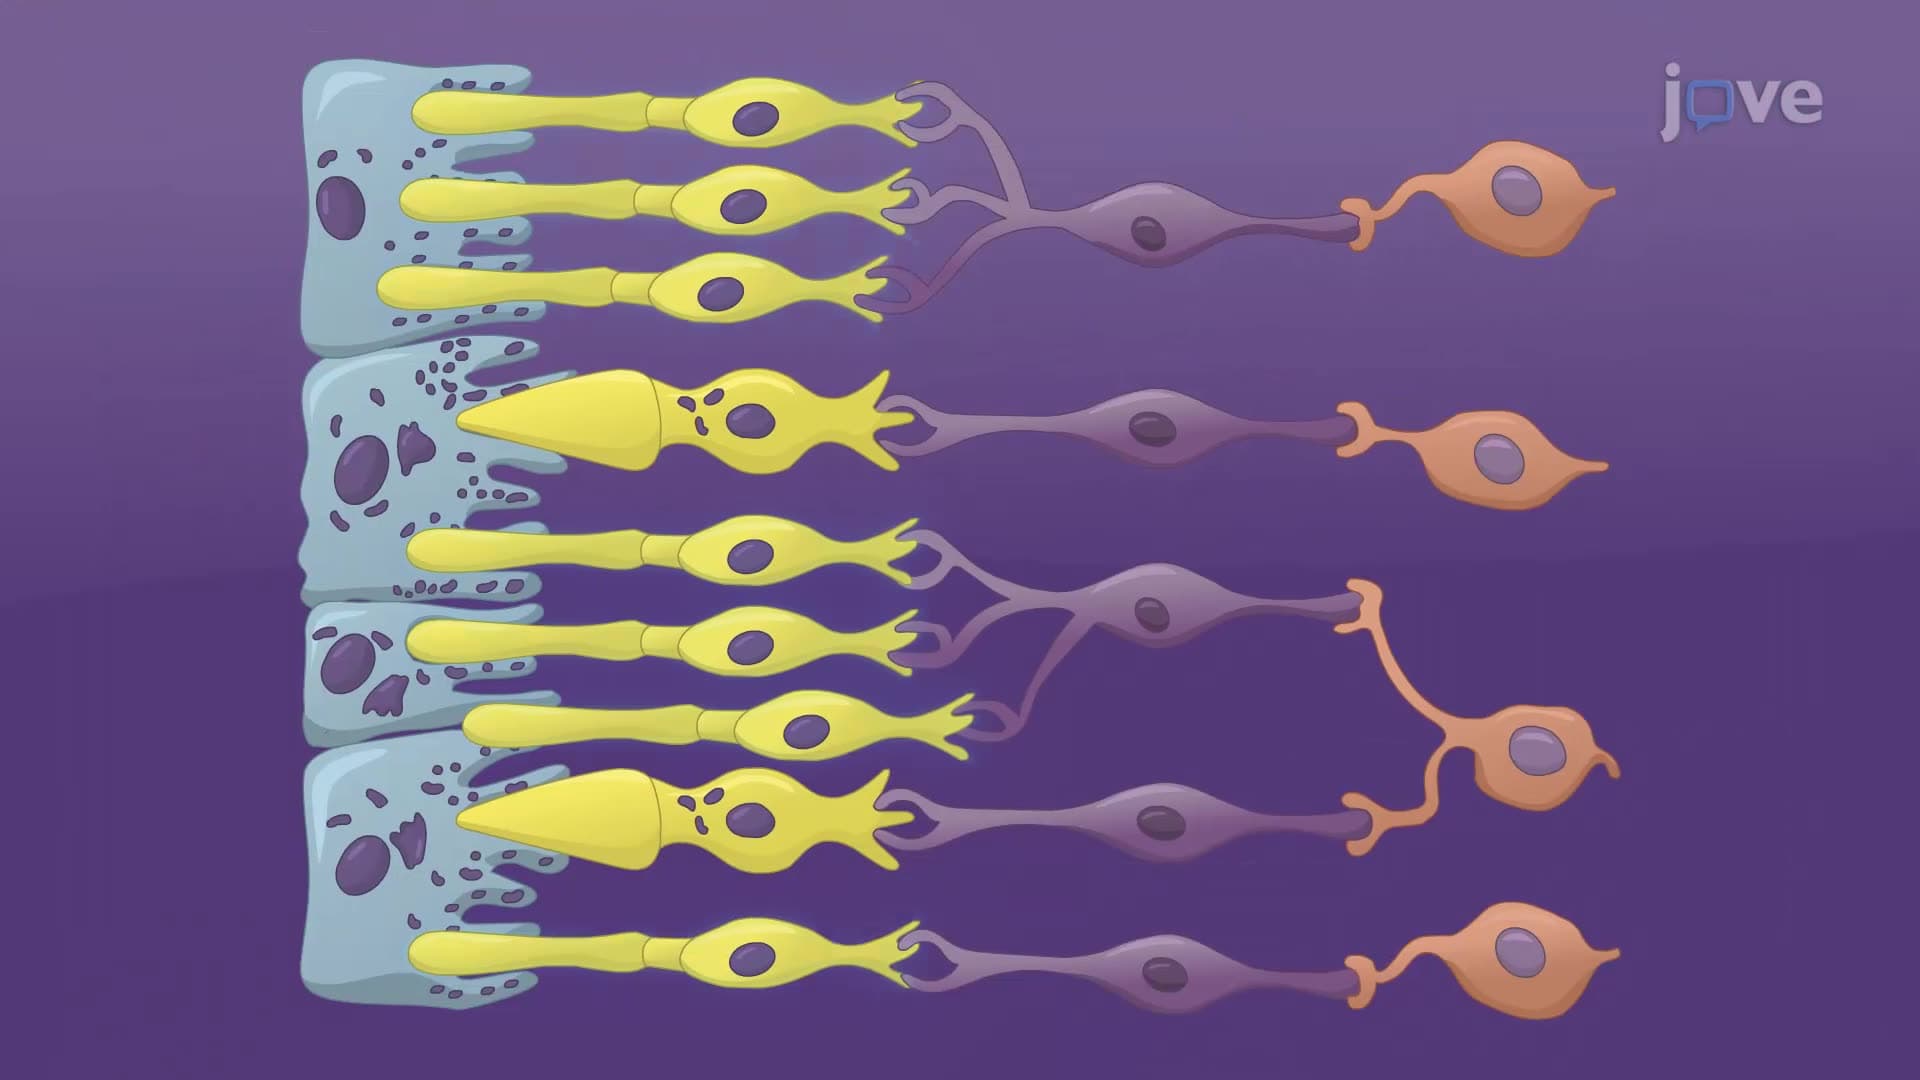
Light enters the eye through the cornea, a transparent, dome-shaped surface covering the surface of the eyeball that helps to direct and focus incoming light. This light is then channeled toward the pupil, an adjustable opening whose size is controlled by the iris. The iris, a pigmented muscle, regulates the amount of light entering the eye by contracting or dilating the pupil, thereby ensuring optimal light levels for clear vision.
Once through the pupil, the light passes through the lens, a...
Once through the pupil, the light passes through the lens, a...
571