
图书统计分析:针中风的研究趋势和表现
Fan Yang1, Yongqiang Cui1, Yuejuan Zhao2
1International Cooperation Department, Guang'anmen Hospital, China Academy of Chinese Medical Sciences, Beijing, People's Republic of China.
Journal of pain research
|May 27, 2024

概括
图书统计分析显示,中风研究中的针显著增长,主要来自中国. 未来的研究应该集中在临床有效性和改善康复结果的机制上.
科学领域:
- 神经学 神经学
- 综合医学是一个整体医学.
- 图书统计学 图书统计学
背景情况:
- 在全世界,中风是导致长期残疾的主要原因.
- 针是一种越来越多地被用于中风康复的传统疗法.
- 图书统计分析提供了研究趋势和影响的定量概述.
研究的目的:
- 为了总结针治疗中风使用图书统计学分析.
- 确定这一领域的趋势,主要研究热点和前沿地区.
- 评估针在中风治疗中的研究环境.
主要方法:
- 关于针治疗中风的文章的图书统计分析来自Web of Science核心集合 (至2023年).
- 使用CiteSpace软件进行国家,机构,作者,期刊和关键词的网络分析.
- 包括引用引用和关键字爆发率的分析.
主要成果:
- 获取了1141件物品,其中中国是最具生产力的国家.
- 北京中医药大学和作者陈LD和陶J是最多产的.
- P是被引用最多的作者;基于证据的补充和替代医学和中风是关键期刊.
- 高频关键词包括刺激,恢复,缺血性中风,电和康复.
结论:
- 关于针治疗中风的研究已经有了显著的发展,但国际合作需要加强.
- 未来的研究应该优先考虑高质量的临床研究,并探索功能康复的分子机制.
- 专注于基于证据的医学和跨学科的创新对于推动针治疗中风护理至关重要.
更多相关视频
相关概念视频
 01:13
Review and Preview
Data are individual items of information obtained from a population or sample. Data may be classified as qualitative (categorical), quantitative continuous, or quantitative discrete. Because it is not practical to measure the entire population in a study, researchers use samples to represent the population. A random sample is a representative group from the population chosen by using a method that gives each individual in the population an equal chance of being included in the sample. Random...
 00:52
Pareto Chart
A Pareto chart is a bar graph or a combination of both line and bar graphs. The bar lengths represent the individual values or the frequency, while the lines represent the cumulative total values. In this chart, the longest bars are arranged on the left and the shortest bars on the right, which makes it easier to read and interpret the data. It can also be called a Pareto diagram or Pareto analysis.
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
 01:10
Review and Preview
In statistics, several tools are used to interpret the data. Measures of central tendency represent the characteristics of the data, such as mean, median, and mode. Additionally, measures of variance like standard deviation and range are used to find the spread of data from the mean. Relative standing measures the distance between data locations. Commonly used measures of relative standings are percentile, z score, and quartiles.
Percentiles are a type of fractile that partition data into...
Percentiles are a type of fractile that partition data into...
 01:10
Central Tendency: Analysis
Measures of central tendency are tools used in biostatistics to identify the average or center of a dataset. They offer a single representative value for understanding and summarizing data distribution.
The mean is one such measure, calculated by totaling all values in a dataset and dividing by the number of values. For instance, the mean blood pressure reading (120, 130, 140, 150) would be 135. However, the mean can be affected by extreme values or outliers.
The median, another measure,...
The mean is one such measure, calculated by totaling all values in a dataset and dividing by the number of values. For instance, the mean blood pressure reading (120, 130, 140, 150) would be 135. However, the mean can be affected by extreme values or outliers.
The median, another measure,...
 01:12
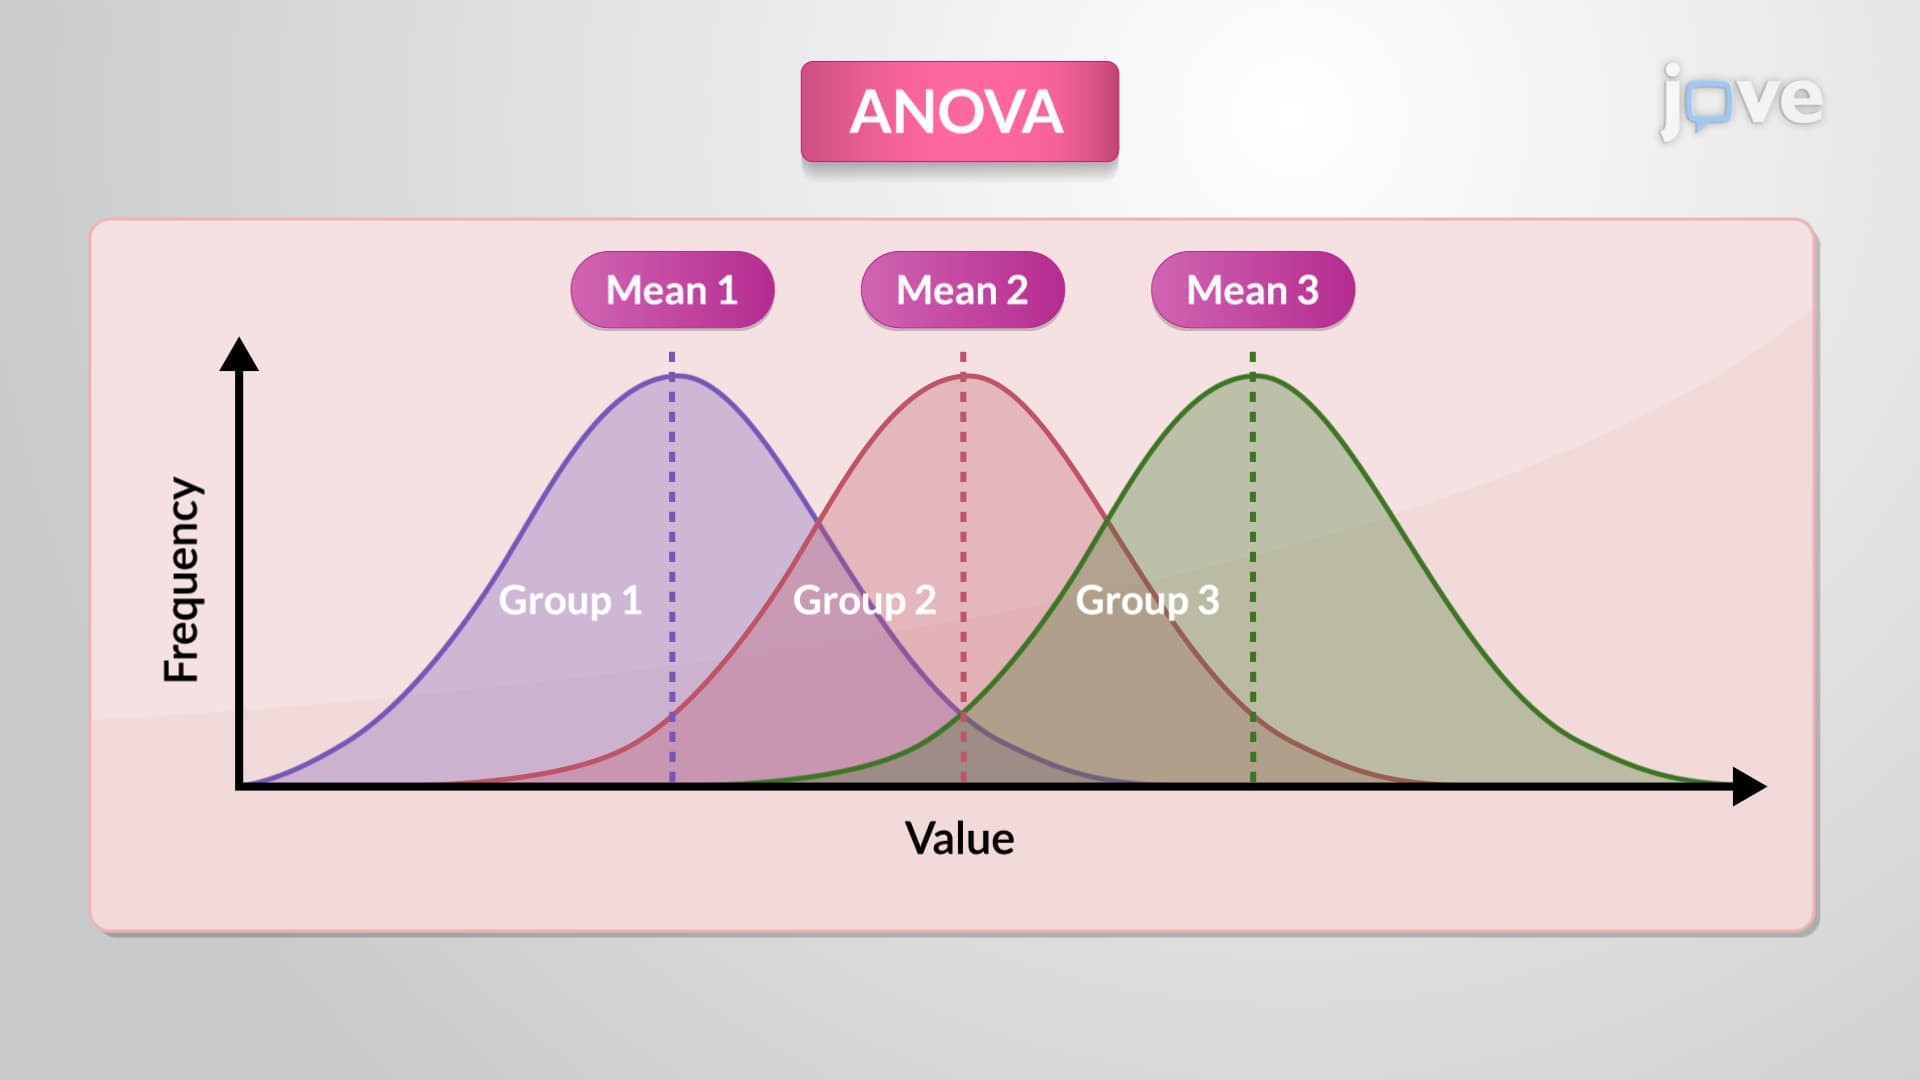
Statistical Methods to Analyze Parametric Data: ANOVA
Analysis of Variance, or ANOVA, is a powerful statistical technique used to analyze parametric data, primarily in research and experimental studies. It's designed to compare the means of two or more groups, assisting researchers in identifying any significant differences between these group means. There are two main types of ANOVA based on the complexity of the analysis: one-way and two-way.
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares the...
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares the...
 01:10
Statgraphics
Statgraphics is a comprehensive statistical software suite designed for both basic and advanced data analysis. Originating in 1980 at Princeton University under Dr. Neil W. Polhemus, it was one of the pioneering tools for statistical computing on personal computers, with its public release in 1982 marking an early milestone in data science software. Over the years, it has evolved into a robust platform for data science, offering tools for regression analysis, ANOVA, multivariate statistics,...