运营支持估计网络 运营支持估计网络

概括
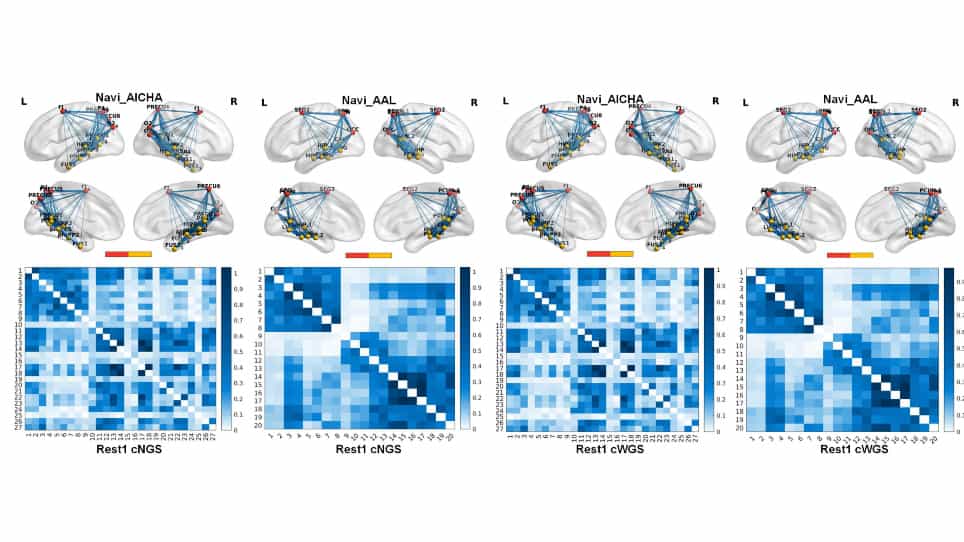
运营支持估计器网络 (OSEN) 通过学习非线性而提供高效的非代性支持估计,而无需深度网络. 这种新的方法显著提高了稀疏信号处理和压缩传感应用中的性能.
科学领域:
- 信号处理 信号处理
- 机器学习 机器学习
- 稀有信号恢复 稀有信号恢复
背景情况:
- 支持估计 (SE) 在稀疏信号中识别非零元素.
- 由于非线性信号映射,传统的SE方法需要计算密集的代技术.
- 现有的方法在效率上扎,尤其是在低测量速率下.
研究的目的:
- 引入运营支持估计器网络 (OSEN) 以改善非代的SE.
- 开发一种新的方法,使用具有生成超级神经元的操作层.
- 在稀疏信号应用中提高SE性能和计算效率.
主要方法:
- 拟议的OSEN利用操作层来学习复杂的非线性,没有深度网络.
- 集成的生成性超级神经元与非局部内核在训练期间优化.
- 在压力传感 (CS) 测量,分类和学习辅助的CS重建中评估了OSEN.
主要成果:
- 在非代性支持估计方面,OSEN显示出了显著的改进.
- 与现有方法相比,实现了优越的性能,特别是在低测量速率下.
- 在各种应用中展示了计算效率和有效性.
结论:
- OSENs为支持估计提供了一个计算效率高和高性能替代方案.
- 新的架构有效地处理非线性信号映射.
- 对于推进稀疏信号处理和压缩传感,OSENs显示出前景.

相关概念视频
 01:06
What are Estimates?
5.0K
It isn't easy to measure a parameter such as the mean height or the mean weight of a population. So, we draw samples from the population and calculate the mean height or mean weight of the individuals in the sample. This sample data acts as a representative measure of the population parameter. These sample statistics are known as estimates.
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
5.0K
 01:05
Estimation of the Physical Quantities
4.2K
On many occasions, physicists, other scientists, and engineers need to make estimates of a particular quantity. These are sometimes referred to as guesstimates, order-of-magnitude approximations, back-of-the-envelope calculations, or Fermi calculations. The physicist Enrico Fermi was famous for his ability to estimate various kinds of data with surprising precision. Estimating does not mean guessing a number or a formula at random. Instead, estimation means using prior experience and sound...
4.2K
 01:29
Econometric Views (EViews)
138
Econometric Views, often stylized as EViews, is a package that merges statistical analysis with econometric studies. It is designed to provide tools for time series analysis, forecasting, and econometric model simulation. The software originated from MicroTSP software and has evolved significantly since its inception in 1981. The history of EViews is marked by a continuous effort to enhance its computational speed and user interface. It was initially developed for large computing systems but...
138
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
48
Mechanistic models play a crucial role in algorithms for numerical problem-solving, particularly in nonlinear mixed effects modeling (NMEM). These models aim to minimize specific objective functions by evaluating various parameter estimates, leading to the development of systematic algorithms. In some cases, linearization techniques approximate the model using linear equations.
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
48
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K