
软指标和Poisson Kriging用于区域数据的噪声过和缩小的比较:应用于每日COVID-19发病率
Pierre Goovaerts1, Thomas Hermans2, Peter F Goossens3
1BioMedware, Inc. 167 Little lake dr., Ann Arbor, MI 48103, USA.
ISPRS international journal of geo-information
|June 7, 2024

概括
这项研究引入了软指标战争 (IK) 来改进空间流行病学分析,提供比Poisson战争 (PK) 更现实的疾病发病率. 该IK方法有效地过噪音,并处理不同的空间尺度,以获得更好的公共卫生洞察力.
科学领域:
- 流行病学 流行病学
- 地质统计学 在地质统计学
- 空间分析 空间分析
背景情况:
- 分析空间流行病学数据在人口规模较小和空间尺度不同时会带来挑战.
- 像Poisson kriging (PK) 这样的传统方法可以产生不切实际的发病率 (负或>100%).
研究的目的:
- 提出和评估软指标战争 (IK) 作为空间疾病发病率分析的PK的替代方案.
- 为了比较IK和PK在不同空间分辨率下过噪声和估计速率方面的性能.
主要方法:
- 采用了地理统计技术,特别是Poisson kriging (PK) 和软指标 kriging (IK).
- 在比利时市政府 (2020-2021) 的每日COVID-19发病率上应用方法.
- 在市政和1公里电网层面推导噪声过的发病率.
主要成果:
- 软指标策划 (IK) 方法避免了负估计,与PK相比,其平滑效应较小.
- 在聚合后,IK表现出与观察到的市级利率更好的一致性,特别是当初始利率为零时.
- 这两种方法都用于在多个尺度上评估空间疾病模式.
结论:
- 软指标策划 (IK) 为分析空间疾病发病率数据提供了更强大和更现实的方法.
- IK有效地解决了PK的局限性,为公共卫生监测提供了更好的估计.
- 该方法增强了通过不同空间分辨率传播疾病的分析.
相关概念视频
 01:25
Statistical Methods for Analyzing Epidemiological Data
353
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
353
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:26
Estimating Population Standard Deviation
3.0K
When the population standard deviation is unknown and the sample size is large, the sample standard deviation s is commonly used as a point estimate of σ. However, it can sometimes under or overestimate the population standard deviation. To overcome this drawback, confidence intervals are determined to estimate population parameters and eliminate any calculation bias accurately. However, this only applies to random samples from normally distributed populations. Knowing the sample mean and...
3.0K
 00:52
Pareto Chart
6.7K
A Pareto chart is a bar graph or a combination of both line and bar graphs. The bar lengths represent the individual values or the frequency, while the lines represent the cumulative total values. In this chart, the longest bars are arranged on the left and the shortest bars on the right, which makes it easier to read and interpret the data. It can also be called a Pareto diagram or Pareto analysis.
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
6.7K
 01:05
Difference from Background: Limit of Detection
6.3K
The limit of detection (LOD) is the smallest amount of analyte that can be distinguished from the background noise. The LOD value corresponds to the concentration at which the analyte signal is three times larger than the standard deviation of the blank signal. Below this value, the analyte signal cannot be differentiated from the background noise. It is calculated by dividing the calibration slope by 3 times the standard deviation of the blank signals.
The LOD indicates the presence or absence...
The LOD indicates the presence or absence...
6.3K
 01:09
Poisson Probability Distribution
7.8K
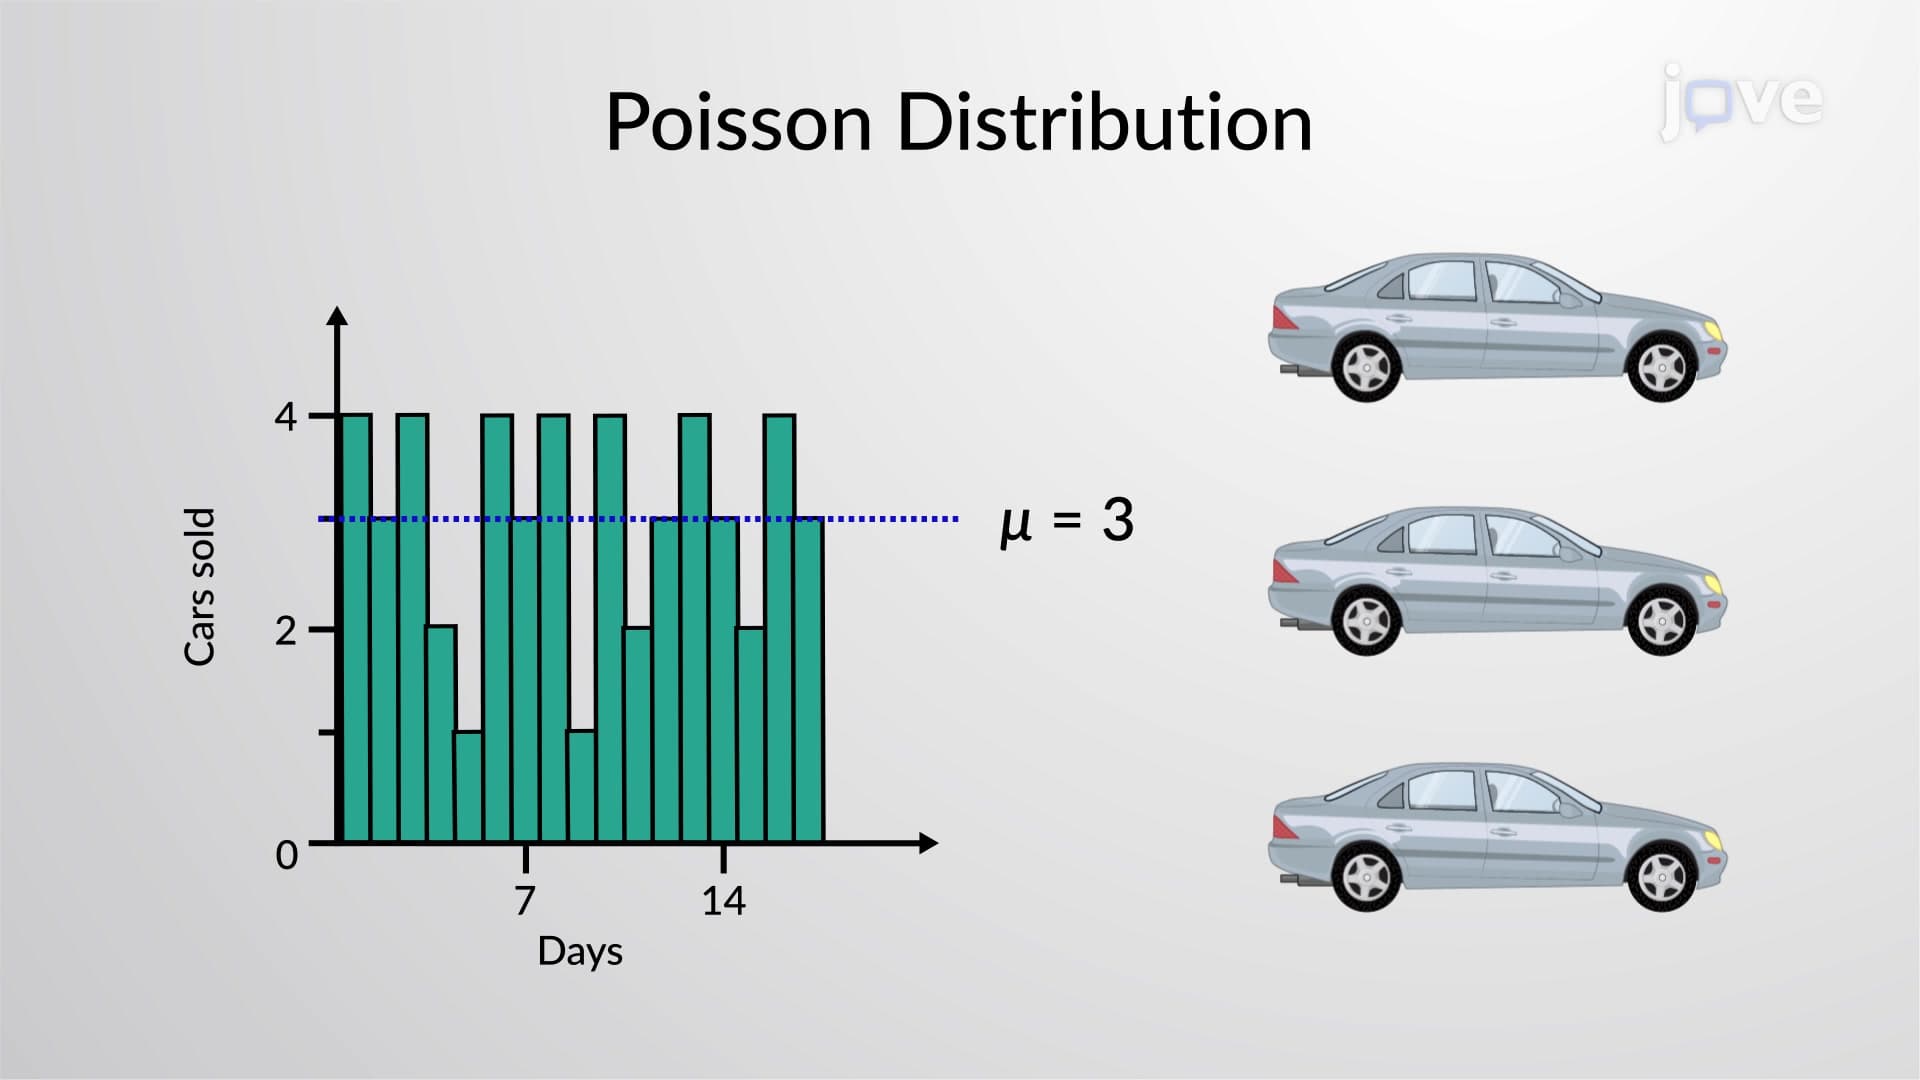
A Poisson probability distribution is a discrete probability distribution. It gives the probability of a number of events occurring in a fixed interval of time or space if these events happen at a known average rate and independently of the time since the last event. For example, a book editor might be interested in the number of words spelled incorrectly in a particular book. It might be that, on average, there are five words spelled incorrectly in 100 pages. The interval is 100 pages.
The...
The...
7.8K