
随机语言模型的稳定性
Fatemeh Lalegani1, Eric De Giuli1
1Department of Physics, <a href="https://ror.org/05g13zd79">Toronto Metropolitan University</a>, Toronto, Canada M5B 2K3.
Physical review. E
|June 22, 2024

概括
随机语言模型,即一组随机无上下文语法,解释了第一语言的获取为化. 这种模型对现实世界的学习复杂性具有强大耐用性,并与24个月的儿童语言发展保持一致.
科学领域:
- 计算语言学 计算语言学
- 认知科学 认知科学
- 机器学习 机器学习
背景情况:
- 随机语言模型 (RLM) 使用随机的无上下文语法来分析人类和计算机语言的语法.
- 它提出,第一语言的获取类似于在可能语言的空间中化.
- 基本的RLM建议通过自发的对称性破坏,通过自发的对称性破坏,不断过渡到语法语法.
研究的目的:
- 仔细检查RLM与模型扩展和替代参数空间轨迹的稳定性.
- 调查明确对称性破坏对语言学习模型的影响.
- 通过操纵深层和表面语言结构来探索语法语法语法的替代途径.
主要方法:
- 该研究通过引入明确的对称性破坏来扩展原来的随机语言模型.
- 它分析了通过模型的参数空间超出最初考虑的轨迹.
- 它将模型预测与语法网络集群系数上的人类数据进行比较.
主要成果:
- 即使有明确的对称性破坏,RLM场景仍然是强大的,这是现实世界的学习的一个关键方面.
- 语法语法可以通过修改可观察的属性,同时保持底层结构不变来实现.
- 在理想化的极限中,过渡到语法语法表现出了急剧热力学过渡的特征.
- 模型预测与人类语言数据保持一致,特别是语法网络的聚类系数,大约在儿童发育24个月.
结论:
- 随机语言模型为理解第一语言学习提供了一个强大的框架.
- 该模型的发现与语言发展的语言学理论和最近的机器学习进展相一致.
- 在模型中过渡到语法语法反映了人类婴儿的关键发展里程碑.
更多相关视频
 09:09
Foreign Accent and Forensic Speaker Identification in Voice Lineups: The Influence of Acoustic Features Based on Prosody
Published on: September 27, 2024
440
 06:48
Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
9.2K
相关概念视频
 01:13
Randomized Experiments
6.9K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.9K
 01:09
Random Variables
11.6K
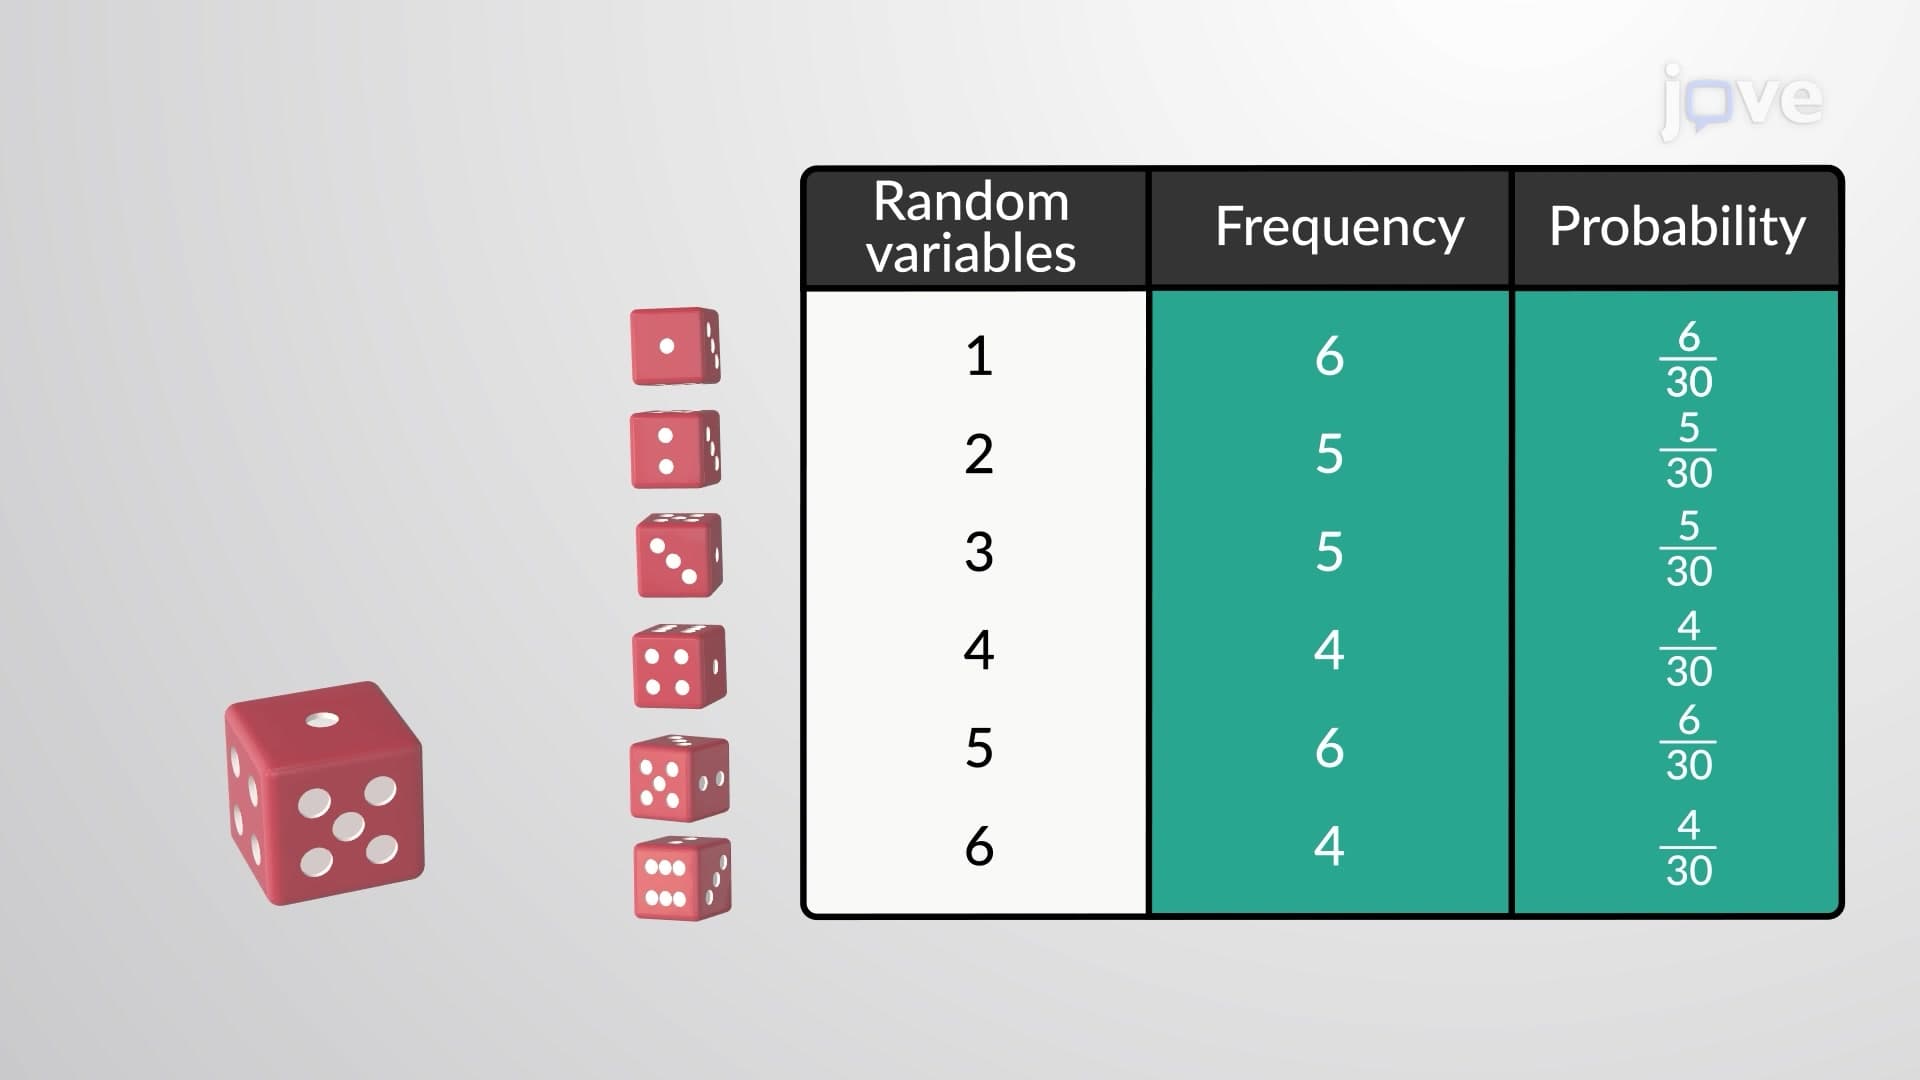
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
11.6K
 01:20
Random and Systematic Errors
10.9K
Scientists always try their best to record measurements with the utmost accuracy and precision. However, sometimes errors do occur. These errors can be random or systematic. Random errors are observed due to the inconsistency or fluctuation in the measurement process, or variations in the quantity itself that is being measured. Such errors fluctuate from being greater than or less than the true value in repeated measurements. Consider a scientist measuring the length of an earthworm using a...
10.9K
 00:59
Propagation of Uncertainty from Random Error
677
An experiment often consists of more than a single step. In this case, measurements at each step give rise to uncertainty. Because the measurements occur in successive steps, the uncertainty in one step necessarily contributes to that in the subsequent step. As we perform statistical analysis on these types of experiments, we must learn to account for the propagation of uncertainty from one step to the next. The propagation of uncertainty depends on the type of arithmetic operation performed on...
677
 01:17
Wald-Wolfowitz Runs Test II
226
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and...
226
 01:17
Wald-Wolfowitz Runs Test I
639
The Wald-Wolfowitz test, also known as the runs test, is a nonparametric statistical test used to assess the randomness of a sequence of two different types of elements (e.g., positive/negative values, successes/failures). It examines whether the order of the elements in a sequence is random or if there is a pattern or trend present. This nonparametric test applies to any ordered data despite the population and sample data distribution, even if a higher sample size is available.
The test works...
The test works...
639