
在量子卷积分类器中利用数据局部性
Mingyoung Jeng1, Alvir Nobel1, Vinayak Jha1
1Department of Electrical Engineering and Computer Science, University of Kansas, Lawrence, KS 66045, USA.
Entropy (Basel, Switzerland)
|June 26, 2024

概括
这项研究引入了一种多维量子卷积分类器 (MQCC),它保留了量子机器学习的数据局部性. MQCC适应了卷积神经网络结构用于变量量子算法,在多维数据集上显示了更好的性能.
科学领域:
- 量子计算是一种量子计算.
- 机器学习 机器学习
- 人工智能的人工智能
背景情况:
- 经典的机器学习 (ML) 任务正在被量子计算 (QC) 推进.
- 卷积神经网络 (CNN) 通过保留数据的局部性,在经典的ML中表现出色.
- 现有的量子CNN经常忽视数据局部性,特别是在多维数据中.
研究的目的:
- 提出一个多维量子卷积分类器 (MQCC),解决当前量子CNN的局限性.
- 适应CNN结构用于变量量子算法 (VQA),同时保持数据局部性,用于多维数据中的多特征提取.
主要方法:
- 开发了一个多维量子卷积分类器 (MQCC).
- 实现了多维和多特征量子卷积与平均值和欧几里德积分.
- 将CNN架构调整为一个变量量子算法 (VQA) 框架.
- 在多维数据集上使用噪声和无噪声量子模拟验证了MQCC.
主要成果:
- 在量子模拟中,MQCC证明了正确性和可扩展性.
- 在标准的ML数据集上对最先进的量子模拟器 (IBM Quantum,Xanadu) 进行评估.
- 与现有方法相比,展示了有利的定量指标,包括更少的训练参数,更低的交叉损失,更高的分类准确性,更少的电路深度和更少的量子门.
结论:
- 拟议的MQCC有效地保留了量子机器学习中的数据局部性,用于多维数据.
- MQCC为增强量子卷积神经网络提供了一个有希望的方法.
- 该方法在效率和性能指标方面显示出与现有技术相比显著的优势.
相关概念视频
 01:20
Parallel Processing
150
The brain processes sensory information rapidly due to parallel processing, which involves sending data across multiple neural pathways at the same time. This method allows the brain to manage various sensory qualities, such as shapes, colors, movements, and locations, all concurrently. For instance, when observing a forest landscape, the brain simultaneously processes the movement of leaves, the shapes of trees, the depth between them, and the various shades of green. This enables a quick and...
150
 01:29
Aggregates Classification
317
Aggregate classification is generally based on its size, petrographic characteristics, weight, and source. Size classification ranges from coarse to fine aggregates, defined by the size of the particles. Coarse aggregates are particles that do not pass through ASTM sieve No. 4, and aggregates that pass through the sieve are fine aggregates.
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
317
 01:14
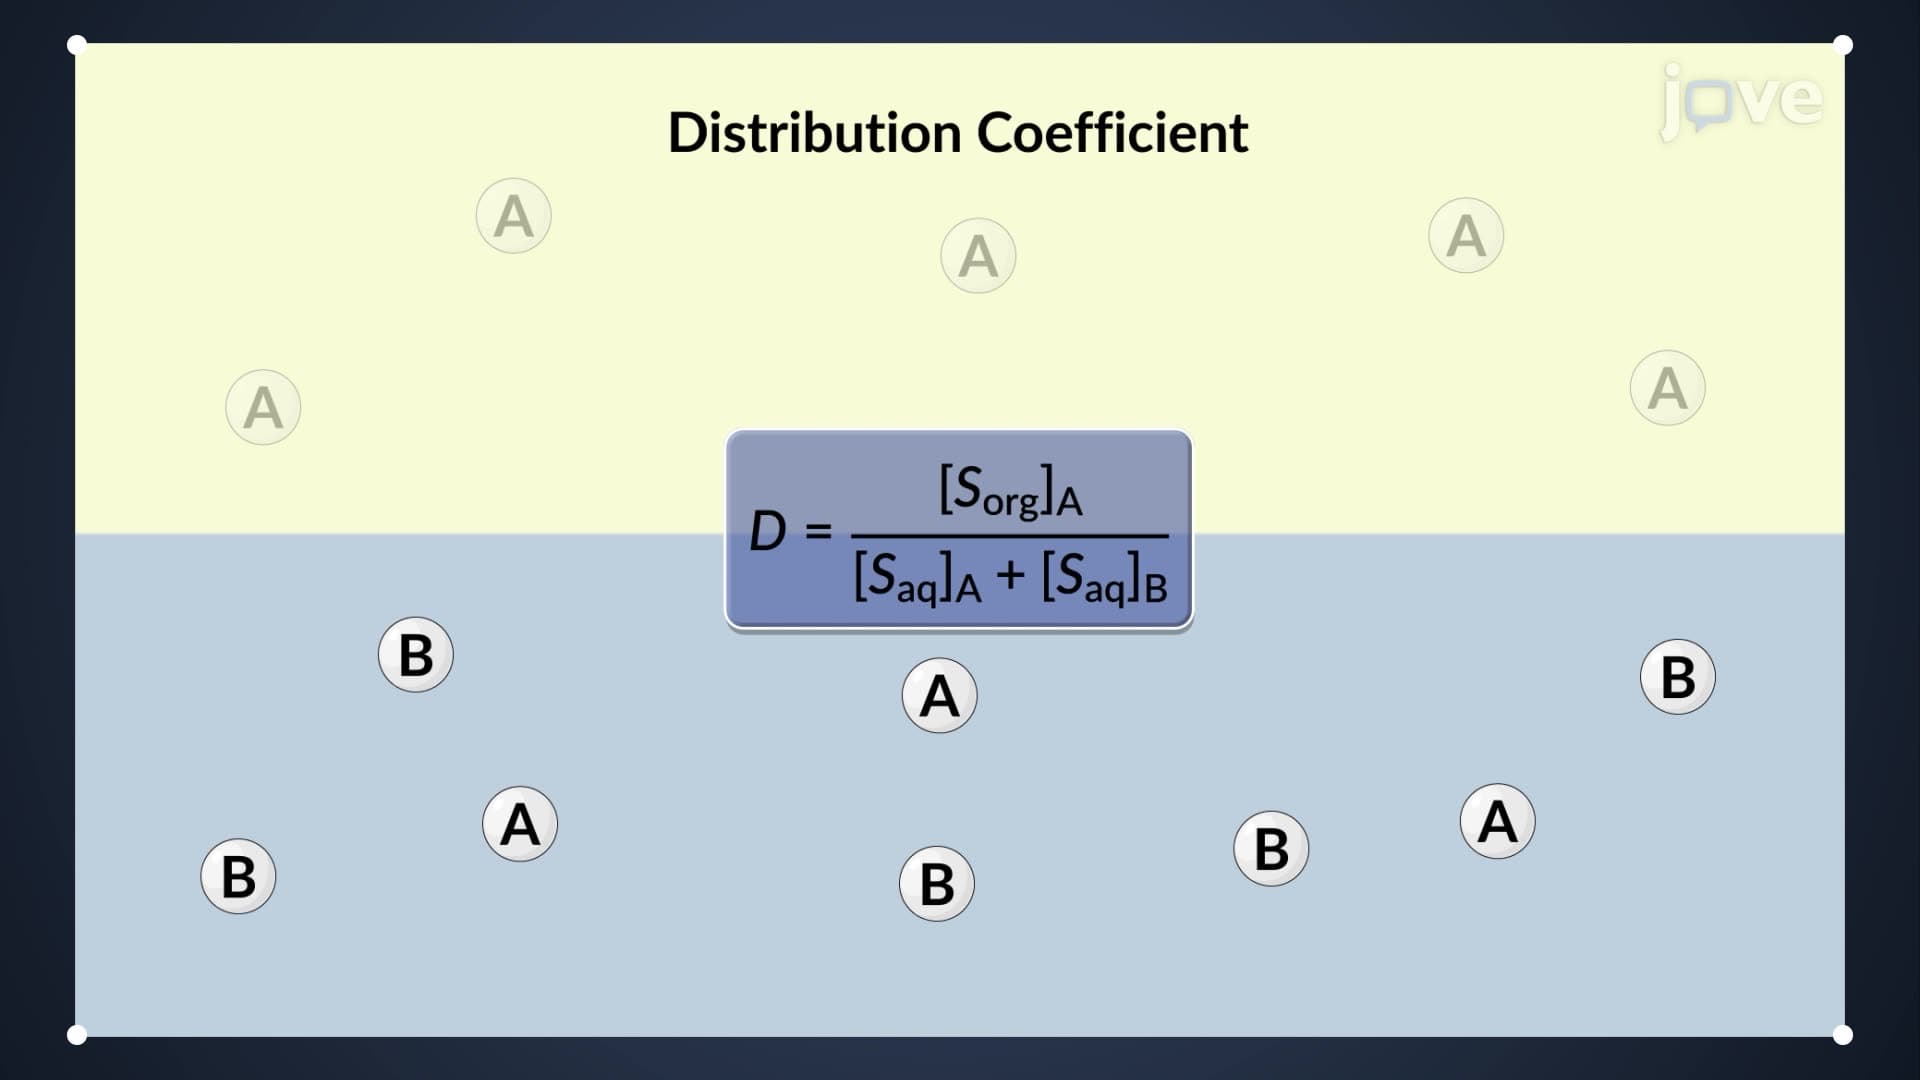
Extraction: Partition and Distribution Coefficients
2.4K
The distribution law or Nernst's distribution law is the law that governs the distribution of a solute between two immiscible solvents. This law, also known as the partition law, states that if a solute is added to the mixture of two immiscible solvents at a constant temperature, the solute is distributed between the two solvents in such a way that the ratio of solute concentrations in the solvents remains constant at equilibrium.
For extracting a solute from an aqueous phase into an...
For extracting a solute from an aqueous phase into an...
2.4K
 02:43
Quantum Numbers
34.6K
It is said that the energy of an electron in an atom is quantized; that is, it can be equal only to certain specific values and can jump from one energy level to another but not transition smoothly or stay between these levels.
34.6K
 01:20
Maxwell-Boltzmann Distribution: Problem Solving
1.5K
Individual molecules in a gas move in random directions, but a gas containing numerous molecules has a predictable distribution of molecular speeds, which is known as the Maxwell-Boltzmann distribution, f(v).
This distribution function f(v) is defined by saying that the expected number N (v1,v2) of particles with speeds between v1 and v2 is given by
This distribution function f(v) is defined by saying that the expected number N (v1,v2) of particles with speeds between v1 and v2 is given by
1.5K
 01:20
Cluster Sampling Method
11.9K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
11.9K