

对于支向量机器来说,一个新的有限损失框架
1College of Mathematics and Statistics, Chongqing University, Chongqing, 401331, China.

概括
这项研究引入了支持向量机 (SVM) 和支持向量回归 (SVR) 的新型边界指数级量子损失 (Leq-loss). 这种新的损失函数增强了对异常值和重新采样的稳定性,提高了模型的稳定性和性能.
科学领域:
- 机器学习 机器学习
- 统计学学习理论
背景情况:
- 支向量机 (SVM) 和支向量回归 (SVR) 是用于分类和回归的强大算法.
- 传统的SVM/SVR可能对异常值和数据扰动敏感,限制了它们的稳定性.
- 现有的损失函数可能无法充分解决这些稳定性问题.
研究的目的:
- 为SVM和SVR引入一个新的有限损失框架.
- 开发一个有界的指数量子损失 (Leq-loss),增强对异常值和重新采样的稳定性.
- 从理论上分析这些属性,并推导出拟议模型的泛化误差界限.
主要方法:
- 设计了一个受限指数量子损失 (Leq-loss),灵感来自Pinball损失.
- 构建了增强的量子支持向量机器 (EQSVM) 和增强的量子支持向量回归 (EQSVR).
- 利用凸过程 (CCCP) 和ClipDCD算法进行优化.
- 使用Rademacher复杂度推导影响函数,分解点下限和概括错误界限.
主要成果:
- Leq-loss显示了SVM和SVR对异常值的增强稳定性.
- 与标准SVM相比,EQSVM显示了对重新采样的更好的稳定性.
- 影响函数被证明是有界的,分解点的下限达到1/2.
- 为EQSVM推导出了泛化误差界限.
结论:
- 拟议的Leq损失框架有效地提高了SVM和SVR的稳定性.
- EQSVM和EQSVR提供了更好的稳定性和可靠性,特别是在有噪音数据的情况下.
- 理论分析支持通过实验证明的实际有效性.

相关概念视频
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:18
Reducing Line Loss
150
In a three-phase circuit, line loss is an indicator of energy dissipated as heat due to the resistance of transmission lines. To address this, incorporating transformers into the system—a step-up transformer at the source and a step-down transformer at the load—is a strategic solution. Two three-phase transformers are introduced to improve this.
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss...
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss...
150
 01:21
Boundary Conditions: Lossless Lines
90
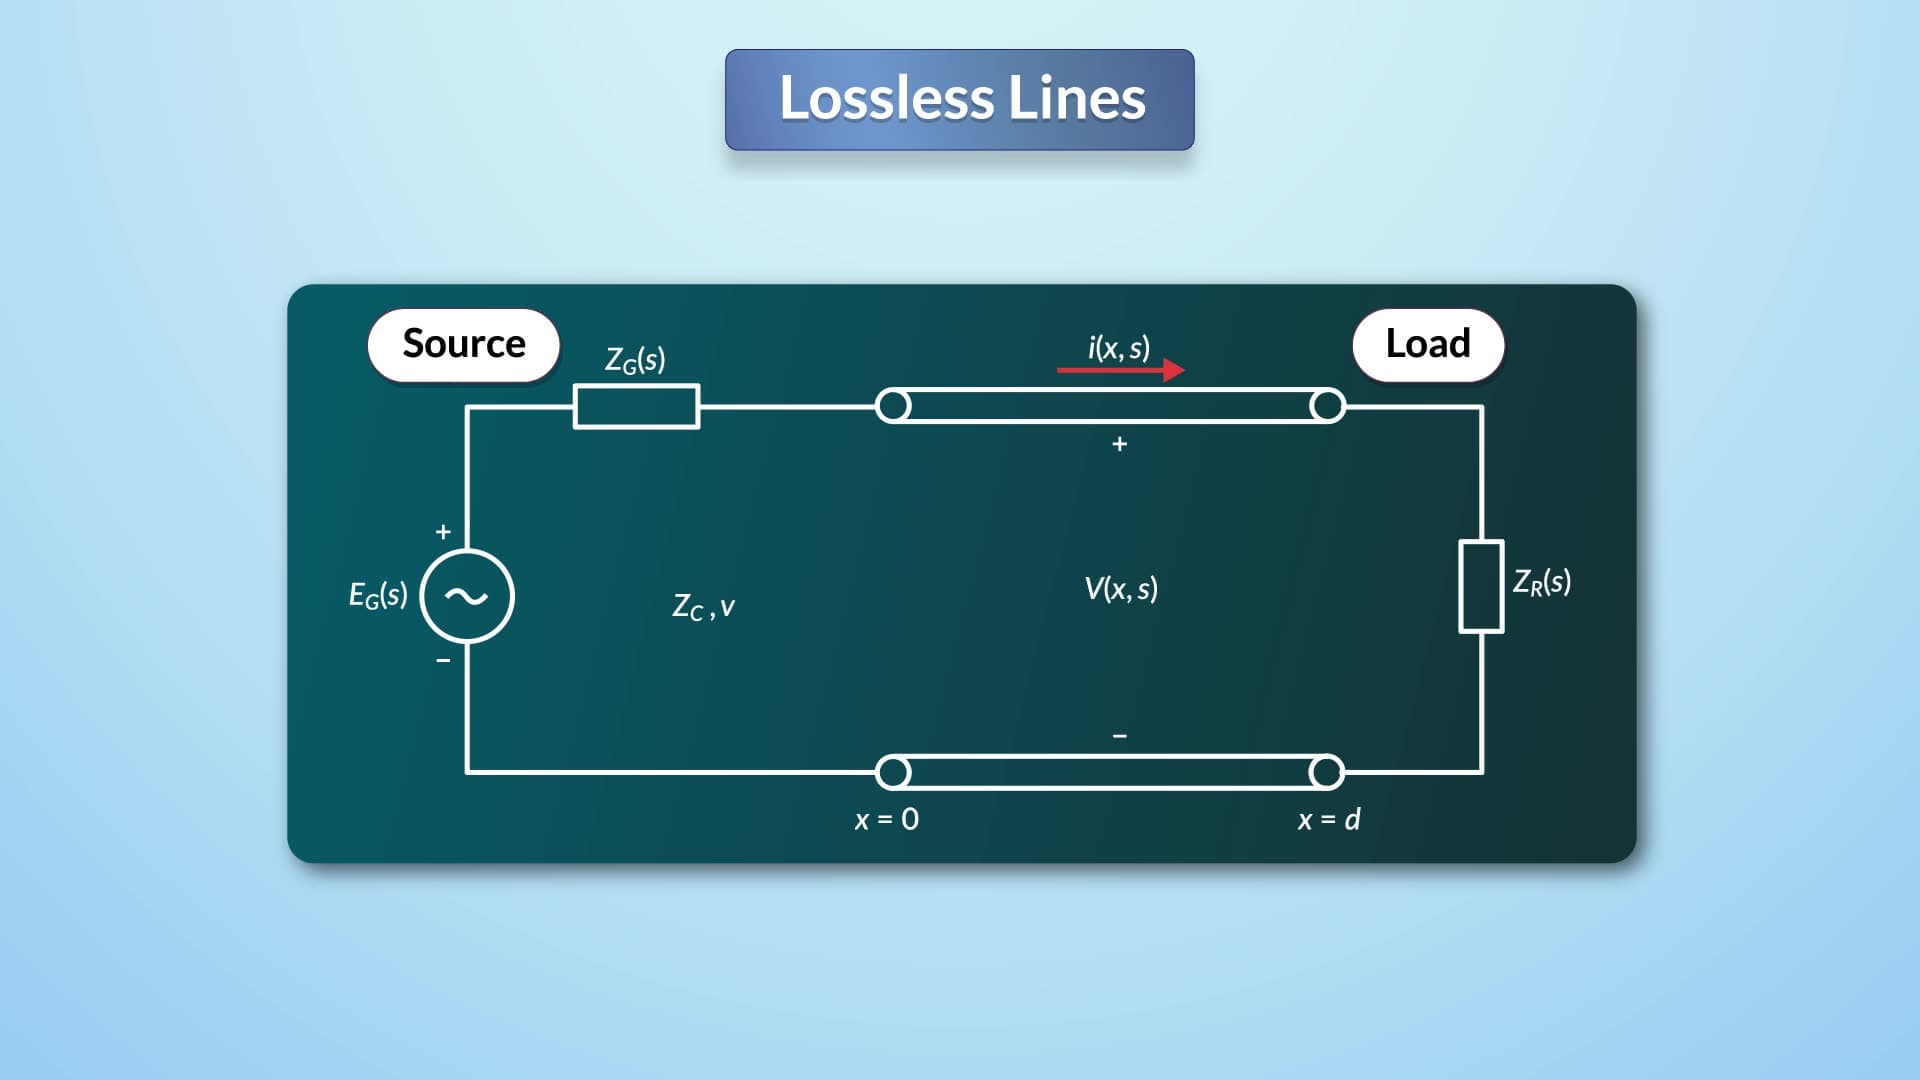
Consider a single-phase, two-wire, lossless transmission line terminated by an impedance at the receiving end and a source with Thevenin voltage and impedance at the sending end. The line, with length, has a surge impedance and wave velocity determined by the line's inductance and capacitance.
At the receiving end, the boundary condition states that the voltage equals the product of the receiving-end impedance and current. This relationship is expressed as a function of the incident and...
At the receiving end, the boundary condition states that the voltage equals the product of the receiving-end impedance and current. This relationship is expressed as a function of the incident and...
90
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:27
Margin of Error
4.0K
The margin of error is also called the maximum error of an estimate. The margin of error is the maximum possible or expected difference between the observed sample parameter value and the actual population parameter value. For proportion, it is the maximum difference between the value of sample proportion obtained from the data and the true value of population proportion. As the true value of the population parameter is not known, the margin of error is calculated using the sample statistic.
4.0K
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K