
分数无otropy是一个更敏感的诊断生物标志物比平均Kurtosis的帕金森病患者与认知功能障碍:一个扩散Kurtosis地图带基于空间统计学研究研究
Bingbing Gao1, Mingrui Qu1, Yuhan Jiang1
1From the Department of Radiology (B.G., M.Q., Y.J., W.l., M.W., C.Y., Y.M), The First Affiliated Hospital of Dalian Medical University, Dalian, China.
AJNR. American journal of neuroradiology
|July 11, 2024

概括
扩散性皮质损伤成像检测了帕金森病患者的白质损伤差异,这些患者有轻度认知障碍和痴呆症. 分数异位变性显示为差异诊断的生物标志物具有前途.
科学领域:
- 神经成像是一种神经成像.
- 神经学 神经学
- 生物标志物 生物标志物
背景情况:
- 帕金森病 (PD) 在各认知状态中表现出异质白质 (WM) 损伤.
- 区分轻度认知障碍PD (PD-MCI) 和痴呆PD (PDD) 之间的区别对于患者管理至关重要.
研究的目的:
- 为了识别敏感的扩散性皮质损伤成像 (DKI) 生物标志物,以区分PD-MCI与PDD中的WM损伤模式.
- 评估DKI指标在区分帕金森病的认知状态的诊断有效性.
主要方法:
- 预计将招募19名PD-MCI和18名PDD患者.
- 获取3D-T1加权和DKIMRI序列. 获得3D-T1加权和DKIMRI序列.
- 使用基于路径的空间统计 (TBSS) 和接收器操作员特征 (ROC) 曲线分析的Voxelwise DKI分析.
主要成果:
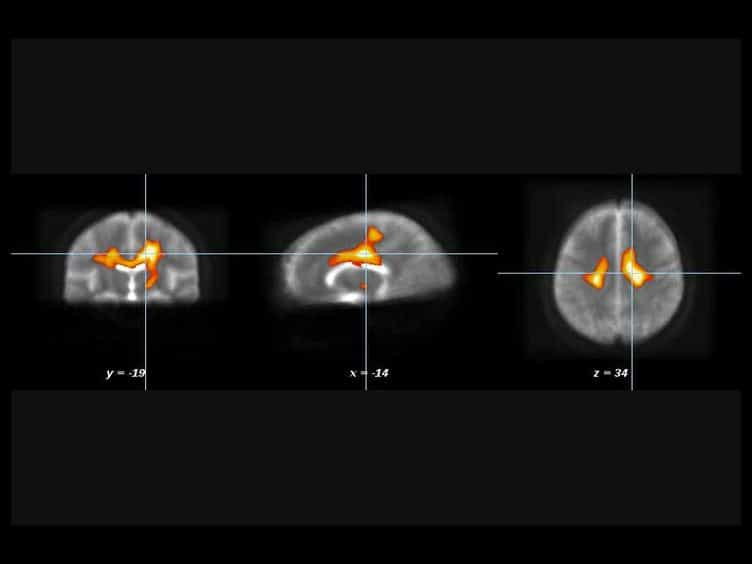
- 与PD-MCI相比,PDD患者在多个WM通道 (例如,小子,下面的前后带) 中显示了分数异构 (FA) 和平均形 (MK) 的降低.
- 在PDD中,子小的平均扩散率 (MD) 降低.
- 在较低的前额尾和较低的纵向中FA显示出高的诊断效率 (0.853) 来区分PD-MCI与PDD.
结论:
- 由DKI衍生出的FA和MK有效地检测PD-MCI和PDD中的明显的WM损伤模式.
- 对于差异诊断,FA是一个比MK更敏感的指标.
- DKI衍生的FA显示出作为一个有前途的成像生物标志物的潜力,用于区分PD-MCI和PDD.
相关概念视频
 01:19
Expected Frequencies in Goodness-of-Fit Tests
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
 01:16
Kendall's Tau Test
Kendall's tau test, also known as the Kendall rank coefficient test, is a nonparametric method for assessing association between two variables. This test is particularly useful for identifying significant correlations when the distributions of the sample and population are unknown. Developed in 1938 by the British statistician Sir Maurice George Kendall, the tau coefficient (denoted as τ) serves as a rank correlation coefficient, with values ranging from -1 to +1.
A τ value of +1 indicates that...
A τ value of +1 indicates that...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This number is...
 01:15
Receiver Operating Characteristic Plot
A ROC (Receiver Operating Characteristic) plot is a graphical tool used to assess the performance of a binary classification model by illustrating the trade-off between sensitivity (true positive rate) and specificity (false positive rate). By plotting sensitivity against 1 - specificity across various threshold settings, the ROC curve shows how well the model distinguishes between classes, with a curve closer to the top-left corner indicating a more accurate model. The area under the ROC curve...
 01:09
Odds Ratio
The odds ratio (OR) is a statistical measure used extensively in epidemiology and research to quantify the strength of association between exposure and outcome across different groups. Unlike relative risk, which compares the probabilities of an event occurring, the odds ratio compares the odds of an event occurring in the exposed group to the odds of it occurring in the unexposed group. The odds, in this context, are calculated as the probability of the event happening divided by the...
 01:24
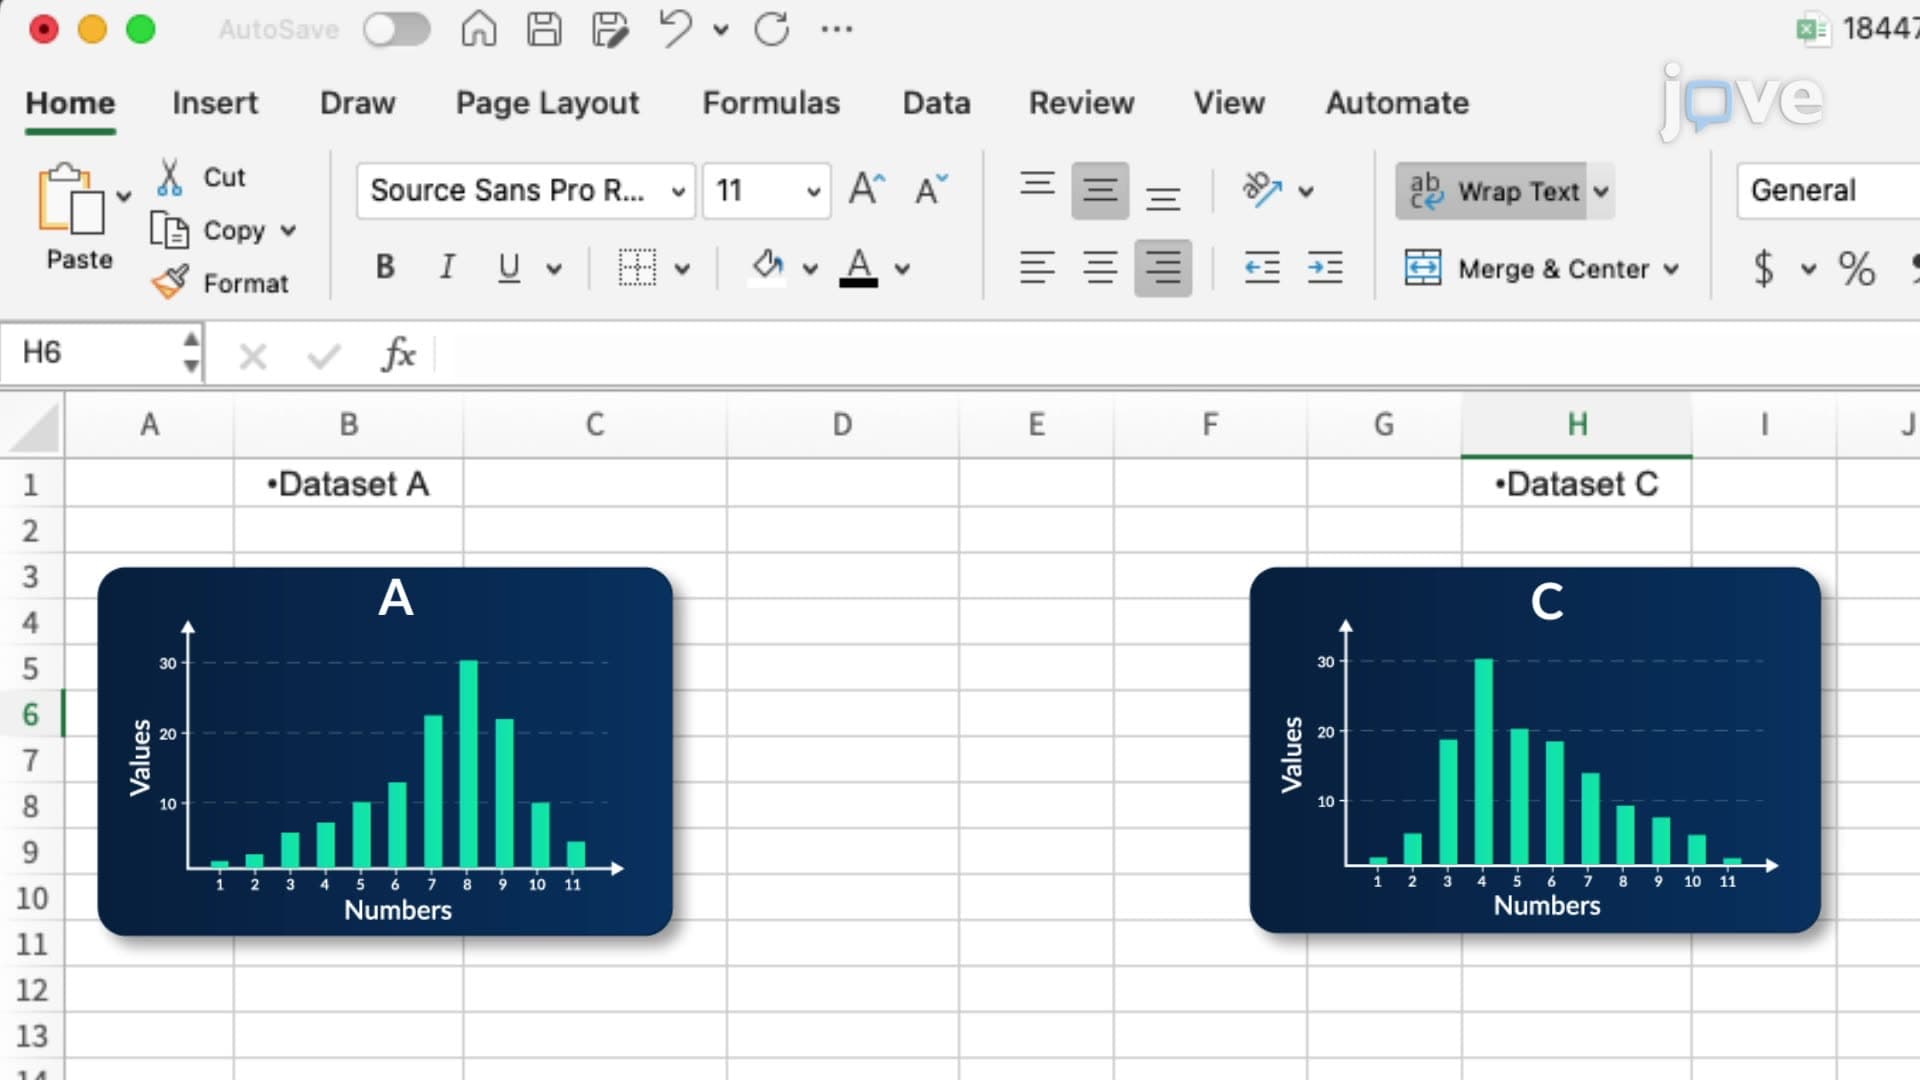
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Central tendency refers to the central point or typical value of a dataset. It summarizes the data set with a single value that represents the center of its distribution. The three main measures of central tendency are:
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...