大型非碎分区非结构化数据的可视化,在高性能计算系统上具有本地分布
IEEE transactions on visualization and computer graphics
|July 15, 2024

概括
在高性能计算 (HPC) 上可视化复杂的模拟数据具有挑战性. 这项研究介绍了一种新的GPU加速染技术,使用射线行进和跟踪来实现有限元素数据的交互可视化.
科学领域:
- 科学可视化科学可视化
- 高性能计算 (HPC) 是一种高性能计算.
- 计算机图形 计算机图形
背景情况:
- 在HPC系统上可视化大型有限元模拟数据,由于非结构化数据和非形域,因此存在染挑战.
- 数据并行染与跨越域边界的射线作斗争,影响射线行进和构成.
- 现有的方法在复杂的几何形状和分布式染环境中遇到困难.
研究的目的:
- 开发一种高效,交互式的可视化技术,用于HPC系统上的大规模有限元模拟数据.
- 为了应对染非结构化数据和处理域跨越并行染的挑战.
- 为了实现复杂的模拟结果的实时或近实时视觉分析.
主要方法:
- 采用GPU优化的光线行进技术,并采用基于XOR的压缩方案,以实现高性能光线穿越.
- 集成硬件加速射线跟踪,以有效地确定射线进入模拟领域的入口点.
- 使用"深度"组合方案,准确地将不同处理单元 (等级) 的染结果合并.
- 利用GPU对GPU远程直接内存访问 (RDMA) 进行高效的数据传输和同步.
主要成果:
- 在Fun3D NASA火星着陆器用例中实现了每秒10-15的交互式速.
- 证明了组合技术在克服与非结构化数据相关的染瓶方面的有效性.
- 在数据平行上下文中成功处理了复杂的空间域边界和光线跨越问题.
结论:
- 拟议的整体方法有效地在HPC系统上交互可视化大型有限元模拟数据.
- 优化射线行进,射线跟踪和深度构成的组合为复杂的可视化任务提供了强大的解决方案.
- 这种技术显著提高了HPC资源的可用性,用于科学数据的探索和分析.
相关概念视频
 01:14
Extraction: Partition and Distribution Coefficients
2.4K
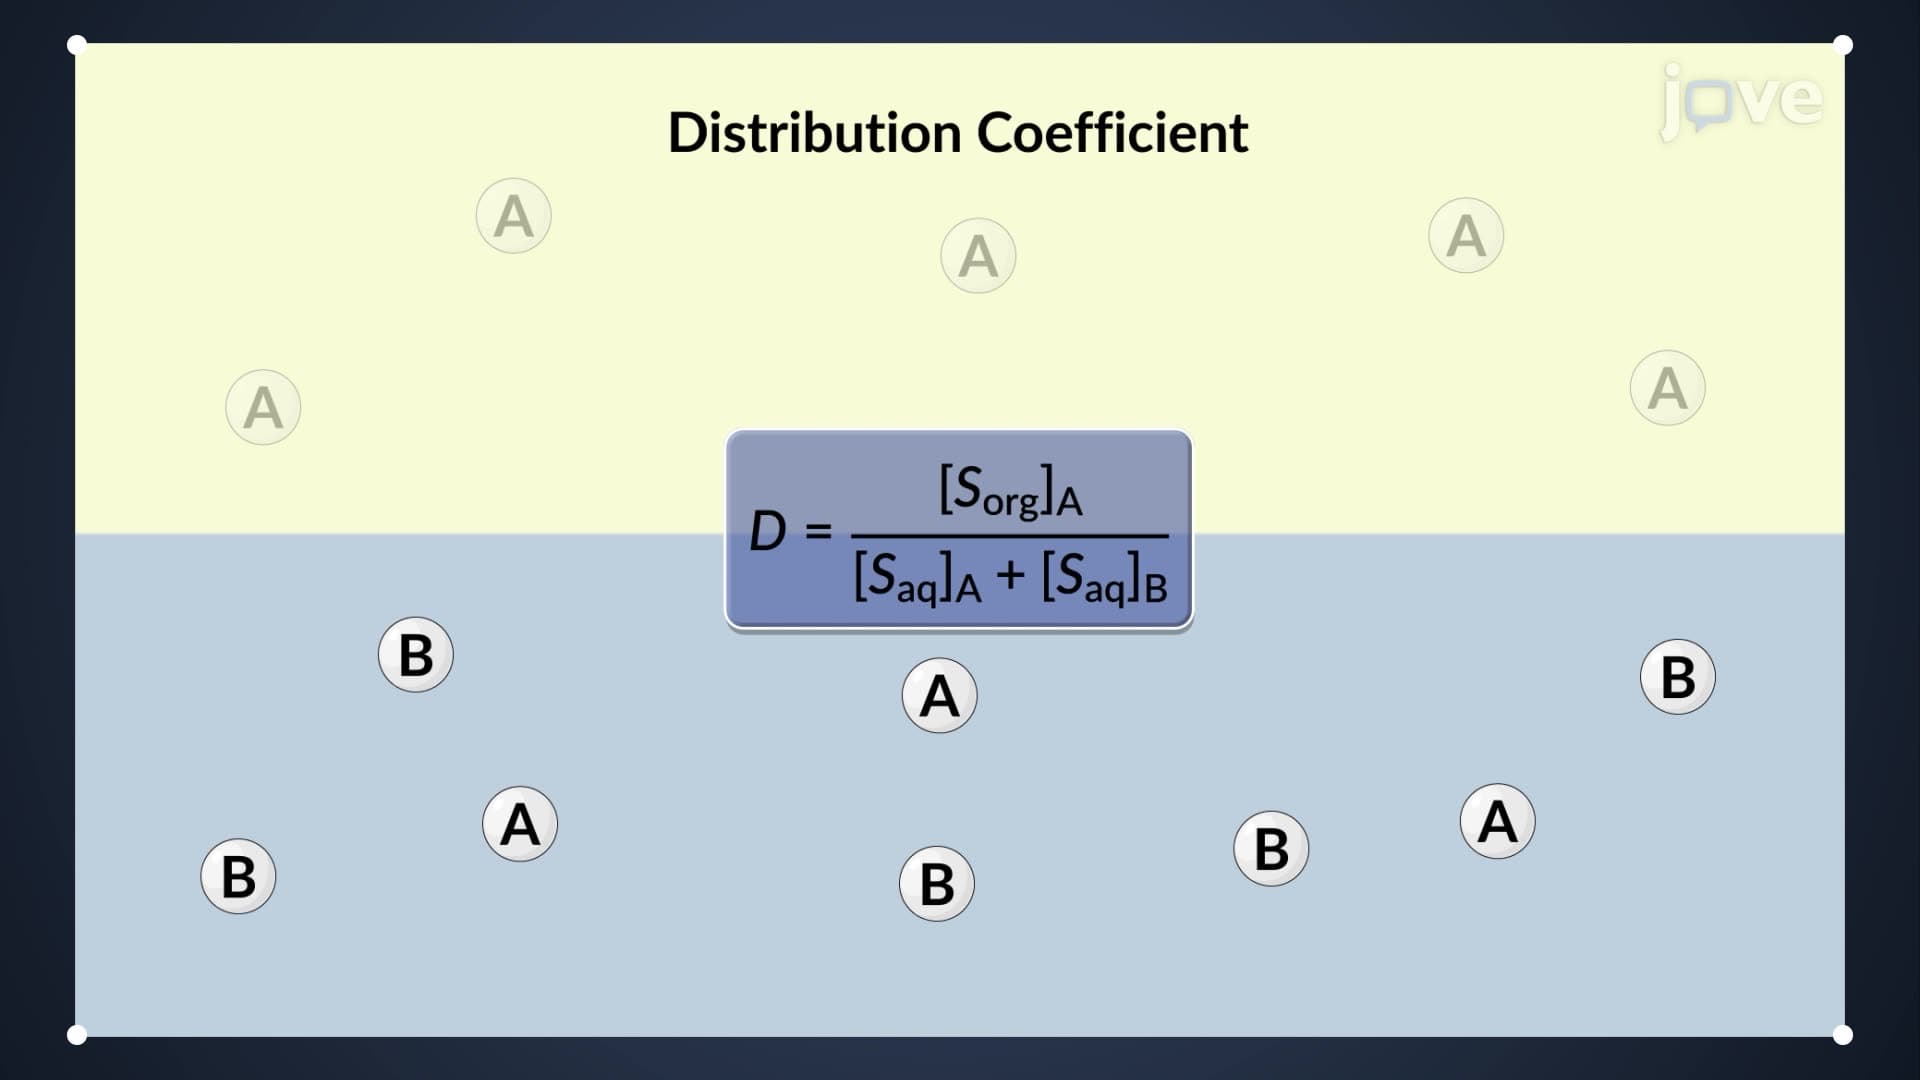
The distribution law or Nernst's distribution law is the law that governs the distribution of a solute between two immiscible solvents. This law, also known as the partition law, states that if a solute is added to the mixture of two immiscible solvents at a constant temperature, the solute is distributed between the two solvents in such a way that the ratio of solute concentrations in the solvents remains constant at equilibrium.
For extracting a solute from an aqueous phase into an...
For extracting a solute from an aqueous phase into an...
2.4K
 01:19
Data: Types and Distribution
714
In biostatistics, data are the observations collected for analysis. There are two main types: parametric and non-parametric. Parametric data, which include continuous (e.g., weight) and discrete numerical data (e.g., number of tablets), assume a particular distribution pattern, often the normal distribution. Non-parametric data do not adhere to a specific distribution and typically comprise nominal (e.g., gender) and ordinal categorical data (e.g., pain scale ratings).
Distributions in...
Distributions in...
714
 01:10
Statgraphics
122
Statgraphics is a comprehensive statistical software suite designed for both basic and advanced data analysis. Originating in 1980 at Princeton University under Dr. Neil W. Polhemus, it was one of the pioneering tools for statistical computing on personal computers, with its public release in 1982 marking an early milestone in data science software. Over the years, it has evolved into a robust platform for data science, offering tools for regression analysis, ANOVA, multivariate statistics,...
122
 01:20
Parallel Processing
150
The brain processes sensory information rapidly due to parallel processing, which involves sending data across multiple neural pathways at the same time. This method allows the brain to manage various sensory qualities, such as shapes, colors, movements, and locations, all concurrently. For instance, when observing a forest landscape, the brain simultaneously processes the movement of leaves, the shapes of trees, the depth between them, and the various shades of green. This enables a quick and...
150
 01:05
Histogram
12.9K
The histogram is a graphical representation in the x-y form of data distribution in a data set. The horizontal x-axis is labeled with what the data represents (for instance, distance from your home to school). The vertical y-axis is labeled either frequency or relative frequency (or percent frequency or probability).
A histogram graph consists of contiguous (adjoining) boxes. The heights of the bars correspond to frequency values. The graph will have the same shape with respective labels. The...
A histogram graph consists of contiguous (adjoining) boxes. The heights of the bars correspond to frequency values. The graph will have the same shape with respective labels. The...
12.9K
 01:17
Probability Histograms
11.2K
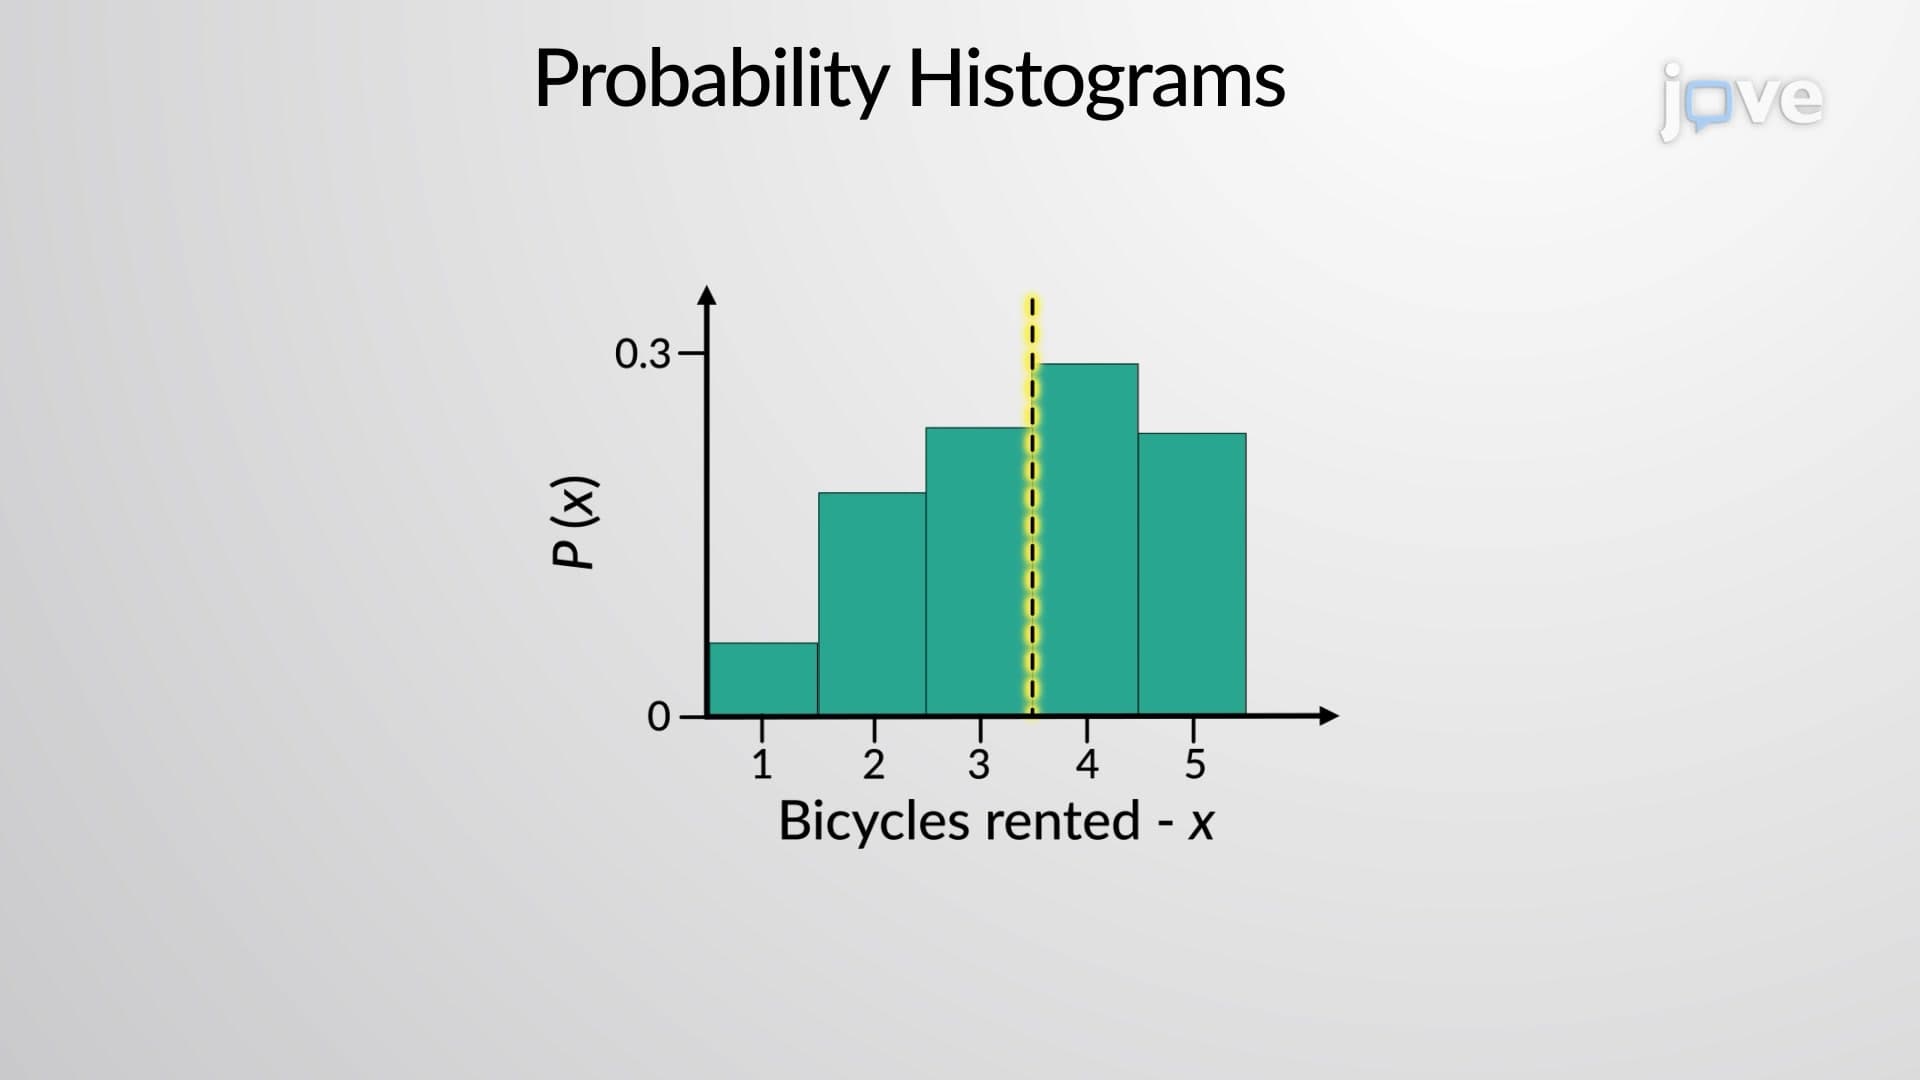
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
11.2K