
机器学习方法用于识别下游沉积物中重金属污染的空间因素及其影响距离
Dong Hoon Lee1, Sang-Il Lee1, Joo-Hyon Kang1
1Department of Civil and Environmental Engineering, Dongguk University-Seoul, Seoul 04620, Republic of Korea.
The Science of the total environment
|July 18, 2024

概括
机器学习模型确定了河流沉积物中的重金属污染源. 随机森林分类器准确地预测了沉积物质量,揭示了关键污染源及其影响距离,以便有效管理.
科学领域:
- 环境科学 环境科学
- 地质化学 地质化学
- 数据科学数据科学数据科学
背景情况:
- 污染的沉积物对水生生态系统构成风险,需要确定来源.
- 沉积物中的重金属污染需要有效的管理策略.
研究的目的:
- 开发和评估机器学习模型,用于识别下游沉积物中的重金属来源及其影响距离.
- 利用高地环境变量来预测沉积物污染水平.
主要方法:
- 使用的分类模型:人工神经网络 (ANN) 和随机森林 (RF).
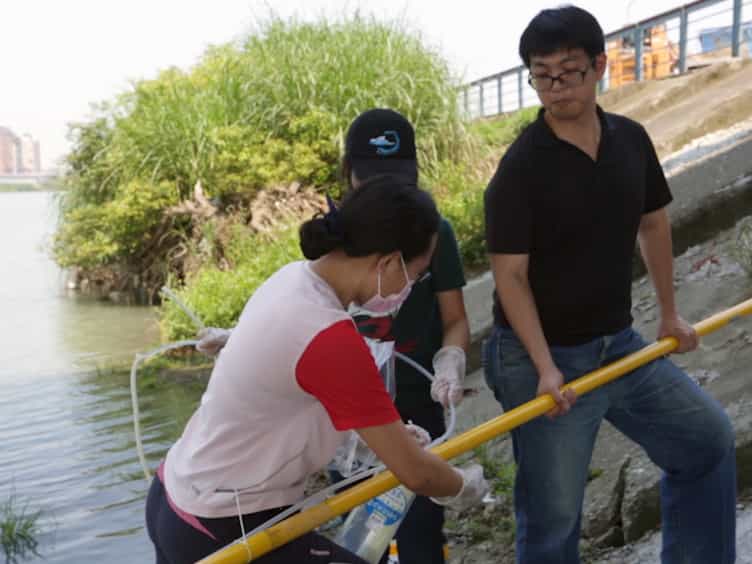
- 利用一个全国性的韩国数据库 (1546个数据集) 采集了来自160个流点的8种重金属 (Ar,Cd,Cr,Cu,Hg,Ni,Pb,Zn) (2014-2018).
- 使用不同的缓冲半径和流域边界评估模型准确性;用于射频模型,采用了自适应合成过量采样 (ORFC).
主要成果:
- 采用自适应合成过量采样 (ORFC) 的射频分类器实现了基于加拿大沉积物质量指南的沉积物质量类的良好预测准确性 (0.67-0.94).
- 确定了重金属的最佳影响距离;Cd,Cu和Pb显示较短的距离 (1.5-2.0公里).
- 确定的主要污染驱动因素:Hg和Ni的高地土壤;Pb和Zn的住宅区和道路.
结论:
- 机器学习,特别是ORFC,可以有效地识别河流沉积物的重金属来源和有影响力的距离.
- 这些发现为优先考虑污染的河流沉积物的管理工作提供了关键信息.
- 该研究强调了高地土地利用和土壤条件在沉积物污染中的重要性.
相关概念视频
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
36
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
36
 00:56
Extraction: Advanced Methods
438
Metal ions can be separated from one another by complexation with organic ligands–the chelating agent– to form uncharged chelates. Here, the chelating agent must contain hydrophobic groups and behave as a weak acid, losing a proton to bind with the metal. Since most organic ligands used in this process are insoluble or undergo oxidation in the aqueous phase, the chelating agent is initially added to the organic phase and extracted into the aqueous phase. The metal-ligand complex is...
438