权衡美国我们所有人研究计划数据与已知的人口估计,使用
Vivian Hsing-Chun Wang1, Jingwen Lei2, Tingjia Shi2
1Center for Population Health & Health Services Research, Department of Foundations of Medicine, NYU Grossman Long Island School of Medicine, Mineola, NY, USA.
Preventive medicine reports
|July 19, 2024

概括
为了提高数据的代表性,为我们所有人的研究计划生成了调查权重. 削减少了我们所有人的估计和国家健康数据之间的差异,增强了人口健康研究潜力.
科学领域:
- 医疗保健服务研究 医疗服务研究
- 生物统计学 生物统计学
- 人口健康 人口健康
背景情况:
- 我们所有人研究计划收集来自美国多样化人口的纵向健康数据.
- 自愿参与对人口层面的健康见解的国家代表性提出了挑战.
- 开发准确的调查权重对于解决我们所有人的数据中抽样偏差至关重要.
研究的目的:
- 为我们所有人的数据集生成调查权重.
- 为了提高我们所有人的研究结果的全国代表性.
- 在人口层面上提高健康和医疗保健估计的准确性.
主要方法:
- 使用我们所有人共同的人口,健康和社会经济变量以及国家健康访谈调查 (NHIS) 开发了重量.
- 分析了100391名所有我们参与者 (18岁以上) 的样本.
- 我们所有人 (未加权和加权) 的流行率估计与NHIS加权估计进行了比较.
主要成果:
- 程序包含了诸如年龄,性别,种族/民族,收入和房屋所有权等变量.
- 在健康变量方面,采用重减小了"我们所有人"和NHIS估计之间的平均百分比差异18.89%.
- 与健康相关的流行率估计的可比性得到了显著改善.
结论:
- 削有效地提高了我们所有人的数据与国家流行率估计的可比性.
- 进一步精细化用于的变量选择可能会产生更大的可比性.
- 产生的权重对于解决"我们所有人"数据集中的代表性挑战有价值.
相关概念视频
 00:57
Weighted Mean
5.1K
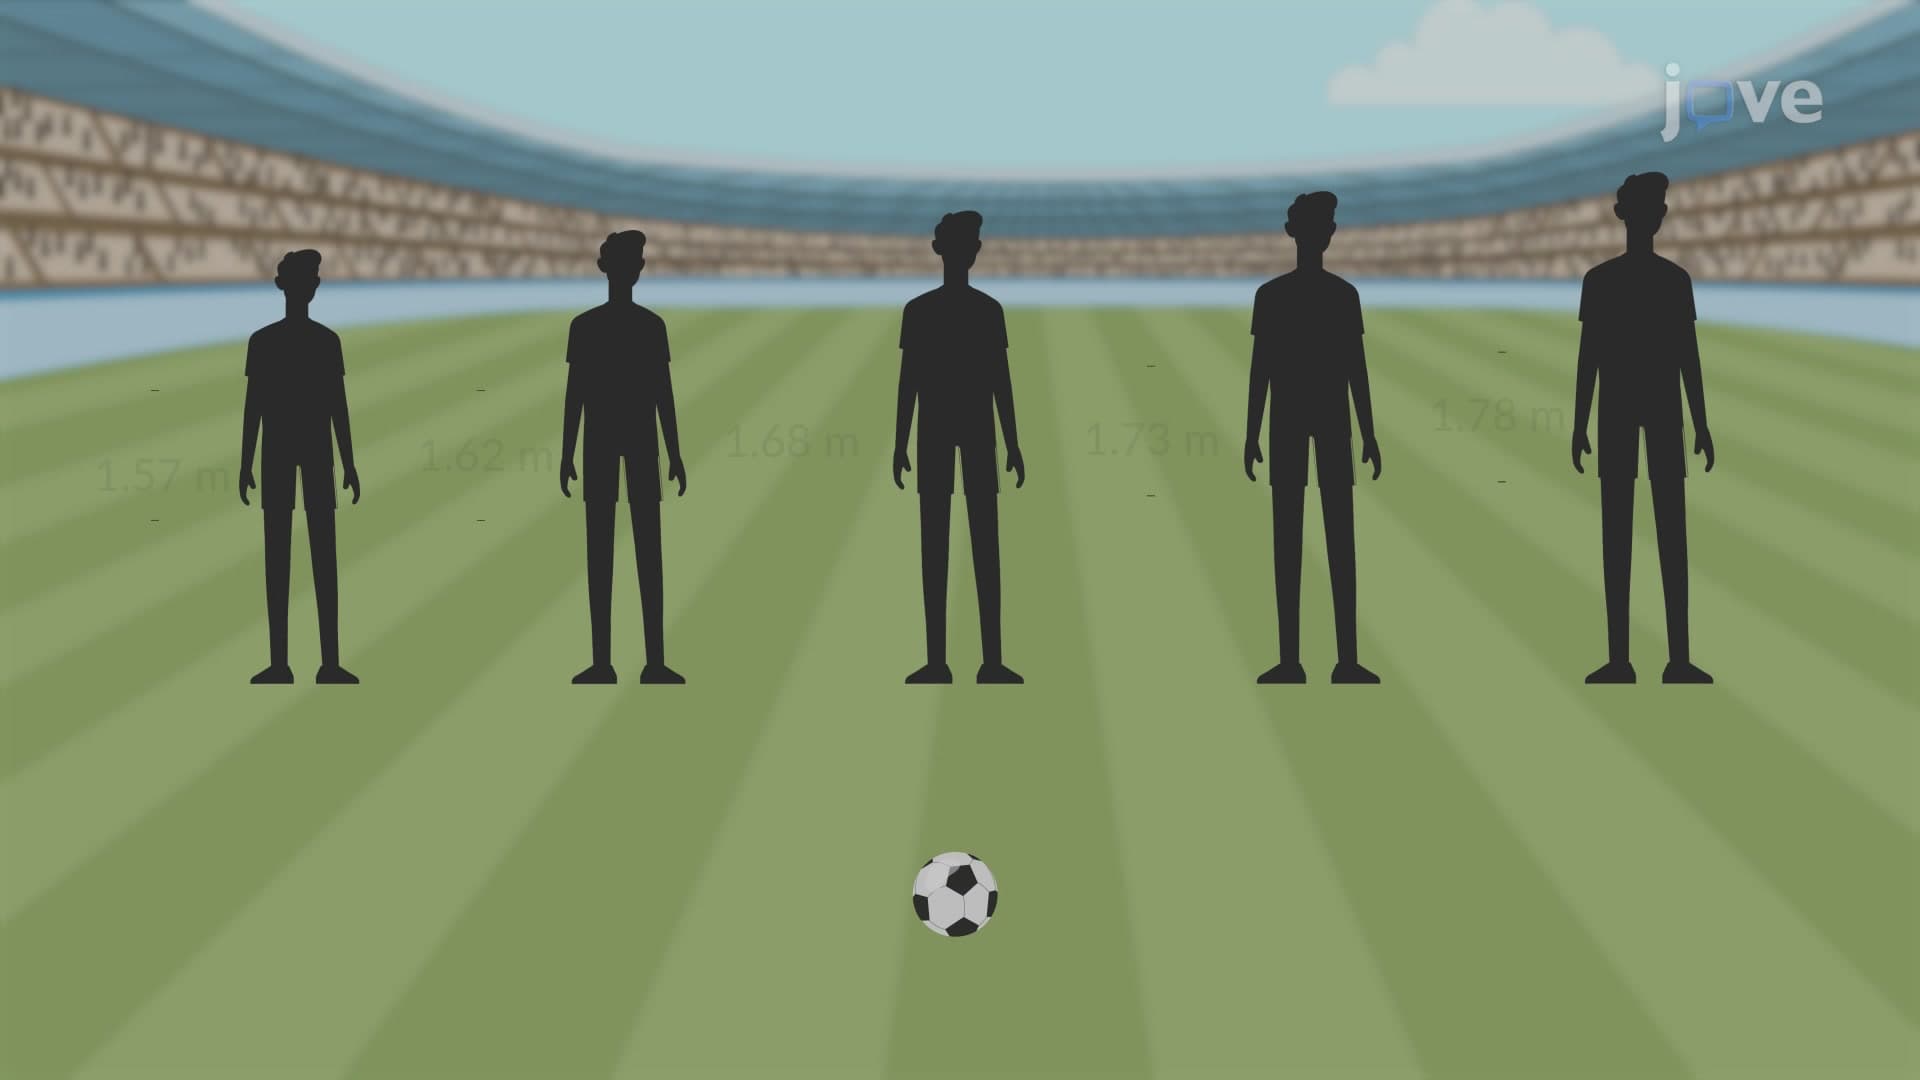
While taking the arithmetic, geometric, or harmonic mean of a sample data set, equal importance is assigned to all the data points. However, all the values may not always be equally important in some data sets. An intrinsic bias might make it more important to give more weightage to specific values over others.
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
5.1K
 01:11
Introduction to R
260
R is a powerful software environment for statistical computing and graphics. Originating as an implementation of the S language, developed at Bell Laboratories, R has evolved into a robust, open-source statistical software favored by statisticians and data scientists worldwide. Its comprehensive suite includes data manipulation, calculation, and graphical display capabilities, making it versatile for data analysis and visualization. Its programming language is at the core of R's...
260
 01:25
Statistical Methods for Analyzing Epidemiological Data
346
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
346
 01:16
Stratified Sampling Method
11.9K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a stratified sample, divide the population into groups called strata and then take a...
To choose a stratified sample, divide the population into groups called strata and then take a...
11.9K
 01:12
Coefficient of Correlation
6.1K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable x and the dependent variable y.
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
6.1K
 01:20
Biostatistics: Overview
230
Biostatistics plays a crucial role in understanding and analyzing data in healthcare and biology. Biostatisticians conduct experiments, gather evidence, and draw meaningful conclusions using statistical methods and techniques. Different variables form the foundation of biostatistical analysis, allowing researchers to understand and interpret data effectively. These variables are classified into different types, each serving a specific purpose in statistical analysis.
Discrete variables are...
Discrete variables are...
230