
用高维数据构建预测模型的重复选
1Department of Biostatistics and Bioinformatics, Duke University, Durham, NC 27708, USA.
Journal of personalized medicine
|July 27, 2024

概括
一种新的重复选方法通过选择比LASSO和弹性网更少,更重要的变量来改善患者结果预测. 这种机器学习方法提高了预测准确性,并降低了未来的数据收集成本.
科学领域:
- 生物统计学 生物统计学
- 机器学习 机器学习
- 个性化医疗是个性化的医疗.
背景情况:
- 准确的患者结果预测对于个性化医学至关重要.
- 高维数据 (基因组学,EHR) 需要对预测模型进行有效的变量选择.
- 像LASSO和弹性网这样的现有方法可以过度选择特征,影响模型的准确性和成本.
研究的目的:
- 引入和评估一种新的机器学习方法,重复选,用于高维数据中的变量选择.
- 将重复选的性能与LASSO和弹性网等既有方法进行比较.
- 评估变量选择对预测准确度和未来数据收集成本的影响.
主要方法:
- 提出了一种重复选机器学习方法,将回归扩展到逐步变量选择.
- 与LASSO (L1-规范处罚) 和弹性网 (L1/L2-规范处罚) 进行反复选的比较.
- 评估方法使用广泛的数值研究和现实世界的数据示例.
主要成果:
- 与LASSO和弹性网相比,重复选的特征明显少.
- 提出的方法显示了比现有的机器学习方法更高的预测准确性.
- 数字研究和真实数据证实了重复选的优越性能.
结论:
- 重复选方法在高维数据的变量选择和预测准确性方面提供了卓越的性能.
- 这种方法有效地解决了其他机器学习方法中常见的过度选择问题.
- 重复选可以降低与预测模型的未来数据收集相关的成本.
相关概念视频
 01:19
Sieve Analysis and Grading Curves
327
Sieve analysis is a method used to determine the particle size distribution of aggregate materials. This process involves the following steps:
327
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
448
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
448
 01:07
End Point Prediction: Gran Plot
305
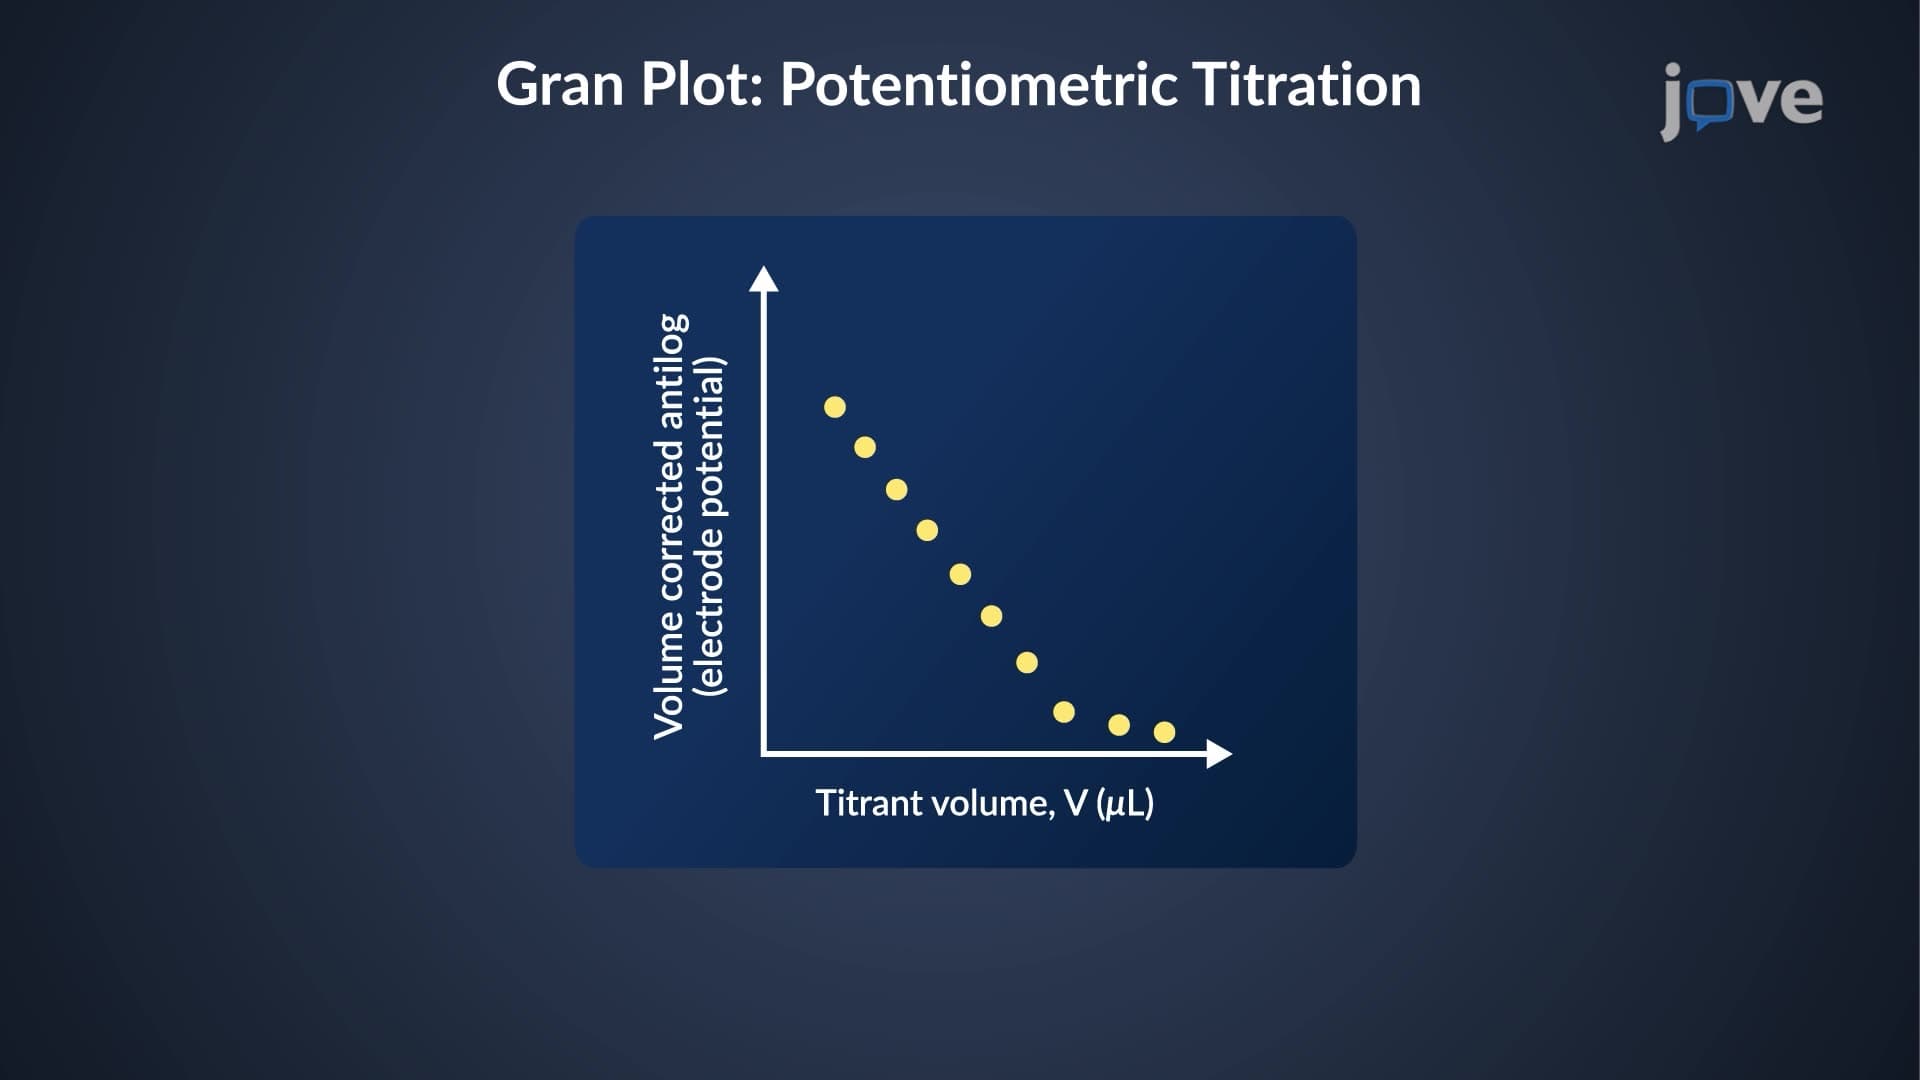
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
305
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K