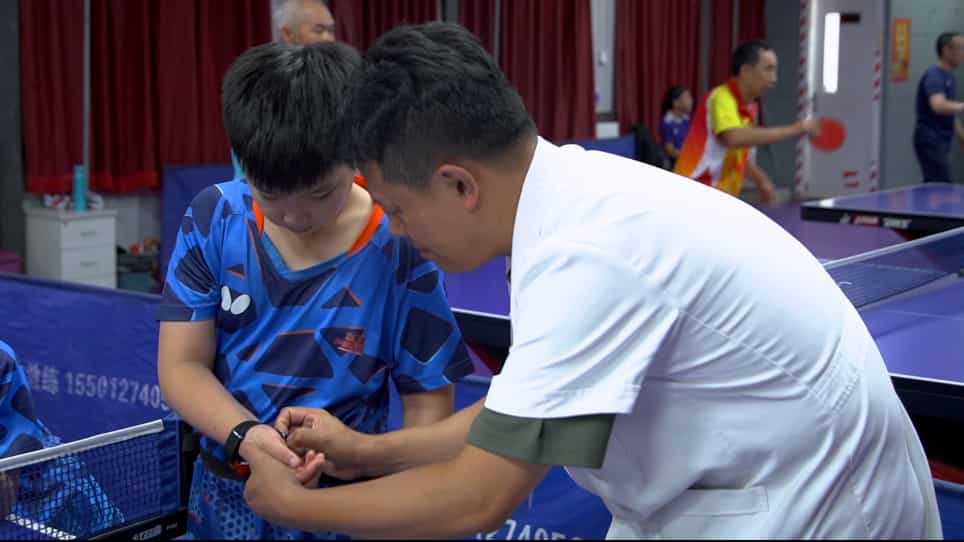

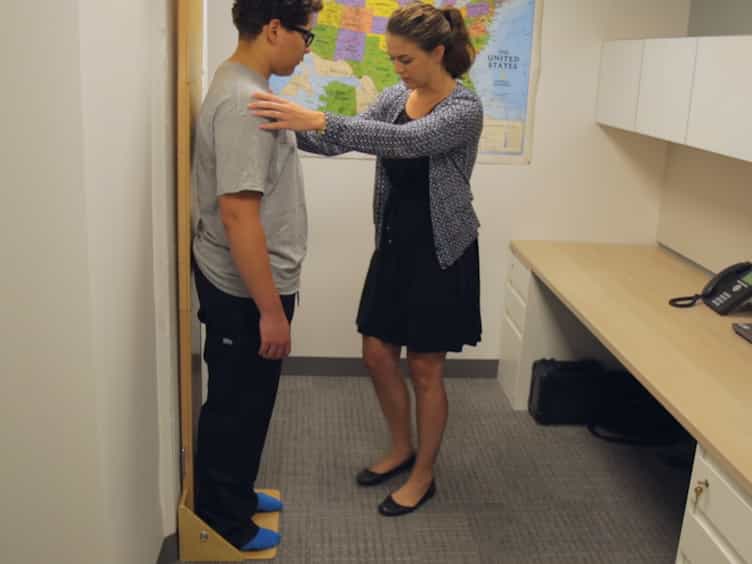
儿童膝盖高度方程的预测精度的比较
Matthew Edwards1, Mary B Feuling1, Alan Silverman2
1Children's Wisconsin, Milwaukee, Wisconsin, USA.
Journal of pediatric gastroenterology and nutrition
|July 29, 2024

概括
鲁马佩亚方程准确地估计了7-12岁儿童的站立高度,当直接测量是不可能的. 对于这个儿科患者群体来说,Chumlea方程证明是不可靠的.
科学领域:
- 儿科人类测量 儿科人类测量
- 生物识别估计的估计.
背景情况:
- 在儿科患者群体中,站立身高测量可能具有挑战性.
- 膝盖高度是估计身高的可行的替代人体测量方法.
- 现有的方程,如Chumlea和Rumapea,用于此估计.
研究的目的:
- 为了比较Chumlea和Rumapea方程在估计儿童从膝盖高度站立的高度时的准确性.
- 确定哪个方程在儿科人口中提供更可靠的身高测量方法.
主要方法:
- 预计将招收210名年龄在7-12岁的儿童,没有脊椎形.
- 测量所有参与者的膝盖高度和站立高度.
- 估计高度 (Chumlea和Rumapea方程) 与实际站立高度的统计比较,使用双尾T测试.
主要成果:
- 鲁马佩亚方程在估计站立高度方面表现出可靠性 (p = 0.878).
- 查米利亚方程被发现是不可靠的 (p = 0.0376).
- 在不同性别和种族之间,Rumapea方程显示出比Chumlea方程更高的准确性.
结论:
- 鲁马佩亚方程是一种可靠且准确的方法,用于估计美国7-12岁儿童的站立高度.
- 在这个年龄组中,不建议使用Chumlea方程来估计站立的身高.
- 准确的身高估计对于监测儿童的成长和健康至关重要.
相关概念视频
 02:32
Variation: Normal Distribution, Range, and Standard Deviation
22.2K
In the field of psychology, there are several ways to organize measurements of a trait, feature, or characteristic (i.e., variables). Qualitative data, such as ethnicity, can be tabulated into a frequency count to provide information about the proportion, as well as the variety of groups in a sample or population. On the other hand, researchers can perform a wider set of calculations on quantitative data. The mean, mode, and median, for instance, are central tendency measures to identify a...
22.2K
 01:15
One-Way ANOVA: Unequal Sample Sizes
5.7K
One-way ANOVA can be performed on three or more samples of unequal sizes. However, calculations get complicated when sample sizes are not always the same. So, while performing ANOVA with unequal samples size, the following equation is used:
5.7K
 01:12
Coefficient of Correlation
6.1K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable x and the dependent variable y.
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
6.1K
 01:19
Variation
6.8K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
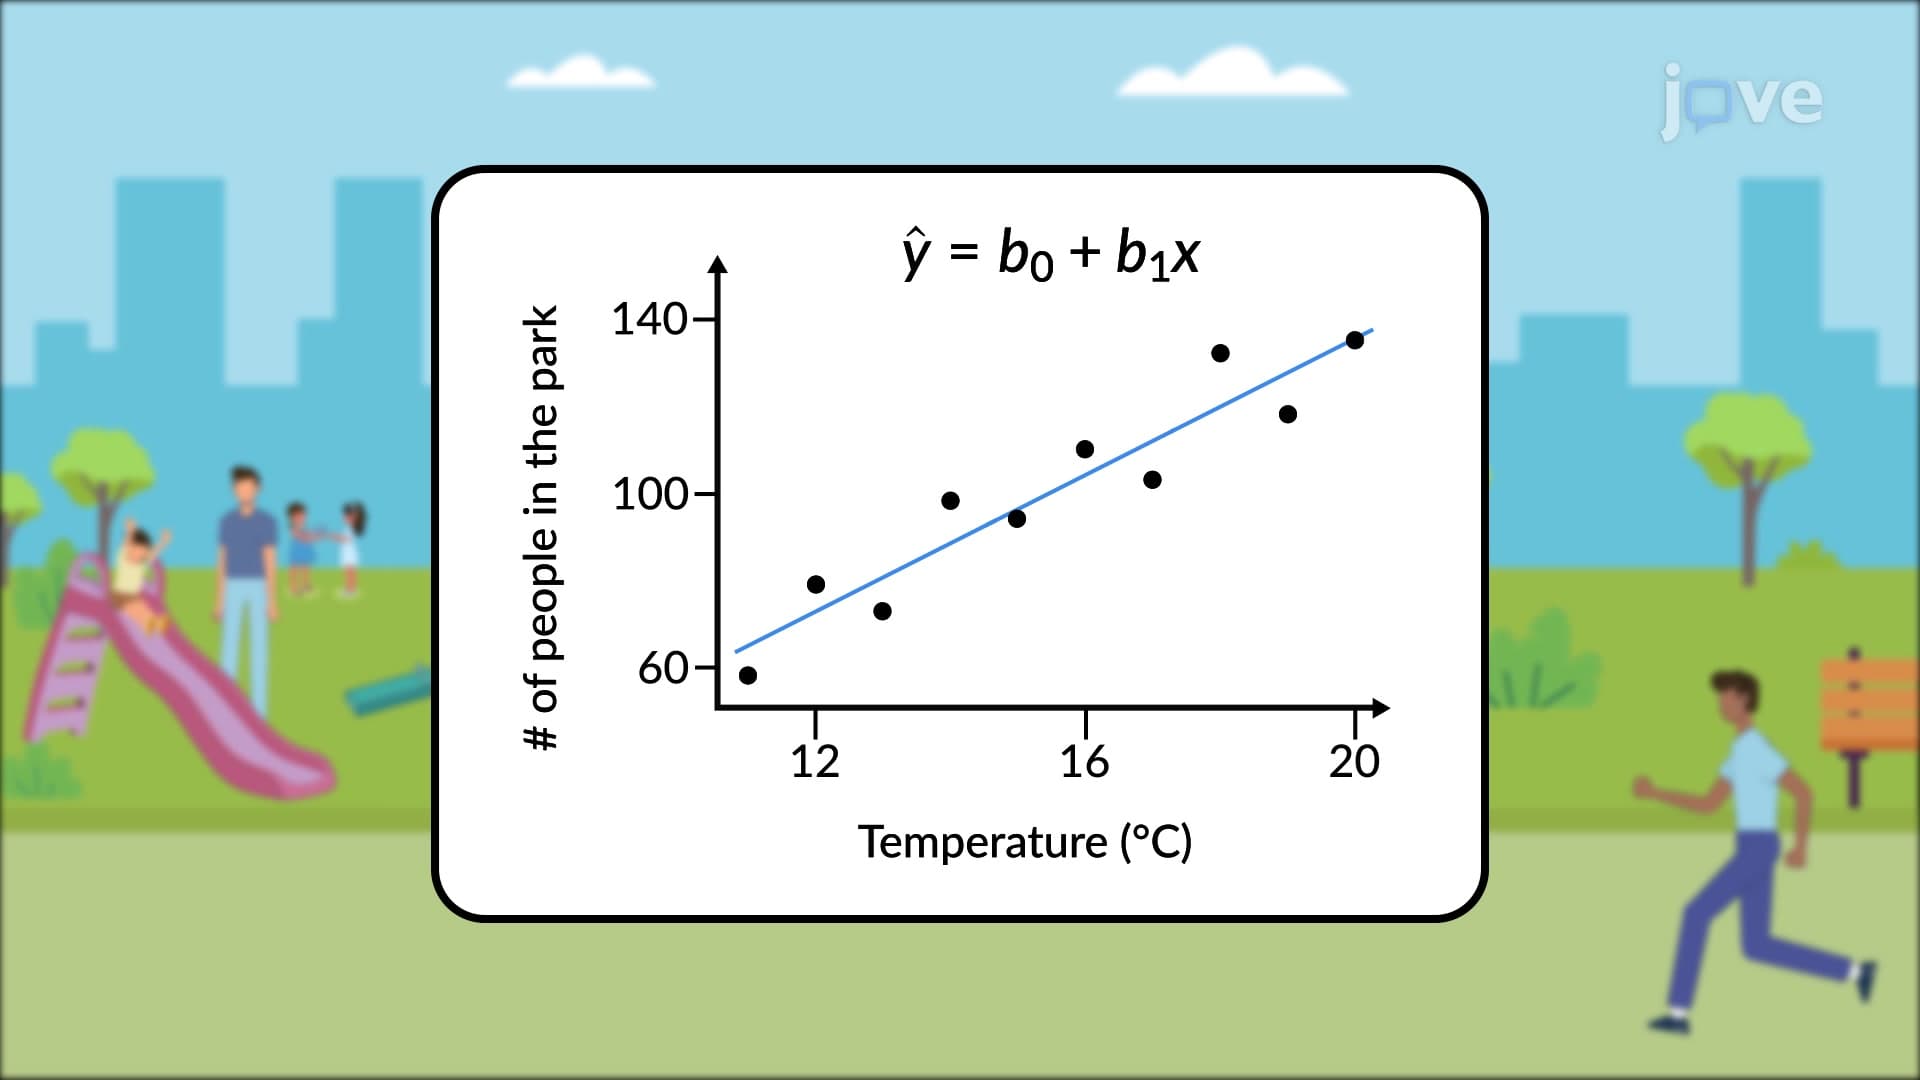
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.8K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K