

群众的智慧与部分排名:贝叶斯的方法在JAGS中实施了瑟斯通模型
Lauren E Montgomery1, Nora Bradford1, Michael D Lee2
1Department of Cognitive Sciences, University of California Irvine, Irvine, CA, 92697-5100, USA.
Behavior research methods
|July 30, 2024

概括
我们创建了一个贝叶斯方法,使用瑟斯通模型汇总部分排名. 这种方法从不完整的数据中推断出真正的排名和个人专业知识,适用于各种数据集.
科学领域:
- 统计 统计 统计 统计
- 计算社会科学 计算社会科学
- 心理测量 心理测量 心理测量
背景情况:
- 聚合部分排名数据是一项挑战.
- 现有的方法可能无法有效处理不完整或多样化的子集排名.
- 从部分数据中了解真正的项目顺序和个人专业知识至关重要.
研究的目的:
- 开发一种灵活的贝叶斯方法来聚合部分排名数据.
- 从不完整的排名中推断潜在的真实排名和个人专业知识.
- 为了证明该方法在不同的部分排名数据收集方案中的有效性.
主要方法:
- 使用瑟斯通模型开发了贝叶斯方法.
- 在JAGS (Just Another Gibbs Sampler) 中实现该模型作为图形模型.
- 设计实验以收集各种形式的部分排名数据.
主要成果:
- 贝叶斯方法有效地从实验中聚合了部分排名数据.
- 该方法准确地推断出潜在的真实排名和相对的个人专业知识.
- 已成功应用于美国城市人口排名和美国总统时间表.
结论:
- 开发的贝叶斯方法对于聚合多样化的部分排名数据是有效的.
- 这种方法提供了对"群众智慧"现象的洞察力.
- 这种方法对于涉及不完全或部分排名聚合的研究具有广泛的适用性.

相关概念视频
 01:21
Friedman Two-way Analysis of Variance by Ranks
175
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
175
 01:09
Decision Making: P-value Method
5.3K
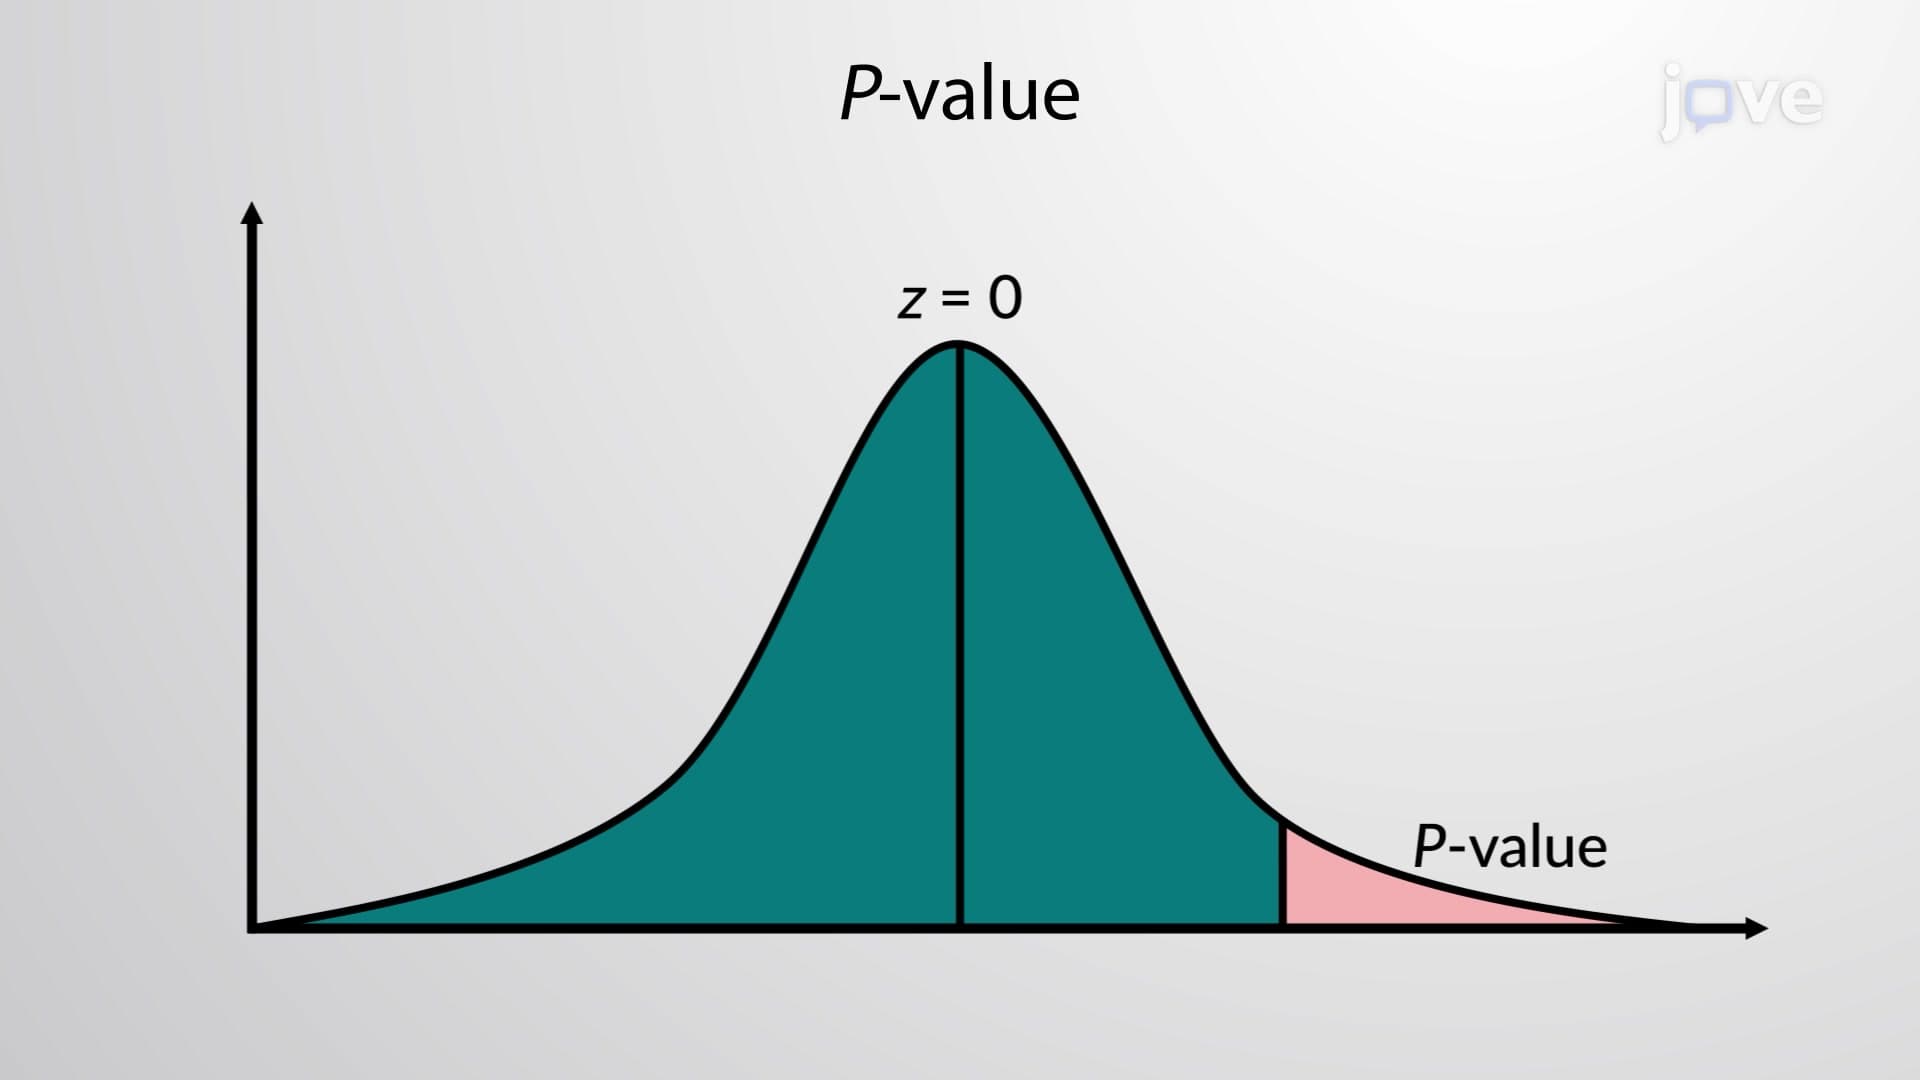
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
5.3K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.5K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.5K
 01:13
Randomized Experiments
6.8K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.8K
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
448
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
448
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K