基于对功率对数分布的排列集采样的估计方法
Najwan Alsadat1, Amal S Hassan2, Mohammed Elgarhy3,4
1Department of Quantitative Analysis, College of Business Administration, King Saud University, P.O. Box 71115, 11587, Riyadh, Saudi Arabia.
Scientific reports
|July 31, 2024

概括
排列集合采样 (RSS) 提高了局限功率对数分布 (PLD) 的统计参数估计准确性. 使用RSS的最大产品间距估计比简单的随机抽样 (SRS) 方法更有效.
科学领域:
- 统计 统计 统计 统计
- 统计建模 统计建模
背景情况:
- 准确的统计参数估计对于数据分析至关重要.
- 排序集采样 (RSS) 提供了一种高效的数据收集方法,特别是在直接量化具有挑战的情况下.
- 有界功率对数分布 (PLD) 是最近的一种分布,适用于有界的真实世界数据.
研究的目的:
- 用排序集采样 (RSS) 估计有限功率对数分布 (PLD) 的三个参数.
- 为了比较RSS下的各种估计方法的效率与它们的简单随机抽样 (SRS) 对应的效率.
主要方法:
- 使用RSS估计PLD参数.
- 调查多种常规估计器:最大概率,最小间距变量,安德森-达林,最小平方,克拉默--米斯和最大间距产物.
- 通过模拟,对RSS估计与SRS估计进行比较分析.
- 验证使用现实世界数据的例子.
主要成果:
- 最大产品间距 (MPS) 估计方法显示了SRS和RSS数据集的卓越性能.
- 使用RSS获得的估计总是比通过SRS获得的更有效.
- 排序集采样 (RSS) 显著提高了PLD参数估计的准确性和效率.
结论:
- 排列集合采样 (RSS) 是一种有价值的技术,可以改进有限功率对数分布 (PLD) 的参数估计.
- 最大产品间距 (MPS) 方法,与RSS相结合,提供最有效的估计.
- 这些发现凸显了RSS估计器在现实应用中的实用实用性.
相关概念视频
 01:26
Distributions to Estimate Population Parameter
4.1K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
4.1K
 01:25
Choosing Between z and t Distribution
2.8K
The z and the Student t distribution estimate the population mean using the sample mean and standard deviation. However, to decide which distribution to use for a calculation, one needs to determine the sample size, the nature of the distribution, and whether the population standard deviation is known. If the population standard deviation is known and the population is normally distributed, or if the sample size is greater than 30, the z distribution is preferred. The Student t distribution is...
2.8K
 01:09
Random Sampling Method
11.0K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. Data are the result of sampling from a population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest. Among the various sampling methods used by...
11.0K
 01:02
Ranks
232
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
232
 01:19
The Mantel-Cox Log-Rank Test
336
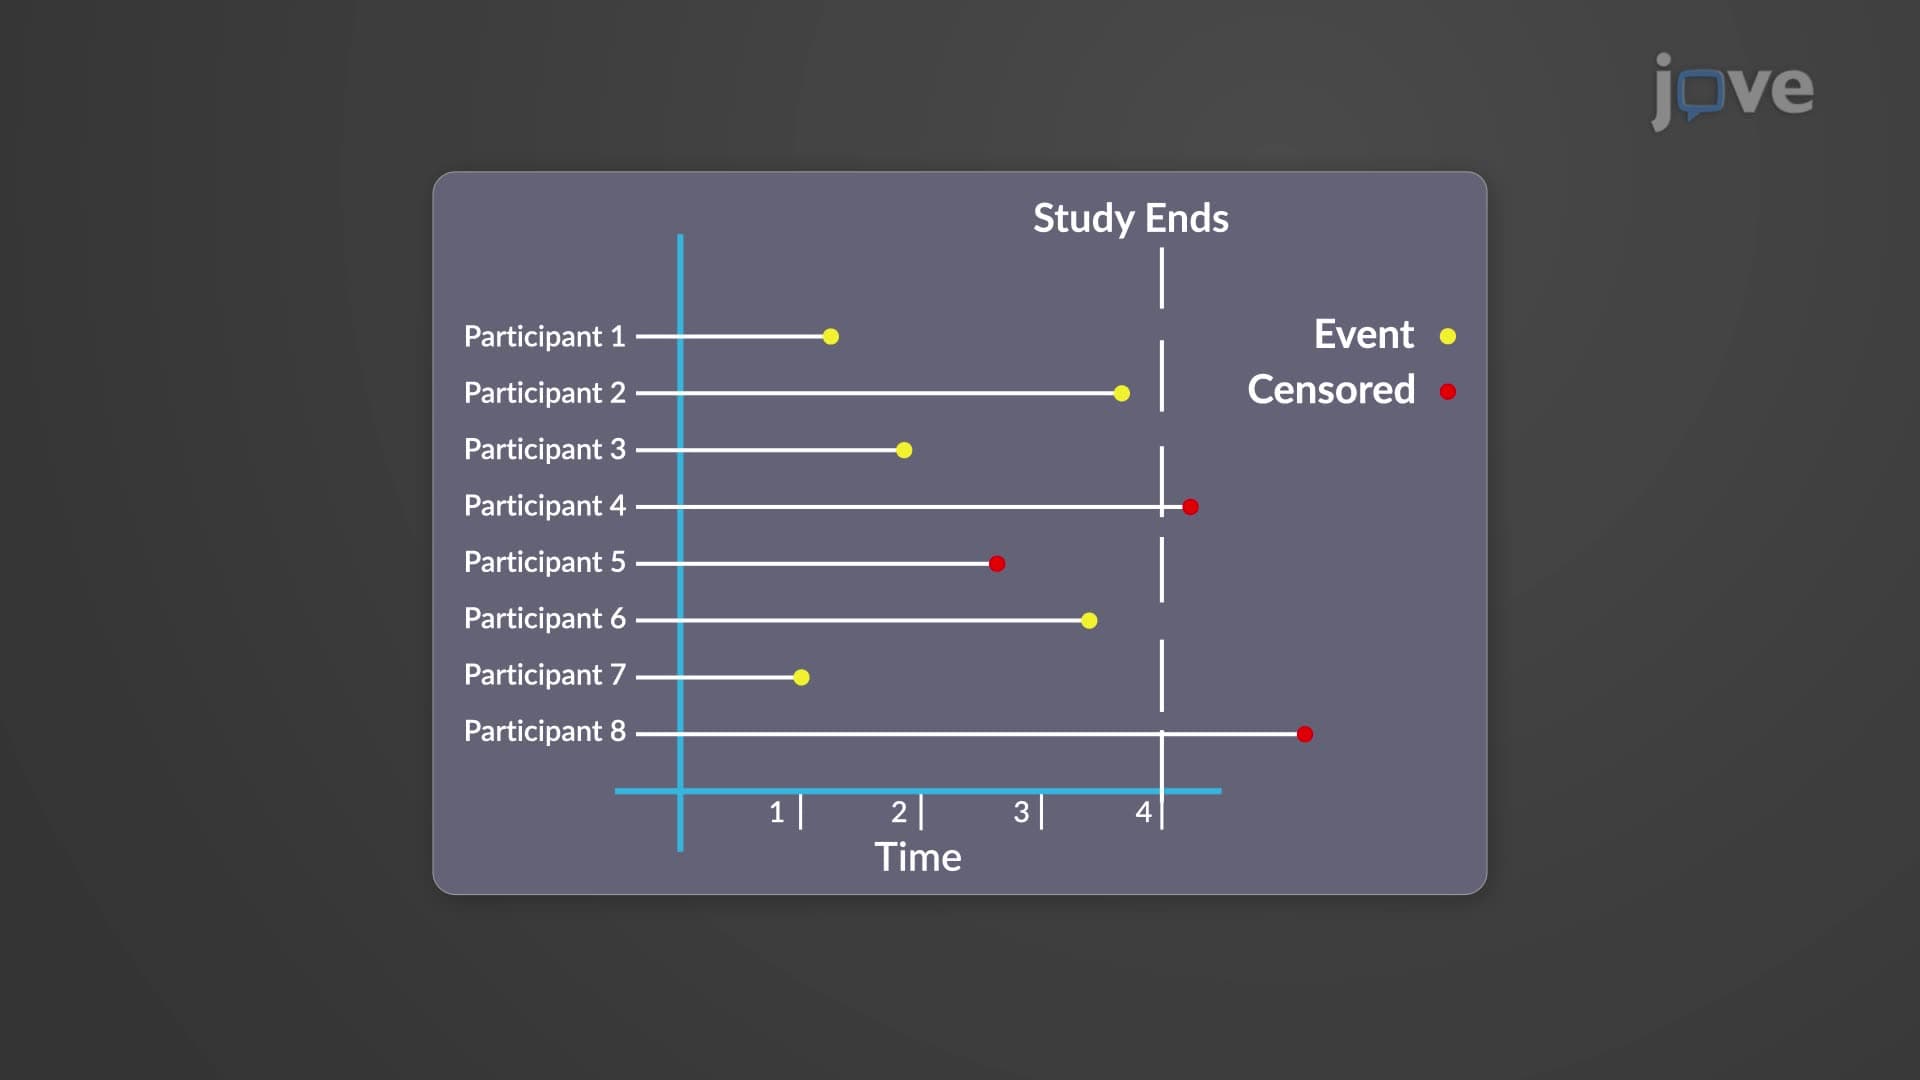
The Mantel-Cox log-rank test is a widely used statistical method for comparing the survival distributions of two groups. It tests whether a statistically significant difference exists in survival times between the groups without assuming a specific distribution for the survival data, making it a non-parametric test. This flexibility makes the log-rank test particularly valuable in medical research and other fields where the timing of an event, such as death or disease recurrence, is of...
336
 01:12
Sampling Distribution
12.3K
Given simple random samples of size n from a given population with a measured characteristic such as mean, proportion, or standard deviation for each sample, the probability distribution of all the measured characteristics is called a sampling distribution. How much the statistic varies from one sample to another is known as the sampling variability of a statistic. You typically measure the sampling variability of a statistic by its standard error. The standard error of the mean is an example...
12.3K