将因果随机森林和线性回归进行比较,以估计组织因素与ICU效率的独立关联
Leonardo S L Bastos1, Safira A Wortel2, Ferishta Bakhshi-Raiez2
1Department of Industrial Engineering, Pontifical Catholic University of Rio de Janeiro (PUC-Rio), Rio de Janeiro, RJ, Brazil.
International journal of medical informatics
|August 7, 2024

概括
因果随机森林 (CRF) 和线性回归建模 (LRM) 都确定了影响ICU效率的因素. CRF强调了具有重大影响的具体单位,帮助改善医疗管理的有针对性的干预措施.
科学领域:
- 关键护理医学 关键护理医学
- 医疗服务研究 医疗服务研究
- 统计建模 统计建模
背景情况:
- 参数回归模型是平均治疗效果的标准.
- 因果机器学习模型对异质治疗效果有希望.
- 进行因果随机森林 (CRF) 和线性回归建模 (LRM) 的比较对于ICU效率分析至关重要.
研究的目的:
- 为了比较CRF和LRM在估计组织因素对ICU效率的影响中的应用.
- 评估两种模型识别影响ICU效率的重要因素的能力.
- 评估CRF在检测特定ICU内的局部影响方面的实用性.
主要方法:
- 在巴西和乌拉圭的128个ICU对277,459名患者进行了三年的回顾性分析.
- 用标准化平均效率比率 (ASER) 衡量ICU效率,包括标准化死亡率 (SMR) 和标准化资源使用率 (SRU).
- 用于估计组织因素的条件平均治疗效应 (CATE) 的因果推断框架,使用LRM与相互作用和CRF.
主要成果:
- 无论是CRF还是LRM,都确定每10张床位的护士平均数量与ICU效率独立相关.
- CRF在特定ICU中发现了显著的CATE,对于LRM没有显著的平均效应的风险.
- 住院死亡率为14%,平均ICU和住院长度分别为2天和7天.
结论:
- CRF和LRM在识别与ICU效率相关的组织因素方面表现出相似的能力.
- CRF的优势在于识别具有重大影响的特定ICU,即使平均影响不显著.
- 结果可以指导医疗保健管理人员进行有针对性的干预,以提高ICU的效率.
相关概念视频
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 00:53
Correlation and Regression
1.2K
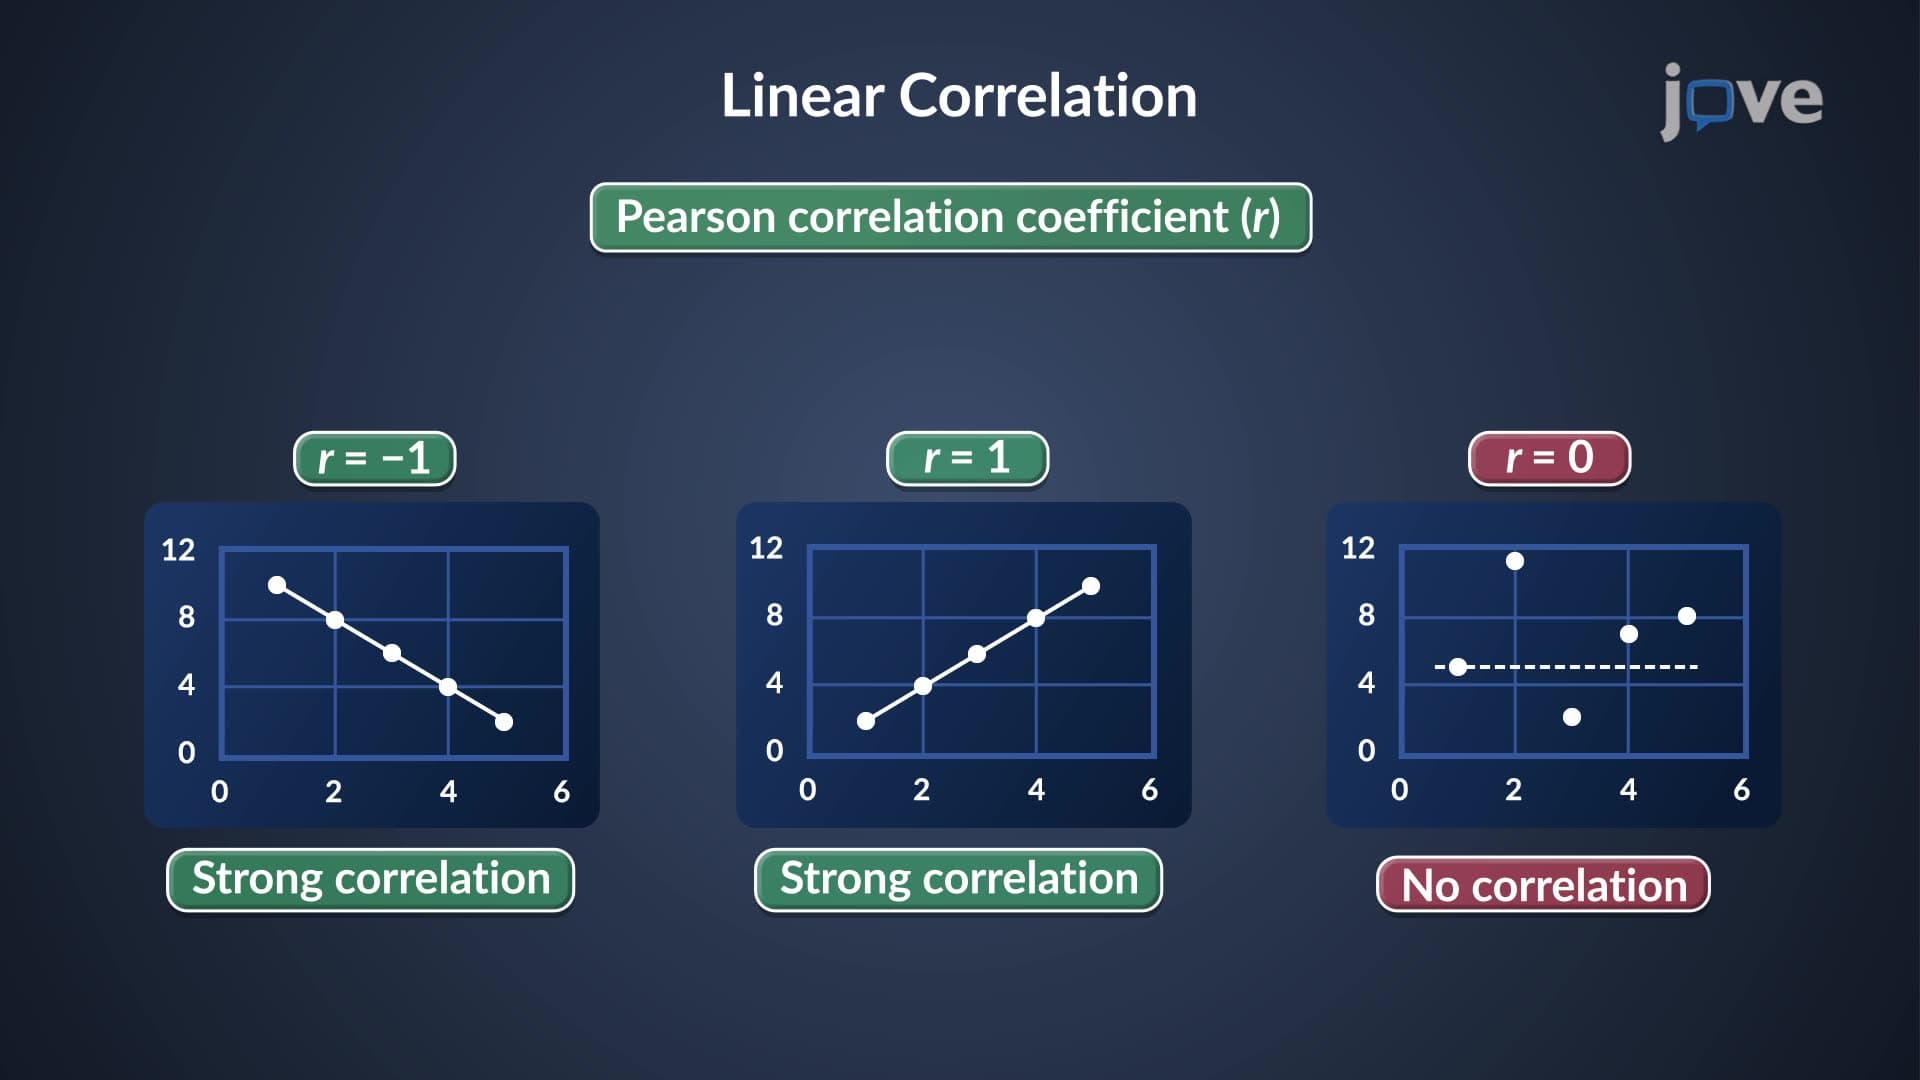
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
1.2K
 02:01
Factorial Design
13.0K
Factorial Analysis is an experimental design that applies Analysis of Variance (ANOVA) statistical procedures to examine a change in a dependent variable due to more than one independent variable, also known as factors. Changes in worker productivity can be reasoned, for example, to be influenced by salary and other conditions, such as skill level. One way to test this hypothesis is by categorizing salary into three levels (low, moderate, and high) and skills sets into two levels (entry level...
13.0K
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
5.9K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable, x, and the dependent variable, y. Hence, it is also known as the Pearson product-moment correlation coefficient. It can be calculated using the following equation:
5.9K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:20
Comparing the Survival Analysis of Two or More Groups
166
Survival analysis is a cornerstone of medical research, used to evaluate the time until an event of interest occurs, such as death, disease recurrence, or recovery. Unlike standard statistical methods, survival analysis is particularly adept at handling censored data—instances where the event has not occurred for some participants by the end of the study or remains unobserved. To address these unique challenges, specialized techniques like the Kaplan-Meier estimator, log-rank test, and...
166