
解读印度儿童营养不良难题:使用复合指数的多变量分析
Gulzar Shah1, Maryam Siddiqa2, Padmini Shankar3
1Department of Health Policy and Community Health, Jiann-Ping Hsu College of Public Health, Georgia Southern University, Statesboro, GA 30460, USA.
Children (Basel, Switzerland)
|August 29, 2024

概括
在印度,儿童营养不良影响了五岁以下儿童的一半以上. 诸如出生顺序,母亲健康和社会经济地位等因素显著预测营养结果,需要全面的公共卫生干预.
科学领域:
- 公共卫生 公共卫生
- 儿科 儿科 儿科
- 营养流行病学 营养流行病学
背景情况:
- 儿童营养不良是印度持续存在的公共卫生挑战.
- 了解营养不良的决定因素对于有效的干预策略至关重要.
研究的目的:
- 调查印度五岁以下儿童营养不良的流行情况并确定营养不良的预测因素.
- 为旨在改善儿童营养的公共卫生政策和干预措施提供信息.
主要方法:
- 利用来自印度国家家庭健康调查 (2019-2021) 的数据.
- 应用了人类学失败综合指数来评估营养不良.
- 采用多变量逻辑回归来识别重要的预测因素.
主要成果:
- 超过52%的儿童经历了人体测量失败.
- 女性性别,更大的出生体型,更高的母亲教育和更好的社会经济地位与较低的营养不良风险有关.
- 出生顺序较高,严重的母体贫血和特定的宗教信仰与营养不良风险增加有关.
结论:
- 儿童营养不良仍然是印度的一个关键问题,需要公共和私营部门的综合努力.
- 建议采用"所有政策中的健康"方法来解决影响儿童营养状况的因素.
相关概念视频
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:25
Statistical Methods for Analyzing Epidemiological Data
330
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
330
 01:21
Friedman Two-way Analysis of Variance by Ranks
168
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
168
 01:18
One-Way ANOVA
7.9K
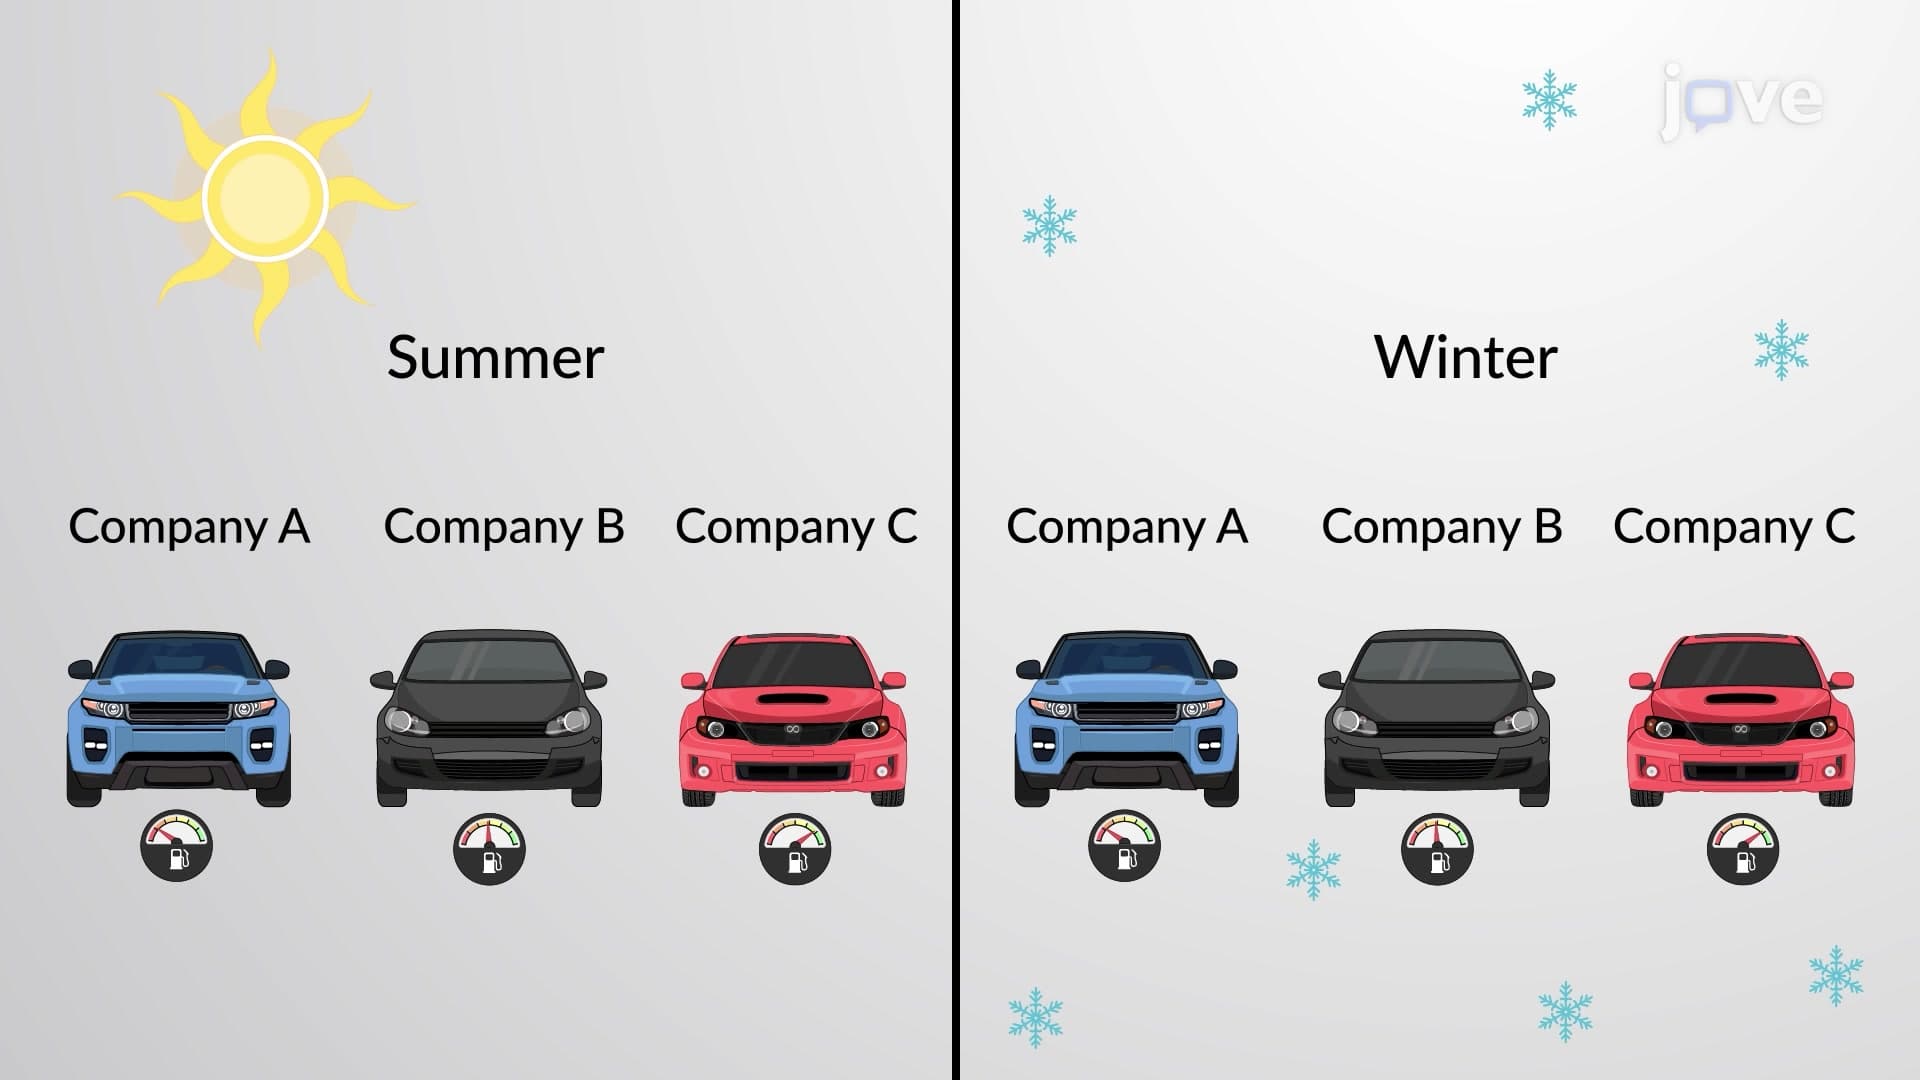
One-way ANOVA analyzes more than three samples categorized by one factor. For example, it can compare the average mileage of sports bikes. Here, the data is categorized by one factor - the company. However, one-way ANOVA cannot be used to simultaneously compare the sample mean of three or more samples categorized by two factors. An example of two factors would be sports bikes from different companies driven in different terrains, such as a desert or snowy landscape. Here, two-way ANOVA is used...
7.9K
 01:29
Bias in Epidemiological Studies
180
Biases can arise at various stages of research, from study design and data collection to analysis and interpretation. Recognizing and addressing these biases is essential to ensure the validity and reliability of epidemiological findings.Broadly speaking, biases in epidemiology fall into three main categories: selection bias, information bias, and confounding. A more detailed description of possible biases is:
180