

调整回归可以在面对多对线性和有限数据的情况下改善多变量选择的估计
Jacqueline L Sztepanacz1, David Houle2
1Department of Ecology and Evolutionary Biology, University of Toronto, Toronto, ON, Canada.
Evolution letters
|August 30, 2024

概括
调节回归通过解决多对线性来改善进化选择的估计. 这种方法为选择提供了更准确的洞察力.
科学领域:
- 进化生物学是进化的生物学.
- 定量遗传学 是一种定量遗传学.
- 统计建模 统计建模
背景情况:
- 育种方程式模型使用遗传 (G) 和选择 (β) 组件来演化变化.
- 特征数据的多线性使得选择梯度 (β) 的准确估计变得复杂.
- 大数据场景加剧了多对线性问题,挑战了传统的回归方法.
研究的目的:
- 调查多对线性对选择梯度估计的影响.
- 评价调整回归作为一个解决方案,用于准确的多变量选择估计.
- 为了比较规范化和传统的回归方法在分析选择压力.
主要方法:
- 使用模拟来建模多对线性对选择估计的影响.
- 调整回归技术被应用来解决多对线性.
- 发表的案例研究被重新分析,使用标准和规范化回归.
主要成果:
- 多对线性导致不准确的选择估计和偏见的解释,当相关的特征被删除.
- 调整回归可以更准确地估计多变量选择的强度和方向,尤其是在有限的数据的情况下.
- 在重新分析的案例研究中,规范化回归改善了健身预测.
结论:
- 规则化回归是一种有价值的补充,用于估计选择的传统最小平方方法.
- 这种方法增强了对个体健康和进化选择的总体方向的预测.
- 调整回归为在多对线性存在的情况下分析选择提供了一个强大的解决方案.

相关概念视频
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
432
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
432
 00:53
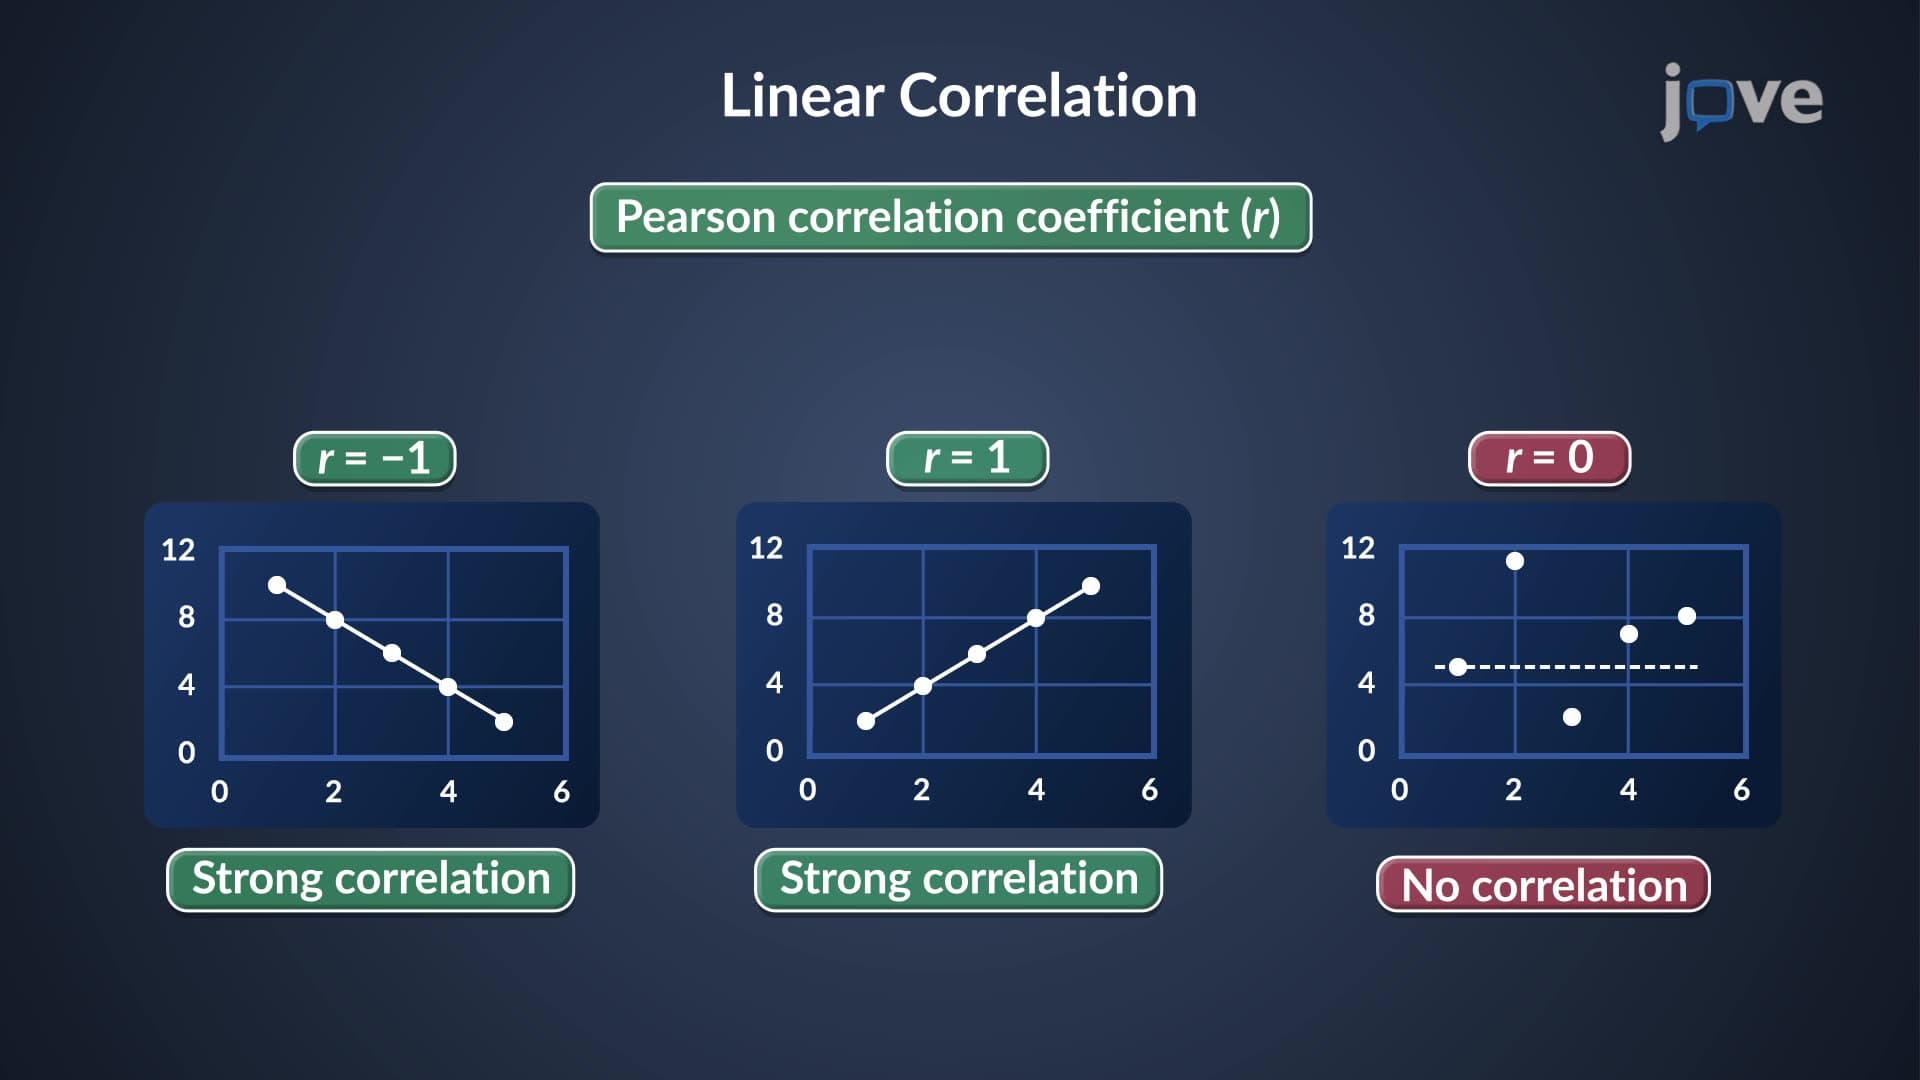
Correlation and Regression
1.2K
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
1.2K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K