变量标签增强用于依赖实例的部分标签学习

IEEE transactions on pattern analysis and machine intelligence
|September 6, 2024

概括
本研究引入了部分标签学习 (PLL) 的新方法,解决了依赖实例的标签噪声. 拟议的VALEN和MILEN模型通过增强隐藏标签分布,有效地提高了预测准确性.
科学领域:
- 机器学习 机器学习
- 人工智能的人工智能
- 计算机科学 计算机科学
背景情况:
- 部分标签学习 (PLL) 是一种弱监督的学习,每个实例都有一组候选标签,只有一个是正确的.
- 现有的PLL方法通常假定错误标签的随机选择,这是不现实的,因为标签可以依赖实例.
- 在现实世界的机器学习应用中,依赖实例的标签噪声构成了重大挑战.
研究的目的:
- 为了解决依赖实例的部分标签学习问题.
- 提出新的方法,以考虑PLL中的候选标签的实例依赖性.
- 在具有非随机标签噪声的场景中提高预测模型的准确性.
主要方法:
- 提出了两种方法:VALEN和MILEN,旨在处理依赖实例的PLL.
- 这两种方法都使用了通过标签增强过程恢复的潜在标签分布.
- VALEN使用推理模型和证据下界推断变化后密度;MILEN使用变化近似来绑定相互信息.
主要成果:
- 拟议的VALEN和MILEN方法在处理依赖实例的部分标签学习方面表现出有效性.
- 对基准和现实数据集的实验验证实了拟议方法的卓越性能.
- 这些方法成功地恢复了隐藏的标签分布,从而改善了模型训练.
结论:
- 开发的方法VALEN和MILEN为具有挑战性的依赖实例的部分标签学习问题提供了有效的解决方案.
- 对依赖实例的标签分发进行核算对于提高PLL性能至关重要.
- 建议的标签增强技术为缺乏监督的学习提供了一个强大的框架,具有复杂的噪音模式.

相关概念视频
 01:27
Associative Learning
317
Associative learning is a fundamental concept in behavioral psychology, wherein a connection is established between two stimuli or events, leading to a learned response. This process is critical in understanding how behaviors are acquired and modified. Conditioning, the mechanism through which associations are formed, can be divided into two main types: classical conditioning and operant conditioning, each elucidating different aspects of associative learning.
Classical conditioning, also known...
Classical conditioning, also known...
317
 01:24
Generalization, Discrimination, and Extinction
490
Generalization, discrimination, and extinction are key concepts in operant conditioning that influence how behaviors are learned and maintained.
Generalization occurs when a behavior reinforced in one context is performed in similar situations. For instance, a student who studies diligently for calculus and receives excellent grades might apply the same study habits to psychology and history, expecting similar results. Generalization shows how learning in one setting can influence behavior in...
Generalization occurs when a behavior reinforced in one context is performed in similar situations. For instance, a student who studies diligently for calculus and receives excellent grades might apply the same study habits to psychology and history, expecting similar results. Generalization shows how learning in one setting can influence behavior in...
490
 01:26
Per-Unit Sequence Models
73
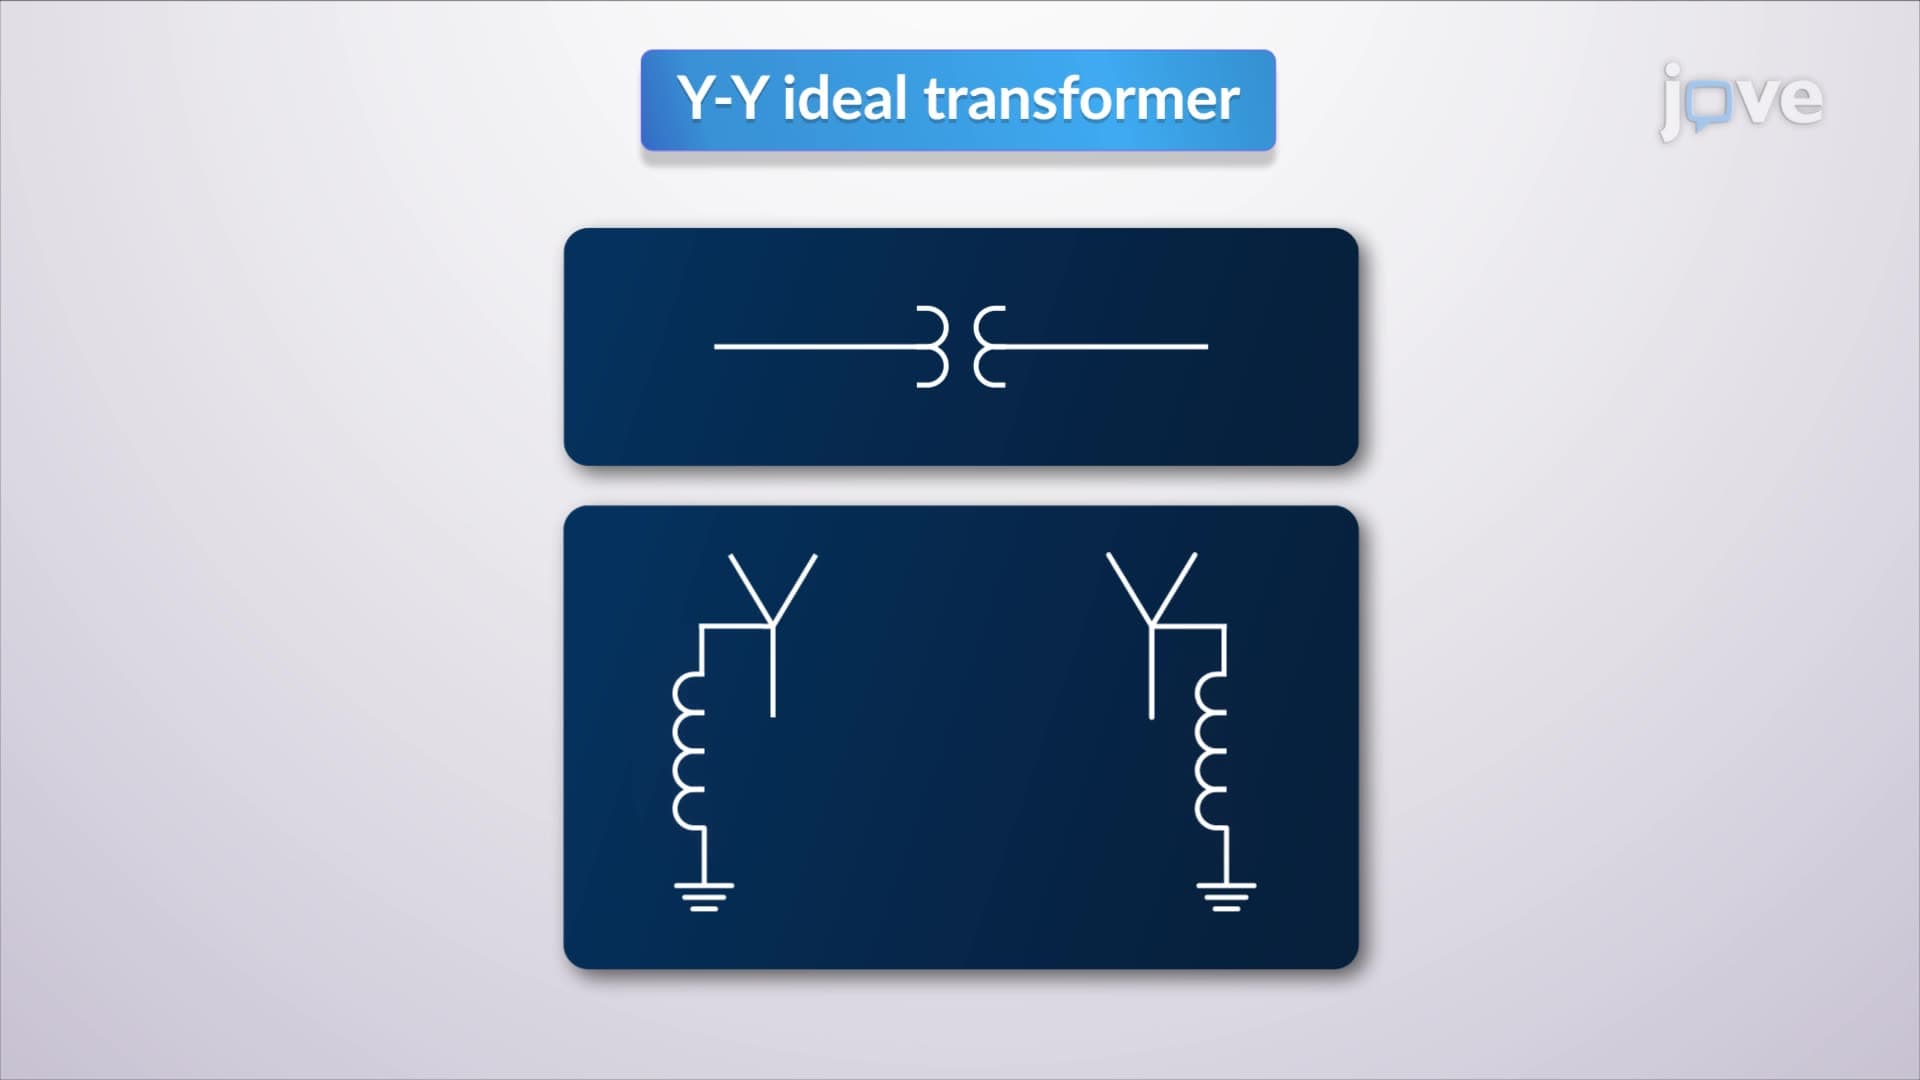
An ideal Y-Y transformer, grounded through neutral impedances, displays per-unit sequence networks akin to those of a single-phase ideal transformer when subjected to balanced positive- or negative-sequence currents. These currents do not produce neutral currents, and their associated voltage drops.
Zero-sequence currents, which are identical in magnitude and phase, generate a neutral current, resulting in voltage drops across the neutral impedance and the low-voltage winding. If the...
Zero-sequence currents, which are identical in magnitude and phase, generate a neutral current, resulting in voltage drops across the neutral impedance and the low-voltage winding. If the...
73
 01:31
Classification of Systems-II
137
Continuous-time systems have continuous input and output signals, with time measured continuously. These systems are generally defined by differential or algebraic equations. For instance, in an RC circuit, the relationship between input and output voltage is expressed through a differential equation derived from Ohm's law and the capacitor relation,
137
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
432
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
432
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K