
在集群集群聚合中精确计算罕见事件的概率
R Rajesh1,2, V Subashri1,2, Oleg Zaboronski3
1<a href="https://ror.org/05078rg59">The Institute of Mathematical Sciences</a>, C.I.T. Campus, Taramani, Chennai 600113, India.
Physical review letters
|September 13, 2024

概括
我们开发了一种新方法来计算集群集群聚合中的罕见事件概率. 这种动作形式主义精确地确定了各种碰撞内核的速率函数和最佳轨迹,匹配模拟结果.
科学领域:
- 统计物理 统计物理
- 化学物理 化学物理
- 计算物理 计算物理
背景情况:
- 集群集群聚合是材料科学和物理学的基本过程.
- 在这样的系统中计算罕见事件的概率在计算上具有挑战性.
- 现有的方法往往缺乏对任意碰撞内核的精度.
研究的目的:
- 开发一种新的动作形式主义,用于计算群集群集聚中的罕见事件概率.
- 为量化这些罕见事件建立一个路径大偏差原理.
- 将形式主义应用于特定的碰撞内核 (常数,和,乘积),并分析速率函数和最佳轨迹.
主要方法:
- 基于大偏差理论的行动形式主义的发展.
- 建立一个路径大偏差原理,其中总质量代表了速率.
- 准确计算速率函数和恒定,和和产品核的最佳演变轨迹.
主要成果:
- 动作形式主义成功计算了任意碰撞内核的罕见事件概率.
- 准确的速度函数和最佳轨迹的解决方案得到了常数,和和和产品的核心.
- 在产品内核中发现了率函数的第二导数中的不连续性.
- 理论预测与专门的模拟对齐,用于罕见事件计算.
结论:
- 开发的动作形式主义提供了一个强大而准确的工具,用于分析集群集群聚合中的罕见事件.
- 这些发现为系统动态提供了精确的见解,特别是对于产品内核的速率函数.
- 与模拟的协议验证了对罕见事件概率计算的理论方法.

相关概念视频
 01:17
Probability Histograms
11.1K
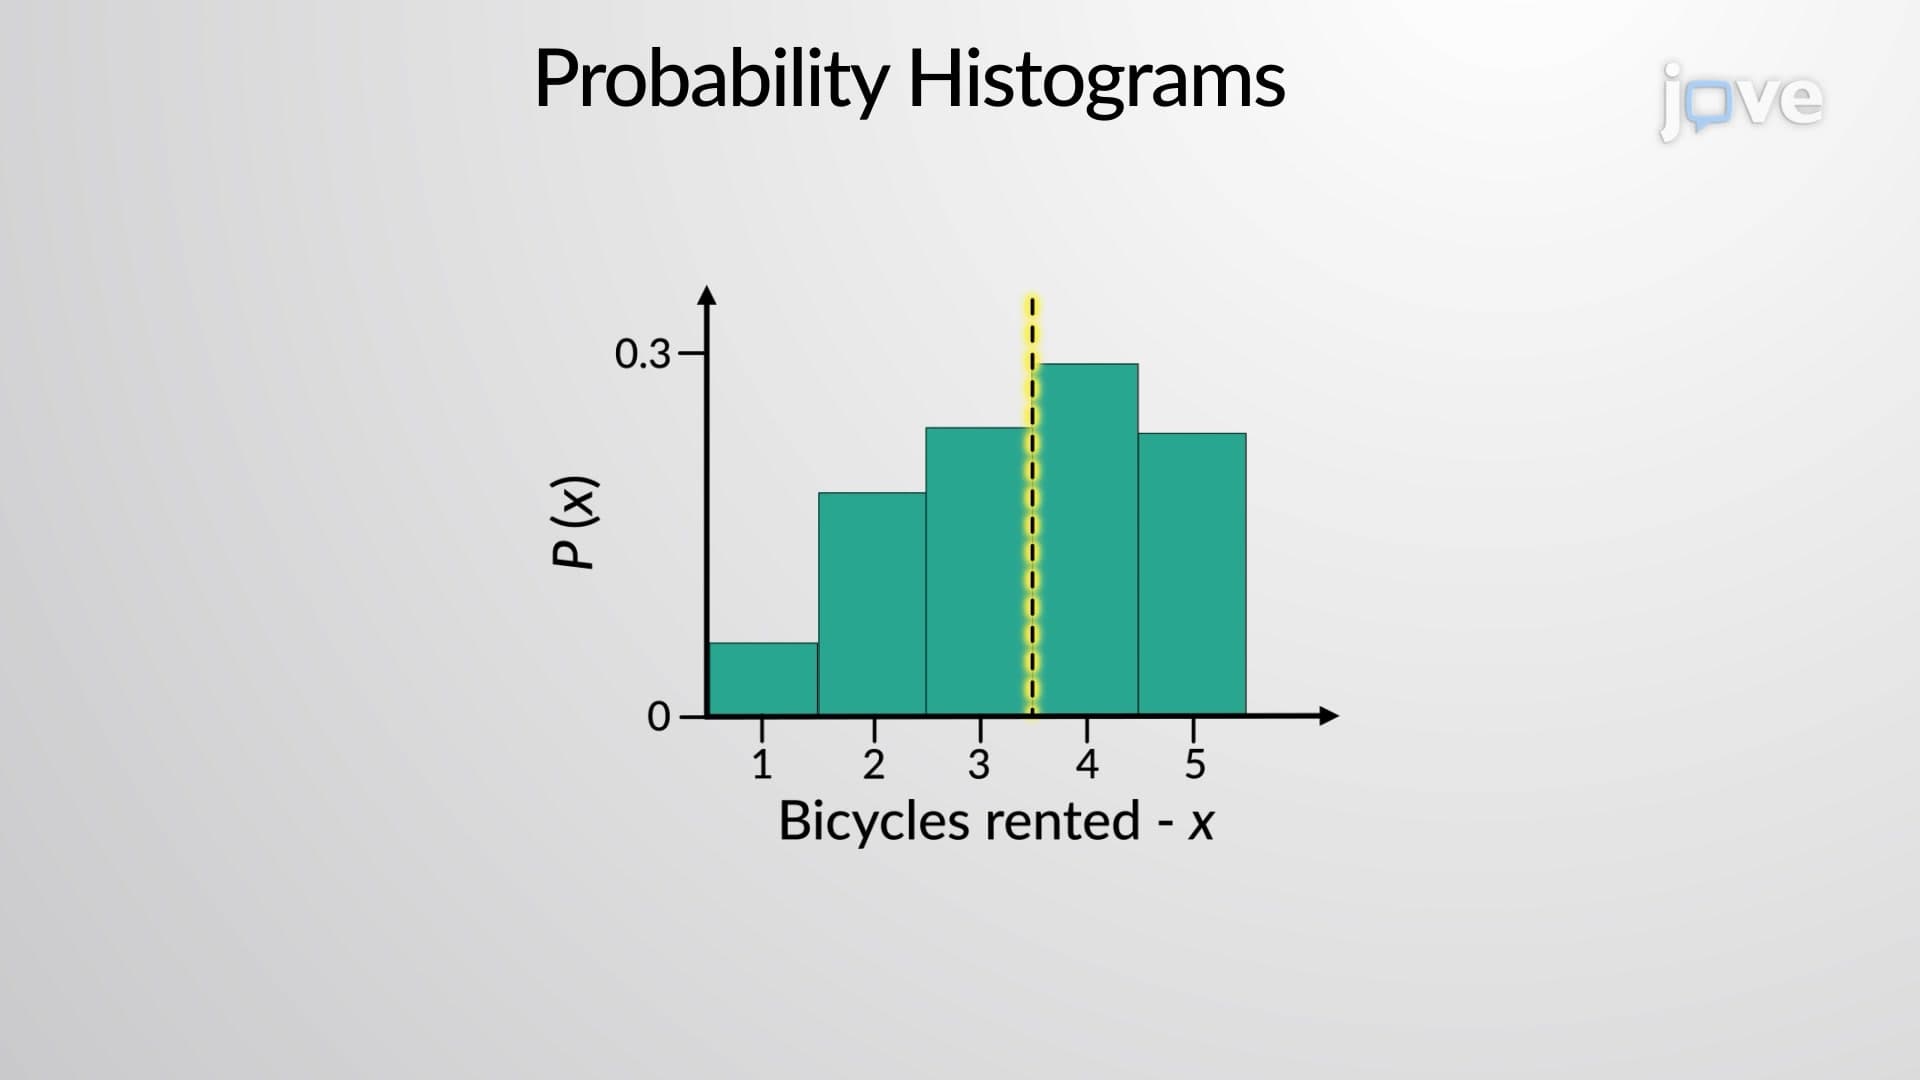
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
11.1K
 01:20
Cluster Sampling Method
11.8K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
11.8K
 01:15
Binomial Probability Distribution
10.3K
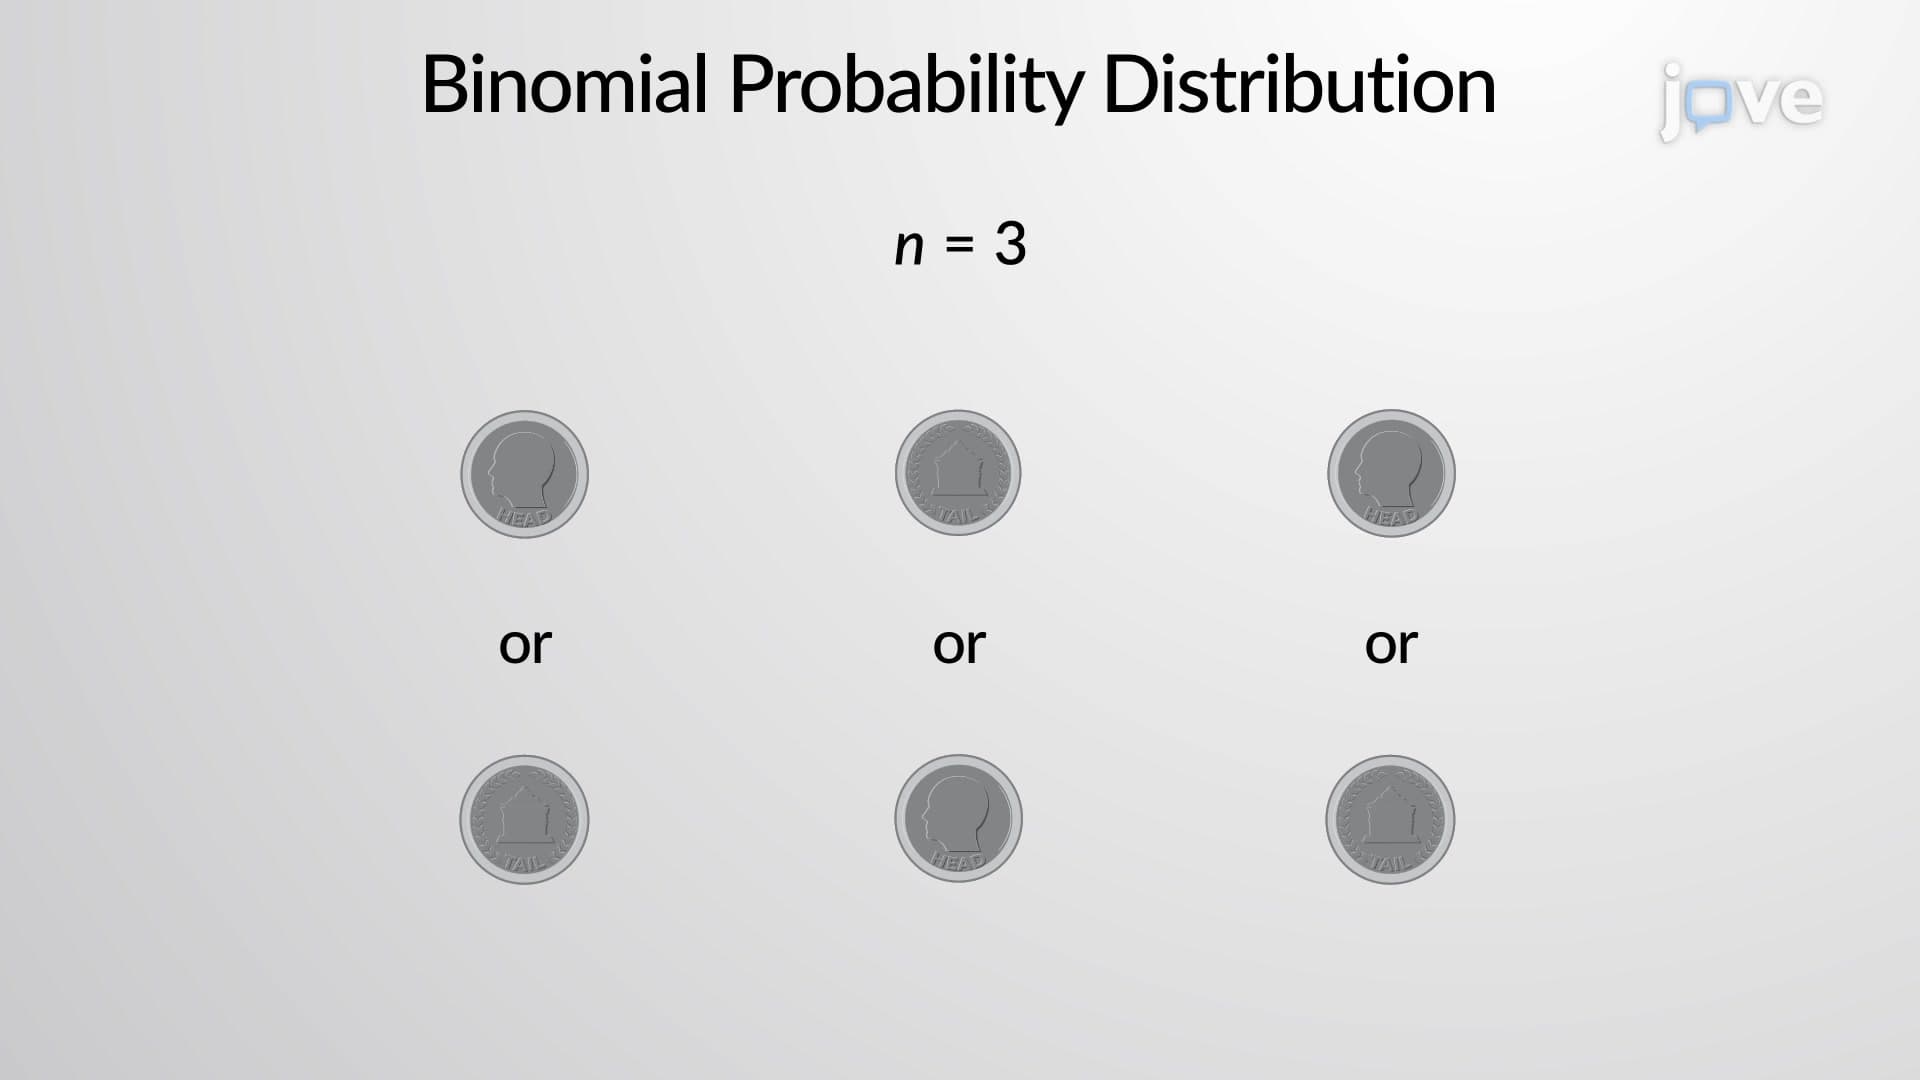
A binomial distribution is a probability distribution for a procedure with a fixed number of trials, where each trial can have only two outcomes.
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
10.3K
 01:14
Probability in Statistics
12.4K
Probability is the likelihood of an event occurring. The term event is defined as a collection of results of a procedure. An event is a simple event when an outcome cannot be divided into simpler parts.
An example of a simple event is a coin toss. The result of a coin toss is either a head or a tail. Here, head and tail are two simple events. These two simple events make up the sample space. Further, the probability of an event occurring falls within the range of 0 to 1. The probability of an...
An example of a simple event is a coin toss. The result of a coin toss is either a head or a tail. Here, head and tail are two simple events. These two simple events make up the sample space. Further, the probability of an event occurring falls within the range of 0 to 1. The probability of an...
12.4K
 01:08
Determination of Expected Frequency
2.2K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.2K
 01:17
z Scores and Area Under the Curve
10.4K
z scores are the standardized values obtained after converting a normal distribution into a standard normal distribution. A z score is measured in units of the standard deviation. The z score tells you how many standard deviations the value x is above (to the right of) or below (to the left of) the mean, μ. Values of x that are larger than the mean have positive z scores, and values of x that are smaller than the mean have negative z scores. If x equals the mean, then x has a z score of...
10.4K