

一个预测模型,用于对全球网络中假新闻和假冒新闻分类算法的性能进行基准测试
Nureni Ayofe Azeez1, Sanjay Misra2, Davidson Onyinye Ogaraku1
1Department of Computer Sciences, University of Lagos, Lagos 100213, Nigeria.
Sensors (Basel, Switzerland)
|September 14, 2024

概括
这项研究使用监督的AI算法来对社交媒体上的假新闻进行分类. 机器学习模型准确地识别虚假信息,提高在线内容的完整性.
科学领域:
- 计算机科学 计算机科学
- 信息科学 信息科学 信息科学
背景情况:
- 社交媒体上假新闻的蔓延对社会信任和民主制度构成重大威胁.
- 有效地检测错误信息对于保持信息完整性至关重要.
研究的目的:
- 调查监督人工智能算法对分类假新闻的有效性.
- 确定最佳的机器学习模型,用于在各种数据集中检测假新闻.
主要方法:
- 利用监督的人工智能算法,包括被动侵略分类器,感知器和决策.
- 在各种社交媒体数据集上训练了29个模型,使用TF-IDF和Count Vectorizers来生成特征.
- 采用传感器进行数据收集和严格的数据预处理技术.
主要成果:
- 使用准确性,精度和回忆指标评估模型性能.
- 在每个数据集中确定了表现最好的算法:SG (数据集1),BernoulliRBM (数据集2),线性SVC (数据集3) 和BernoulliRBM (数据集4).
- 展示了人工智能在区分真实的新闻和伪造的内容方面的潜力.
结论:
- 监督的人工智能算法为打击假新闻和维护信息完整性提供了可行的解决方案.
- 这些发现对学术界和实际应用在维护民主话语方面有重大影响.
- 强调传感器和大数据分析在物联网和智能城市环境中的信息完整性中的作用.


相关概念视频
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:29
Aggregates Classification
306
Aggregate classification is generally based on its size, petrographic characteristics, weight, and source. Size classification ranges from coarse to fine aggregates, defined by the size of the particles. Coarse aggregates are particles that do not pass through ASTM sieve No. 4, and aggregates that pass through the sieve are fine aggregates.
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
306
 01:30
Classification of Signals
420
In signal processing, signals are classified based on various characteristics: continuous-time versus discrete-time, periodic versus aperiodic, analog versus digital, and causal versus noncausal. Each category highlights distinct properties crucial for understanding and manipulating signals.
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
420
 02:07
Improving Translational Accuracy
9.4K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
9.4K
 01:52
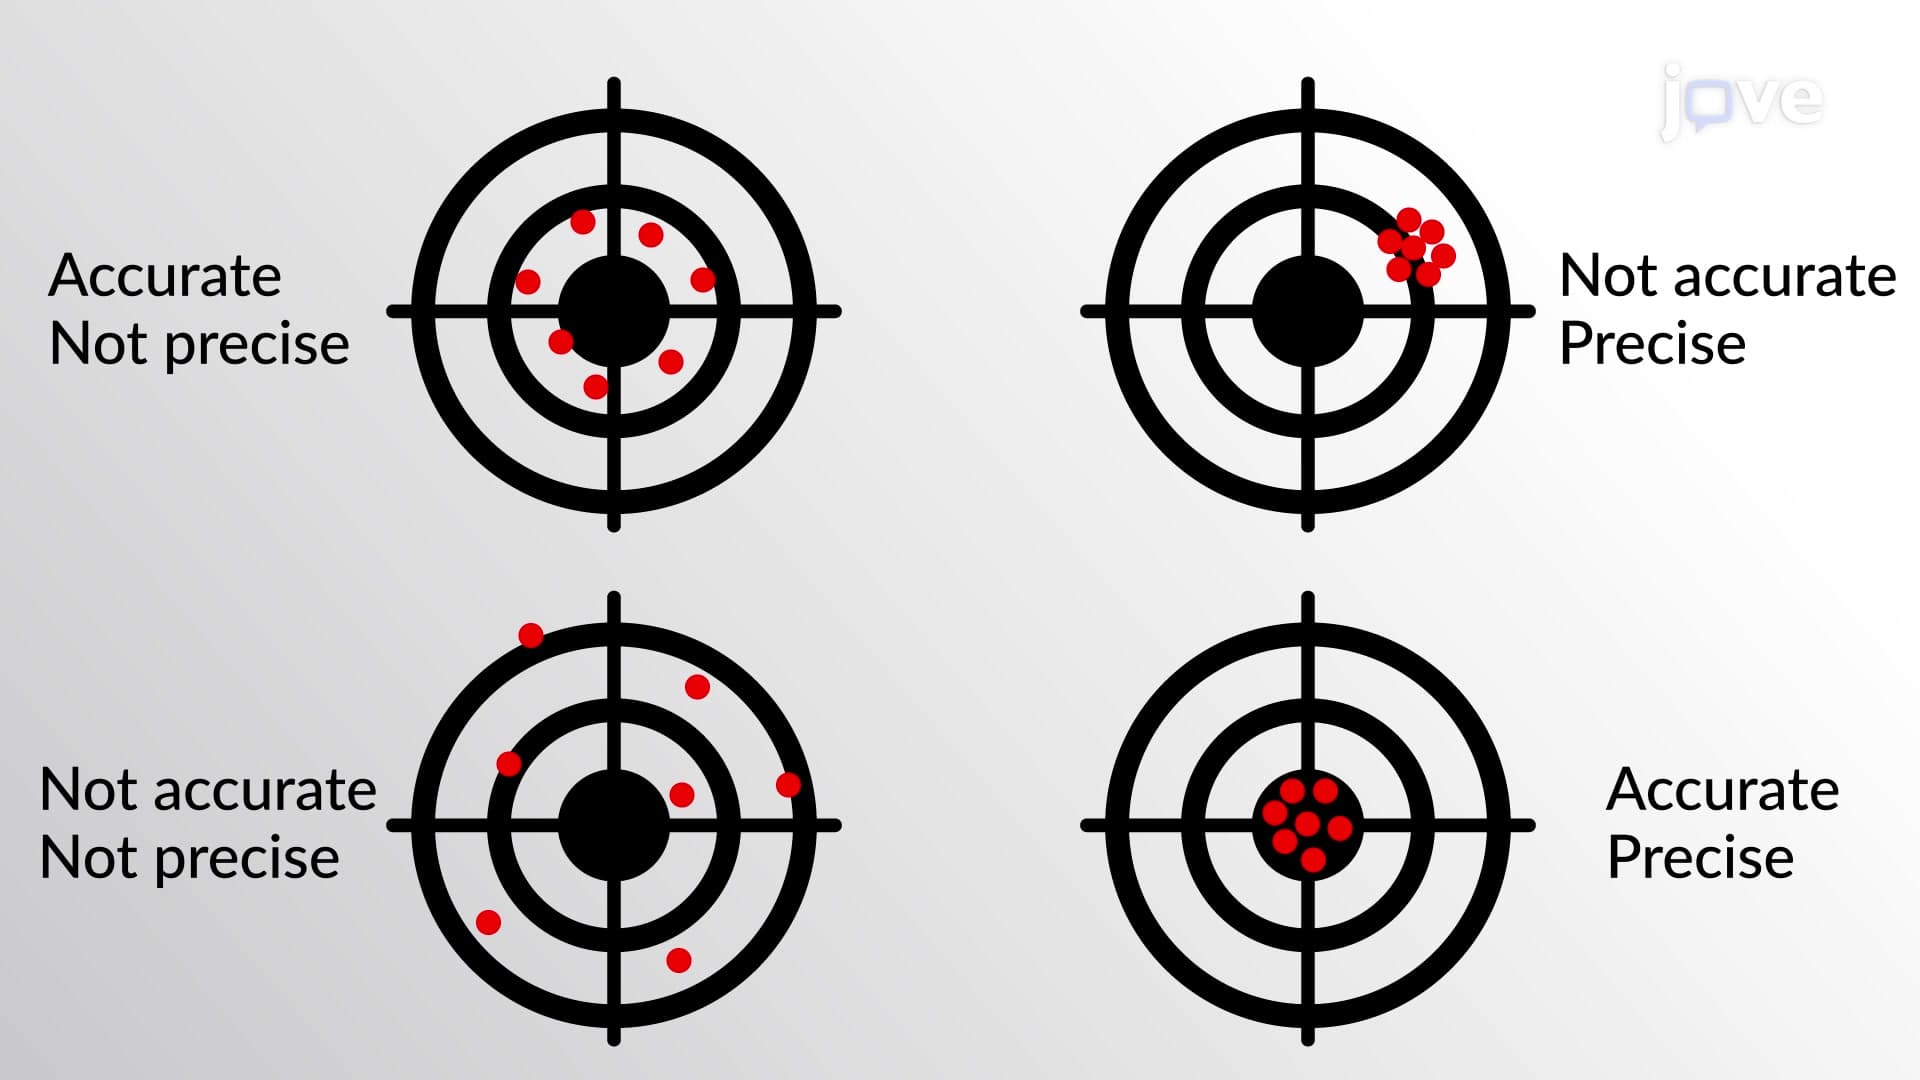
Accuracy and Precision
8.8K
Scientists typically make repeated measurements of a quantity to ensure the quality of their findings and to evaluate both the precision and the accuracy of their results. Measurements are said to be precise if they yield very similar results when repeated in the same manner. A measurement is considered accurate if it yields a result that is very close to the true or the accepted value. Precise values agree with each other; accurate values agree with a true value. Highly accurate...
8.8K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.5K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.5K