
使用非线性自回归分布式滞后和机器学习算法预测和揭示孟加拉国总出口的受阻因素
Tanzin Akhter1, Tamanna Siddiqua Ratna1, Ferdous Ahmed2
1Department of Quantitative Sciences, International University of Business Agriculture and Technology, (IUBAT), 4 Embankment Drive Road, Sector -10, Uttara, Dhaka, Bangladesh.
Heliyon
|September 16, 2024

概括
油价上成为孟加拉国面临的挑战.
科学领域:
- 经济学 经济学 经济学
- 计量经济学 计量经济学
- 能源经济学 能源经济学
背景情况:
- 孟加拉国等新兴经济体面临着全球油价上带来的重大挑战.
- 之前关于石油价格冲击影响的研究主要集中在发达国家,忽视了新兴经济体.
- 孟加拉国不断增加的石油消费增加了其对价格波动的脆弱性.
研究的目的:
- 调查油价波动对孟加拉国出口总收入的影响.
- 在不同的石油价格情景下预测孟加拉国总体出口量.
- 分析油价变化对出口业绩的不对称影响.
主要方法:
- 非线性自回归分布式滞后 (NARDL) 模型应用于1991-2021年的数据.
- 对称性测试用于评估出口量与石油价格之间的非线性关系.
- 先知和长短期记忆 (LSTM) 模型用于预测出口量和评估预测准确性.
主要成果:
- 长期分析表明,正面和负面的石油价格冲击都会增加出口收入.
- 短期分析显示,油价变化对出口产生了显著的负面影响.
- 短期内,通货膨胀会对出口收入产生负面影响,但从长远来看会产生积极影响.
- LSTM模型在先知模型上表现出优越的预测性能,其低RMSE为1.88.
结论:
- 该研究强调了孟加拉国出口部门多元化的必要性,以减轻与油价波动相关的风险.
- 政策干预应考虑石油价格和通货膨胀对出口收入的不对称和时间变化的影响.
- 使用像LSTM这样的先进机器学习技术进行准确的预测对于脆弱国家的经济规划至关重要.

相关概念视频
 01:18
Steps in Outbreak Investigation
114
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
114
 01:18
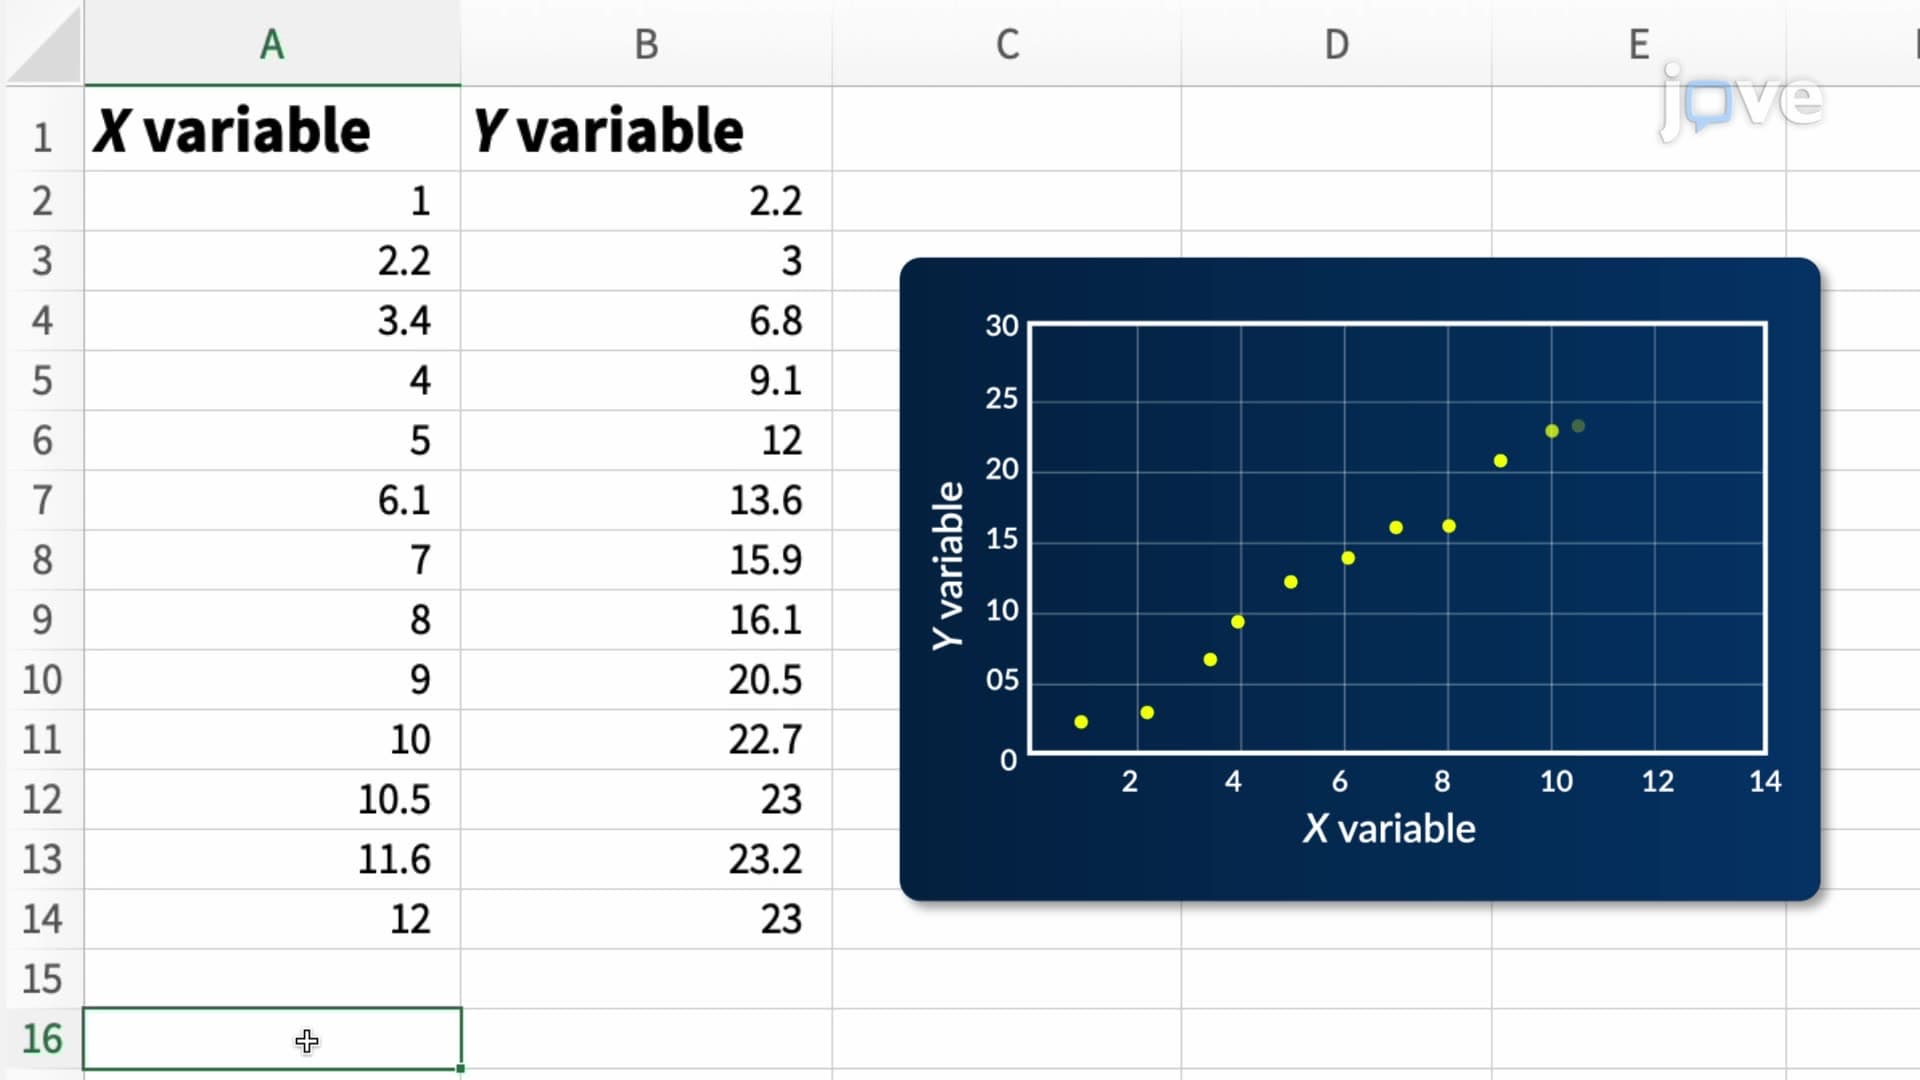
Microsoft Excel: Regression Analysis
531
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
531
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:07
Residual Plots
4.6K
A residual plot is a statistical representation of data used to analyze correlation and regression results. It helps verify the requirements for drawing specific conclusions about correlation and regression. To obtain the residual plot, first, the residual for each data value is calculated, which is simply the vertical distance between the observed and the predicted value obtained from the regression equation.
When the residual values are plotted against the variable x, it is called a residual...
When the residual values are plotted against the variable x, it is called a residual...
4.6K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K