相关实验视频
Updated: Jun 12, 2025
09:05

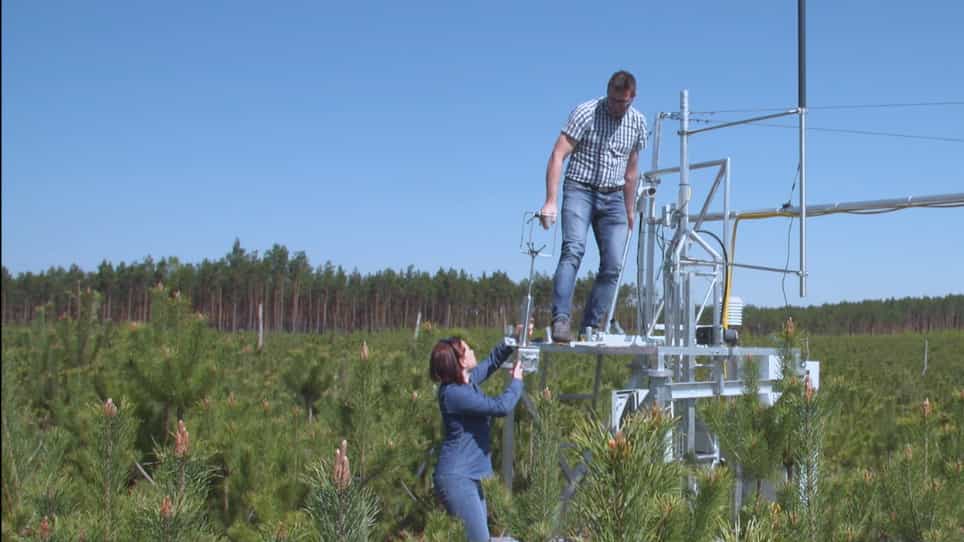
Measurements of CO2 Fluxes at Non-Ideal Eddy Covariance Sites
Published on: June 24, 2019
7.9K
一个新的基于集体的深度模型,具有异常值去除和顺序不变排名,用于二氧化碳排放预测
1Institute of Industrial Economics, Chinese Academy of Social Science, Beijing, 100006, PR China. yanhuan56@126.com.
Environmental science and pollution research international
|September 17, 2024

概括
准确的二氧化碳 (CO2) 排放预测对于气候政策至关重要. 本研究引入了使用长短期记忆 (LSTM) 网络的深度合并模型,提高了预测准确性和稳定性,以进行知情决策.
科学领域:
- 环境科学 环境科学
- 气候变化研究 气候变化研究
- 数据科学数据科学数据科学
背景情况:
- 增加的二氧化碳 (CO2) 排放是一个重大的全球挑战,影响气候变化和经济发展.
- 可靠的二氧化碳排放预测对于政策制定者来说至关重要,以实施有效的减排战略,并与经济增长平衡环境目标.
研究的目的:
- 为预测二氧化碳排放开发和评估一种创新的深度整体预测模型.
- 为决策提高二氧化碳排放预测的准确性,稳定性和可靠性.
主要方法:
- 一个集成四个并行的长短期记忆 (LSTM) 神经网络的深层集合模型.
- 一个基于多层感知 (MLP) 的集体框架,包含k-最近邻居 (KNN) 异常值检测和顺序不变排名模块.
- 模型验证使用6个代表国家的1971-2021年历史二氧化碳排放数据.
主要成果:
- 拟议的深层组合模型在多个评估指标上显示出与现有方法相比的优异性能.
- 该模型大大减少了预测差异,并提高了CO2排放预测的稳定性.
- 对六个国家产生了长期二氧化碳排放预测,为政策制定提供了有价值的见解.
结论:
- 新型深层组合模型为准确的二氧化碳排放预测提供了强大而稳定的方法.
- 这些发现支持使用先进的机器学习技术来制定减缓气候变化政策.
- 产生的长期预测可以帮助决策者做出有关碳减排战略的明智决策.
相关概念视频
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.5K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.5K
 01:08
Outliers and Influential Points
4.0K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.0K
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:12
What Are Outliers?
3.7K
Outliers are observed data points that are far from the least squares line. They have unusual values and need to be examined carefully. Though an outlier may result from erroneous data, at other times, it may hold valuable information about the population under study and should be included in the data. Hence, it is crucial to examine what causes a data point to be an outlier.
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
3.7K
 01:07
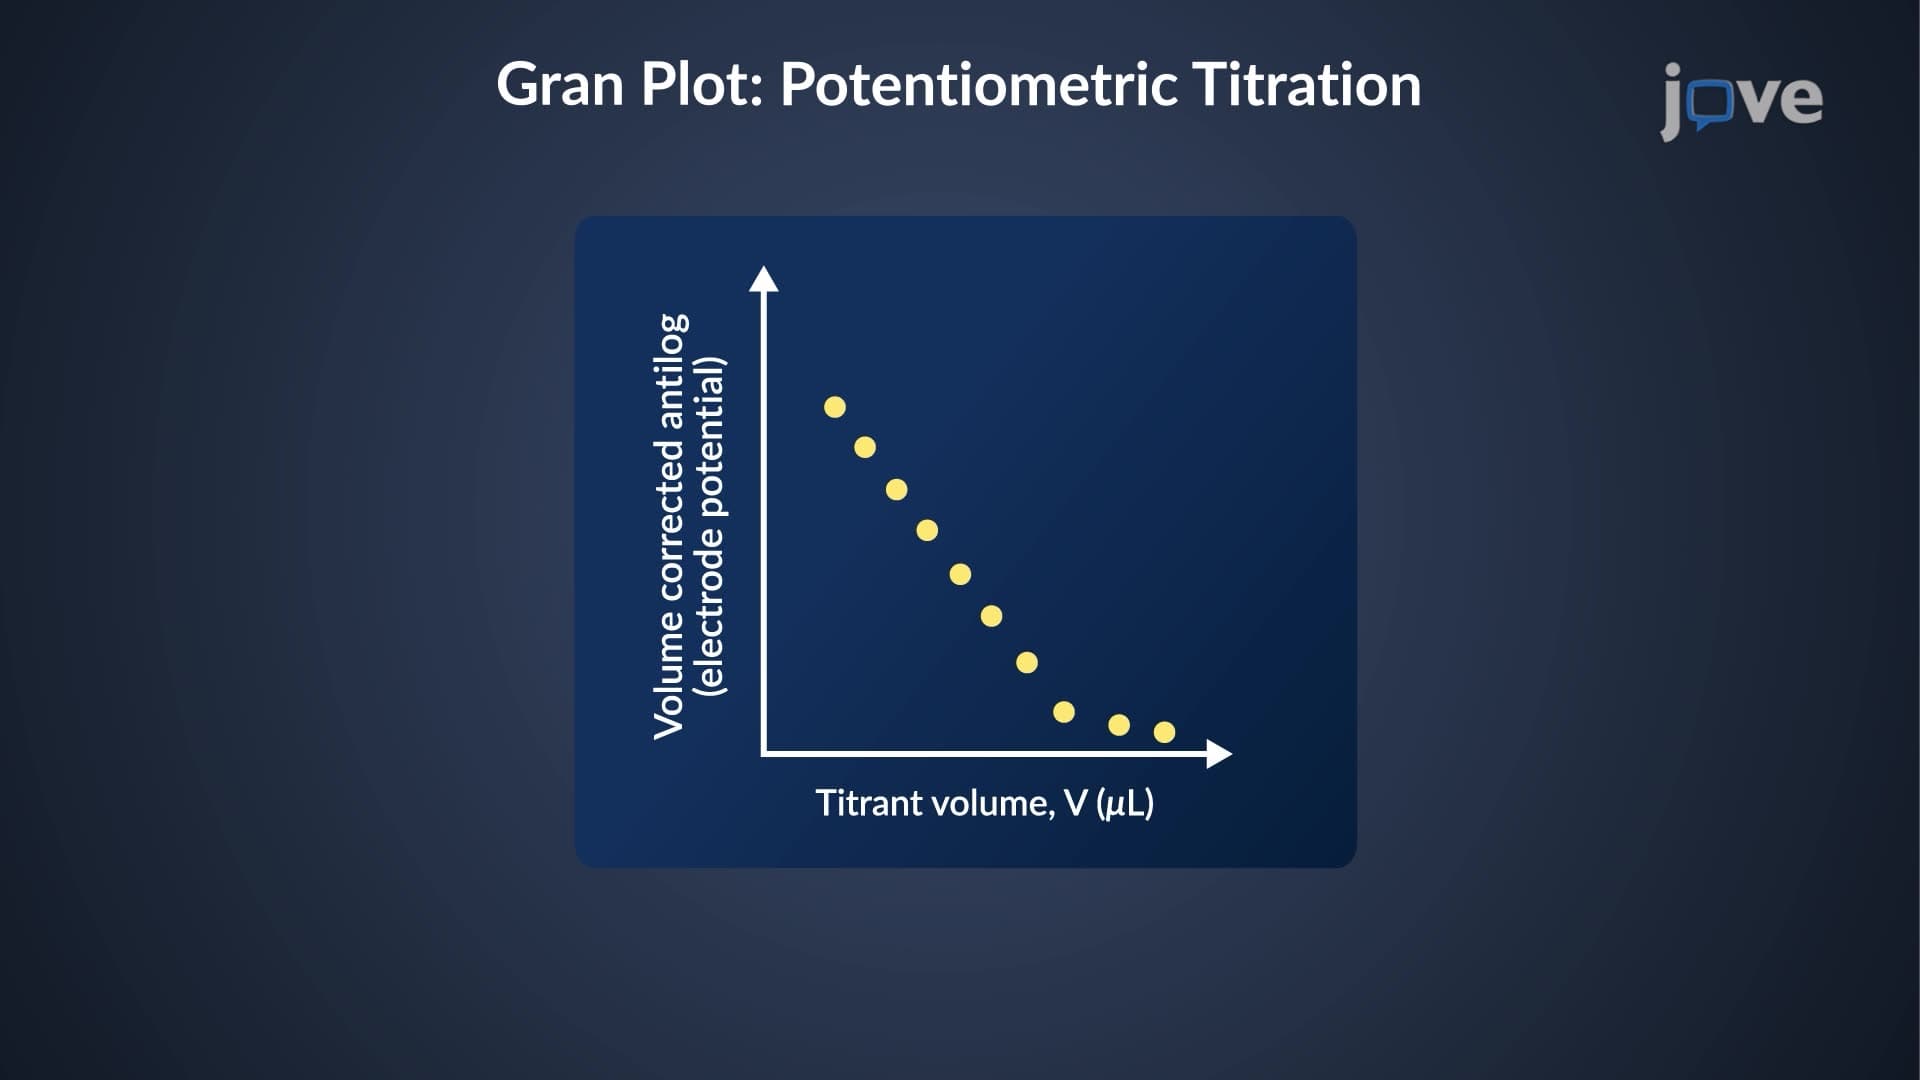
End Point Prediction: Gran Plot
294
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
294
 01:11
Regression Analysis
5.6K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.6K