
使用潜变量建模来识别早产的病因异质性
Kim Steven Betts1, Rosa Alati1, Peter Baker2
1School of Population Health, Curtin University, Perth, Western Australia, Australia.
Journal of paediatrics and child health
|September 21, 2024

概括
一小群患病率高的母亲在连续三次分娩中始终经历过早产. 识别这种高风险子组可以改善对早产的理解和结果.
科学领域:
- 生殖健康 生殖健康
- 围产期流行病学 围产期流行病学
- 孕产妇和胎儿医学 孕产妇和胎儿医学
背景情况:
- 过早分娩仍然是新生儿发病率和死亡率的主要原因.
- 对于有针对性的干预措施来说,识别具有重复早产风险高的母亲至关重要.
- 了解连续分娩多病症和复发的模式对于风险分层至关重要.
研究的目的:
- 为了确定一个特定的母亲的子组在高风险的早产.
- 根据多病症和连续三次分娩中复发的经验性类别来定义这个子组.
主要方法:
- 隐性类分析 (LCA) 用于确定不同的孕产妇健康轨迹.
- 分析了来自澳大利亚昆士兰州7714名母婴母婴,分别连续三次 (2009-2015年) 单胎分娩的数据.
- 评估了与特定类别相关的孕产妇和妊娠相关因素的相关性.
主要成果:
- 一个四类解决方案最好地描述了数据:"规范" (健康),早产/高发病率,分娩发病率和早产/低发病率.
- 一个小但高度病态的班级 (<2%的样本) 始终经历过早产.
- 高发病率和早产,低发病率类别在连续分娩中显示出强烈的连续性,独立于其他因素.
结论:
- 确定了一个独特的,高度病态的母亲类别,经常出现早产.
- 这个子组在连续的分娩中表现出强烈的连续性,这表明固有的风险因素.
- 对这一高风险群体的进一步调查可能会为早产的病因提供见解,并改善出生结果.
更多相关视频
 07:36
Modeling Encephalopathy of Prematurity Using Prenatal Hypoxia-ischemia with Intra-amniotic Lipopolysaccharide in Rats
Published on: November 20, 2015
11.3K
 10:46
A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
10.7K
相关概念视频
 01:11
Variability: Analysis
133
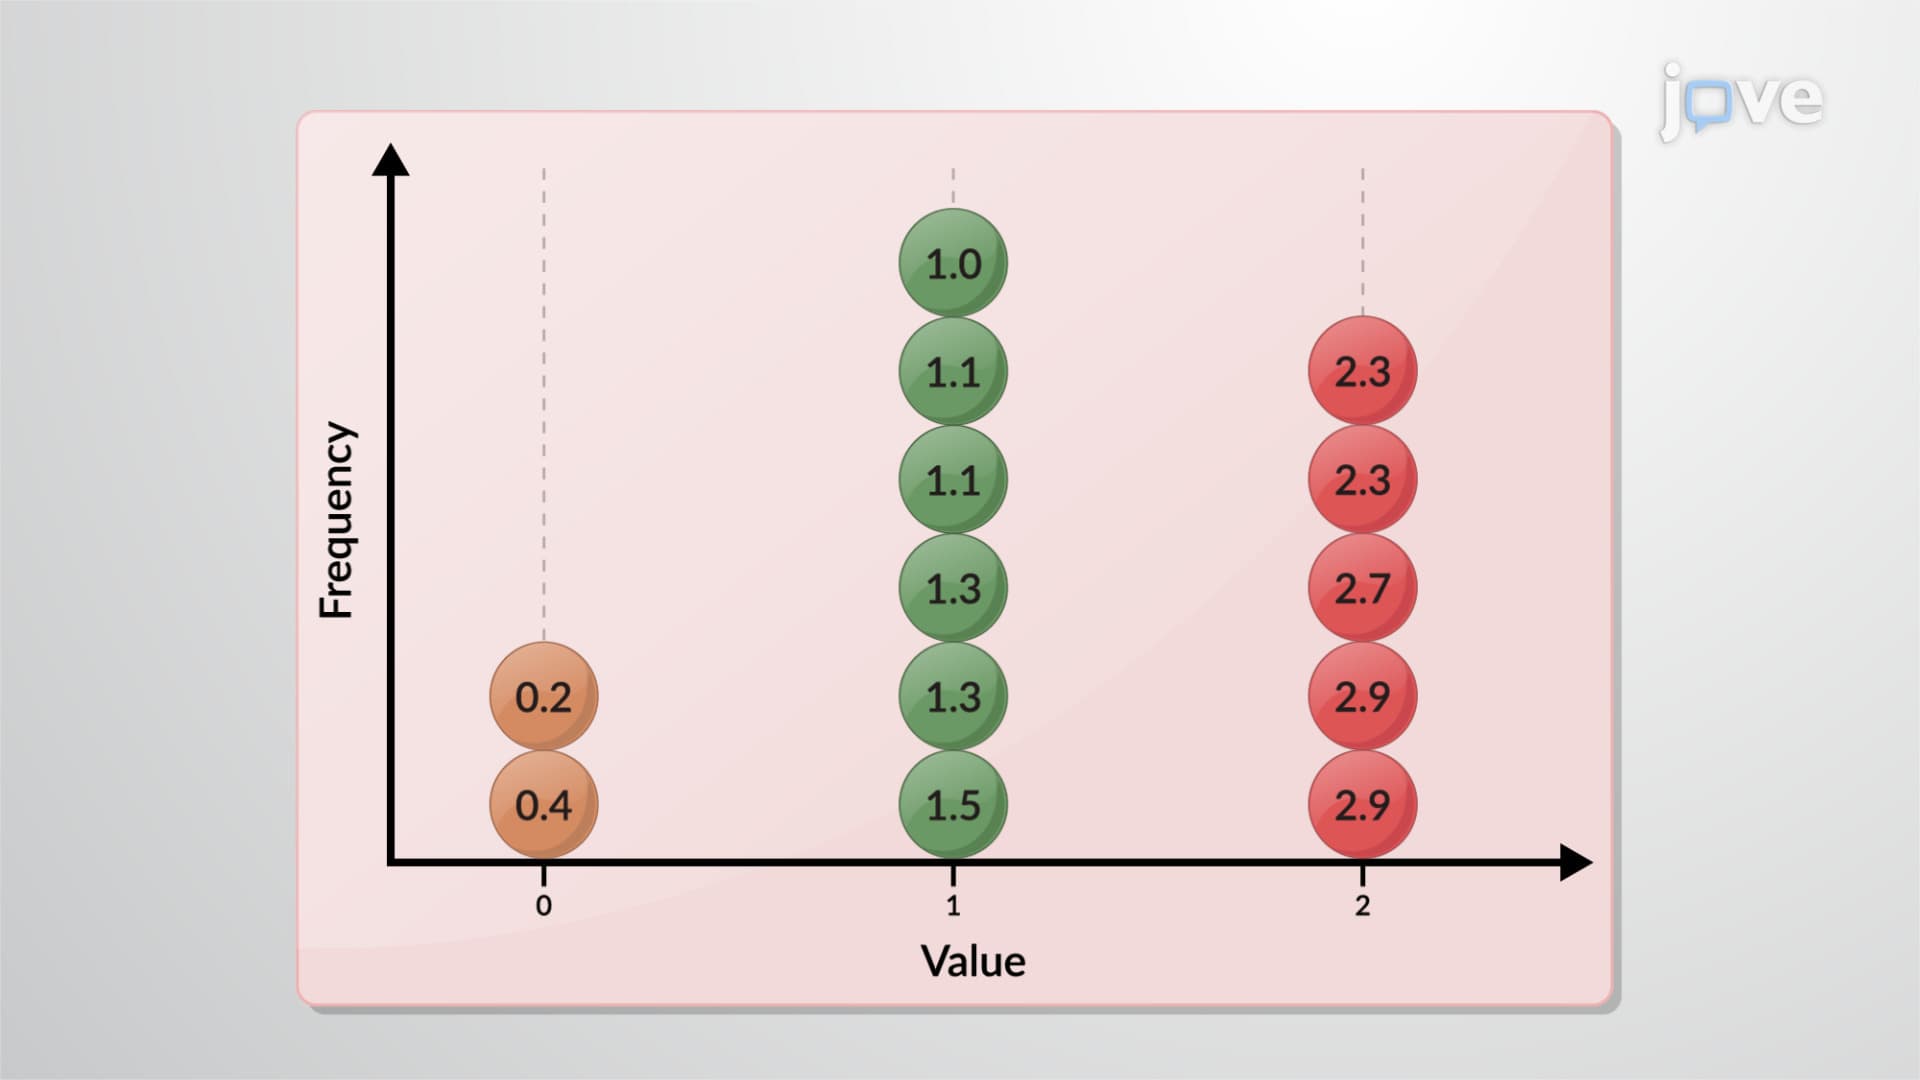
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
133
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:29
Bias in Epidemiological Studies
168
Biases can arise at various stages of research, from study design and data collection to analysis and interpretation. Recognizing and addressing these biases is essential to ensure the validity and reliability of epidemiological findings.Broadly speaking, biases in epidemiology fall into three main categories: selection bias, information bias, and confounding. A more detailed description of possible biases is:
168
 01:27
Confounding in Epidemiological Studies
148
Confounding in statistical epidemiology represents a pivotal challenge, referring to the distortion in the perceived relationship between an exposure and an outcome due to the presence of a third variable, known as a confounder. This variable is associated with both the exposure and the outcome but is not a direct link in their causal chain. Its presence can lead to erroneous interpretations of the exposure's effect, either exaggerating or underestimating the true association. This...
148
 01:26
Longitudinal Studies
142
Longitudinal studies are also widely used in other medical and social science fields. For instance, in cardiovascular research, they can monitor patients' health over decades to identify risk factors for heart disease, such as high cholesterol or smoking, and evaluate the long-term effectiveness of preventive measures. Similarly, in mental health studies, researchers might follow individuals from adolescence into adulthood to understand the development and progression of conditions like...
142
 01:20
Biostatistics: Overview
227
Biostatistics plays a crucial role in understanding and analyzing data in healthcare and biology. Biostatisticians conduct experiments, gather evidence, and draw meaningful conclusions using statistical methods and techniques. Different variables form the foundation of biostatistical analysis, allowing researchers to understand and interpret data effectively. These variables are classified into different types, each serving a specific purpose in statistical analysis.
Discrete variables are...
Discrete variables are...
227