隐藏空间贝叶斯优化与隐藏数据增强用于增强探索

Onur Boyar1, Ichiro Takeuchi2,3
1Department of Mechanical Systems Engineering, Nagoya University, Furo-cho, Chikusa-ku, Nagoya, 4648603, Japan boyar.onur.nagoyaml@gmail.com.
Neural computation
|September 23, 2024

概括
通过解决变化自编码器 (VAE) 和贝叶斯优化 (BO) 之间的不匹配,提高了潜在空间贝叶斯优化 (LSBO). 我们的新方法在新的设计任务中提高了探索和采样效率.
科学领域:
- 人工智能的人工智能
- 机器学习 机器学习
- 计算化学计算化学
背景情况:
- 潜空间贝叶斯优化 (LSBO) 将变化自编码器 (VAE) 等生成模型与贝叶斯优化 (BO) 集成,用于 de novo 对象生成.
- 由于VAE和BO目标之间的不匹配,现有的LSBO方法在勘探中扎,导致效率低下.
- 这种不匹配造成了潜在的不一致性,阻碍了LSBO的有效性.
研究的目的:
- 介绍并解决LSBO中隐藏不一致的问题.
- 提高LSBO的勘探能力和采样效率.
- 开发一种新的LSBO框架,以改善新一代的LSBO.
主要方法:
- 提出了潜在一致性/不一致性的概念来诊断LSBO挑战.
- 开发了一个潜在一致的意识获取函数 (LCA-AF),以利用一致的潜在点.
- 引入LCA-VAE,这是一个VAE变体,采用隐性空间数据增强和不一致性惩罚来促进隐性一致性.
- 结合了LCA-VAE和LCA-AF,创建了LCA-LSBO框架.
主要成果:
- 拟议的LCA-LSBO框架显示了高样本效率.
- 通过解决潜在的不一致性,可以实现有效的勘探能力.
- 在LCA-VAE中新的隐性空间数据增强的整合显著改善了LSBO性能.
结论:
- 解决潜在一致性对于提高LSBO效率和勘探至关重要.
- 结合了LCA-VAE和LCA-AF的LCA-LSBO,为新一代任务提供了一个强大的解决方案.
- 这项研究强调了潜在空间数据增强在增强基于生成模型的优化方面的有效性.
相关概念视频
 01:13
Randomized Experiments
6.8K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
6.8K
 02:07
Improving Translational Accuracy
9.4K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
9.4K
 01:16
Experimental Designs
11.1K
An experimental design is a systematic process that allows researchers to evaluate the relationship between dependent and independent variables. There are three widely used types of experimental design - pre-experimental design, true experimental design, and quasi-experimental design. In pre-experimental design, the researcher compares the data before and after some interventions or treatments. The true-experimental design has more than one purposefully created group, a commonly measured...
11.1K
 01:09
Random Variables
11.4K
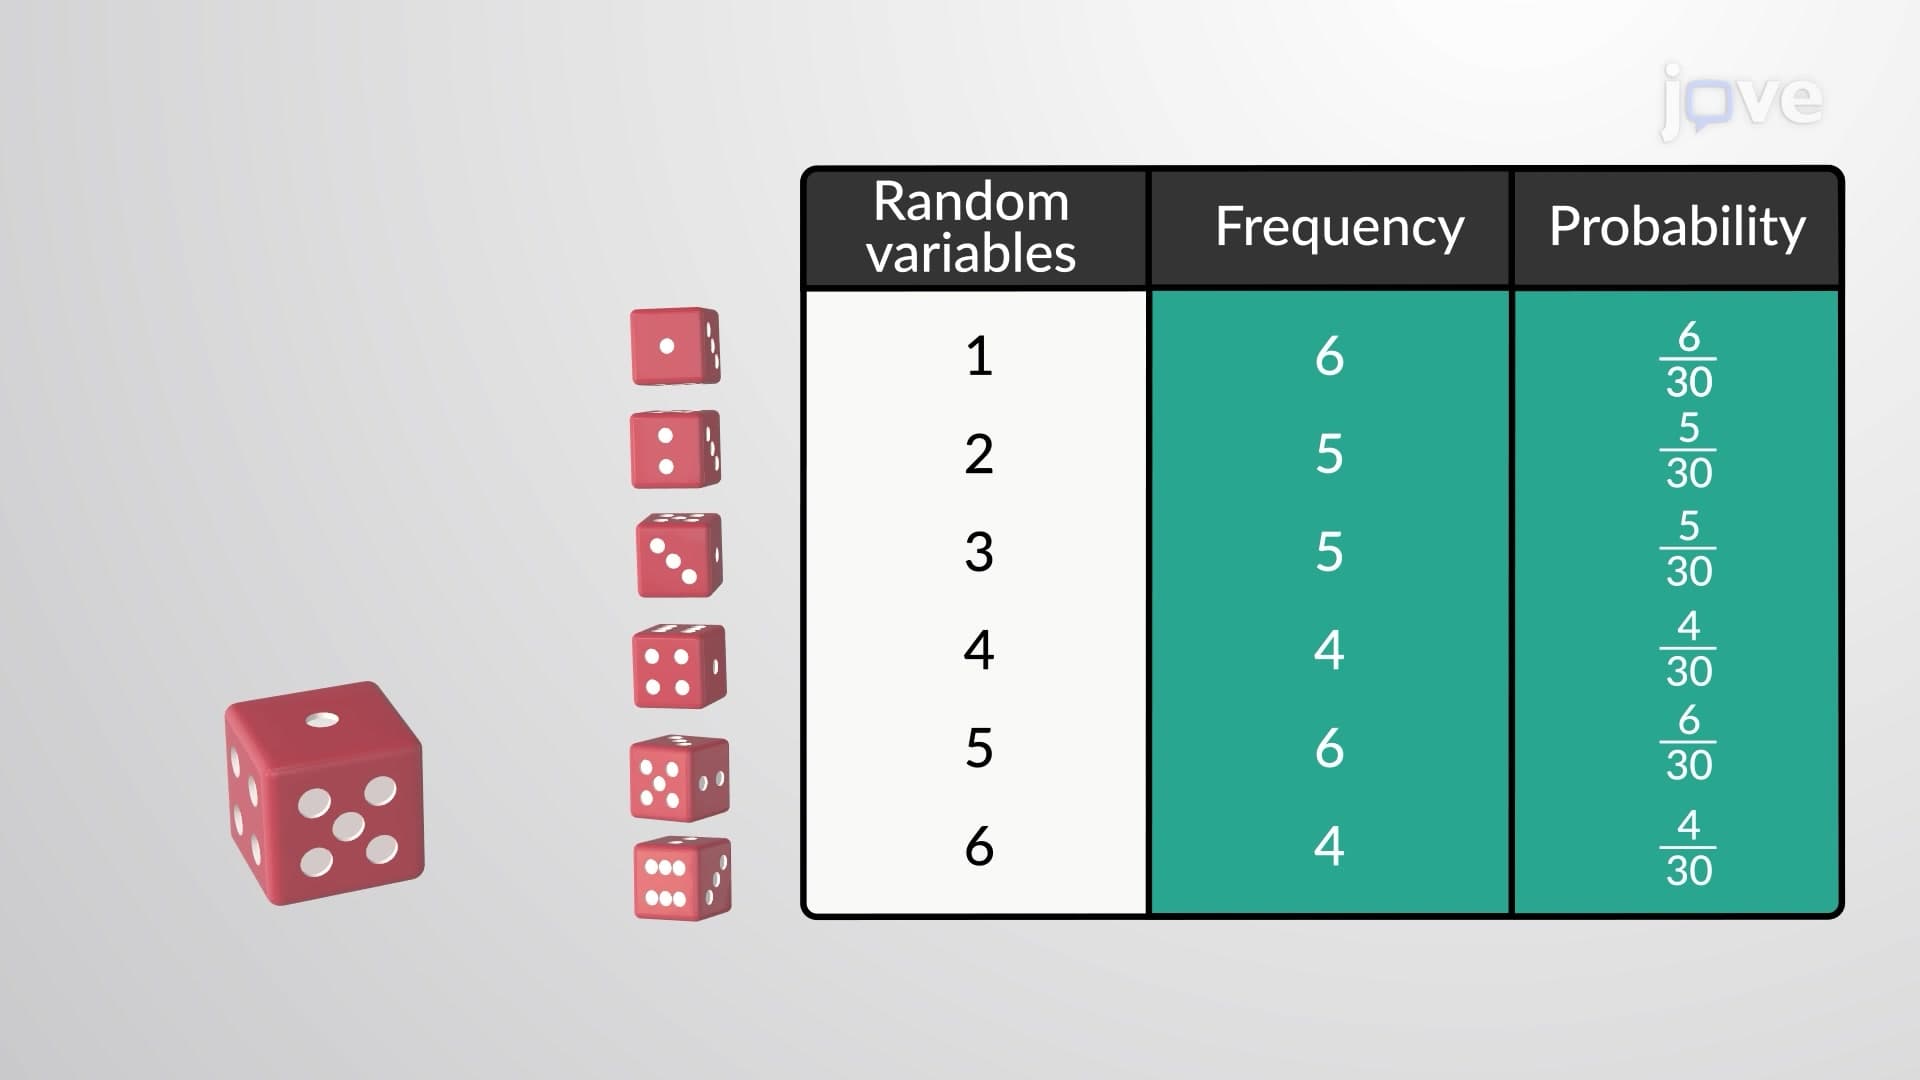
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
11.4K
 01:20
Cluster Sampling Method
11.8K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
11.8K
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
421
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
421