相关实验视频
Updated: Jun 11, 2025

05:37

An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
2.0K
了解在随机森林中的过,以估计概率:一个可视化和模拟研究
Lasai Barreñada1,2, Paula Dhiman3, Dirk Timmerman1,4
1Department of Development and Regeneration, Leuven, KU, Belgium.
Diagnostic and prognostic research
|September 28, 2024

概括
随机森林为临床风险预测创造了概率"尖峰",导致了高训练的AUC. 然而,这些峰值不会显著损害测试数据的性能,尽管完全成长的树木可能不是最佳的概率估计.
科学领域:
- 机器学习 机器学习
- 生物统计学 生物统计学
- 临床风险预测预测
背景情况:
- 随机森林对于临床风险预测非常受欢迎.
- 在一个案例研究中观察到接近1的高训练AUC,这表明潜在的过拟合.
- 该研究调查了概率估计中的随机森林行为.
研究的目的:
- 了解用于概率估计的随机森林行为.
- 在现实世界的案例研究和模拟研究中可视化数据空间.
- 评估模型参数对性能的影响.
主要方法:
- 视觉化风险估计使用热图在2D子空间的案例研究.
- 通过48个物流数据生成机制 (DGM) 进行了模拟研究.
- 多种预测器分布,预测器的数量/相关性,真实AUC和预测器强度;使用Ranger R包训练随机森林模型.
主要成果:
- 视觉化显示了训练数据事件周围的"概率峰值".
- 培训中位数AUC高 (0.97-1),除非满足特定预测因素/节点大小条件.
- 差异化损失中等 (中位数为0.025),测试AUC受每个变量,节点大小和预测器类型事件的影响.
结论:
- 随机森林学习本地概率峰值,通常导致近乎完美的训练AUCs.
- 这些峰值通常不会严重影响测试数据的AUC.
- 对于概率估计,结果挑战了在随机森林模型中使用完全成长的树木的建议.
相关概念视频
 01:19
Survival Tree
63
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
63
 01:17
Probability Histograms
11.1K
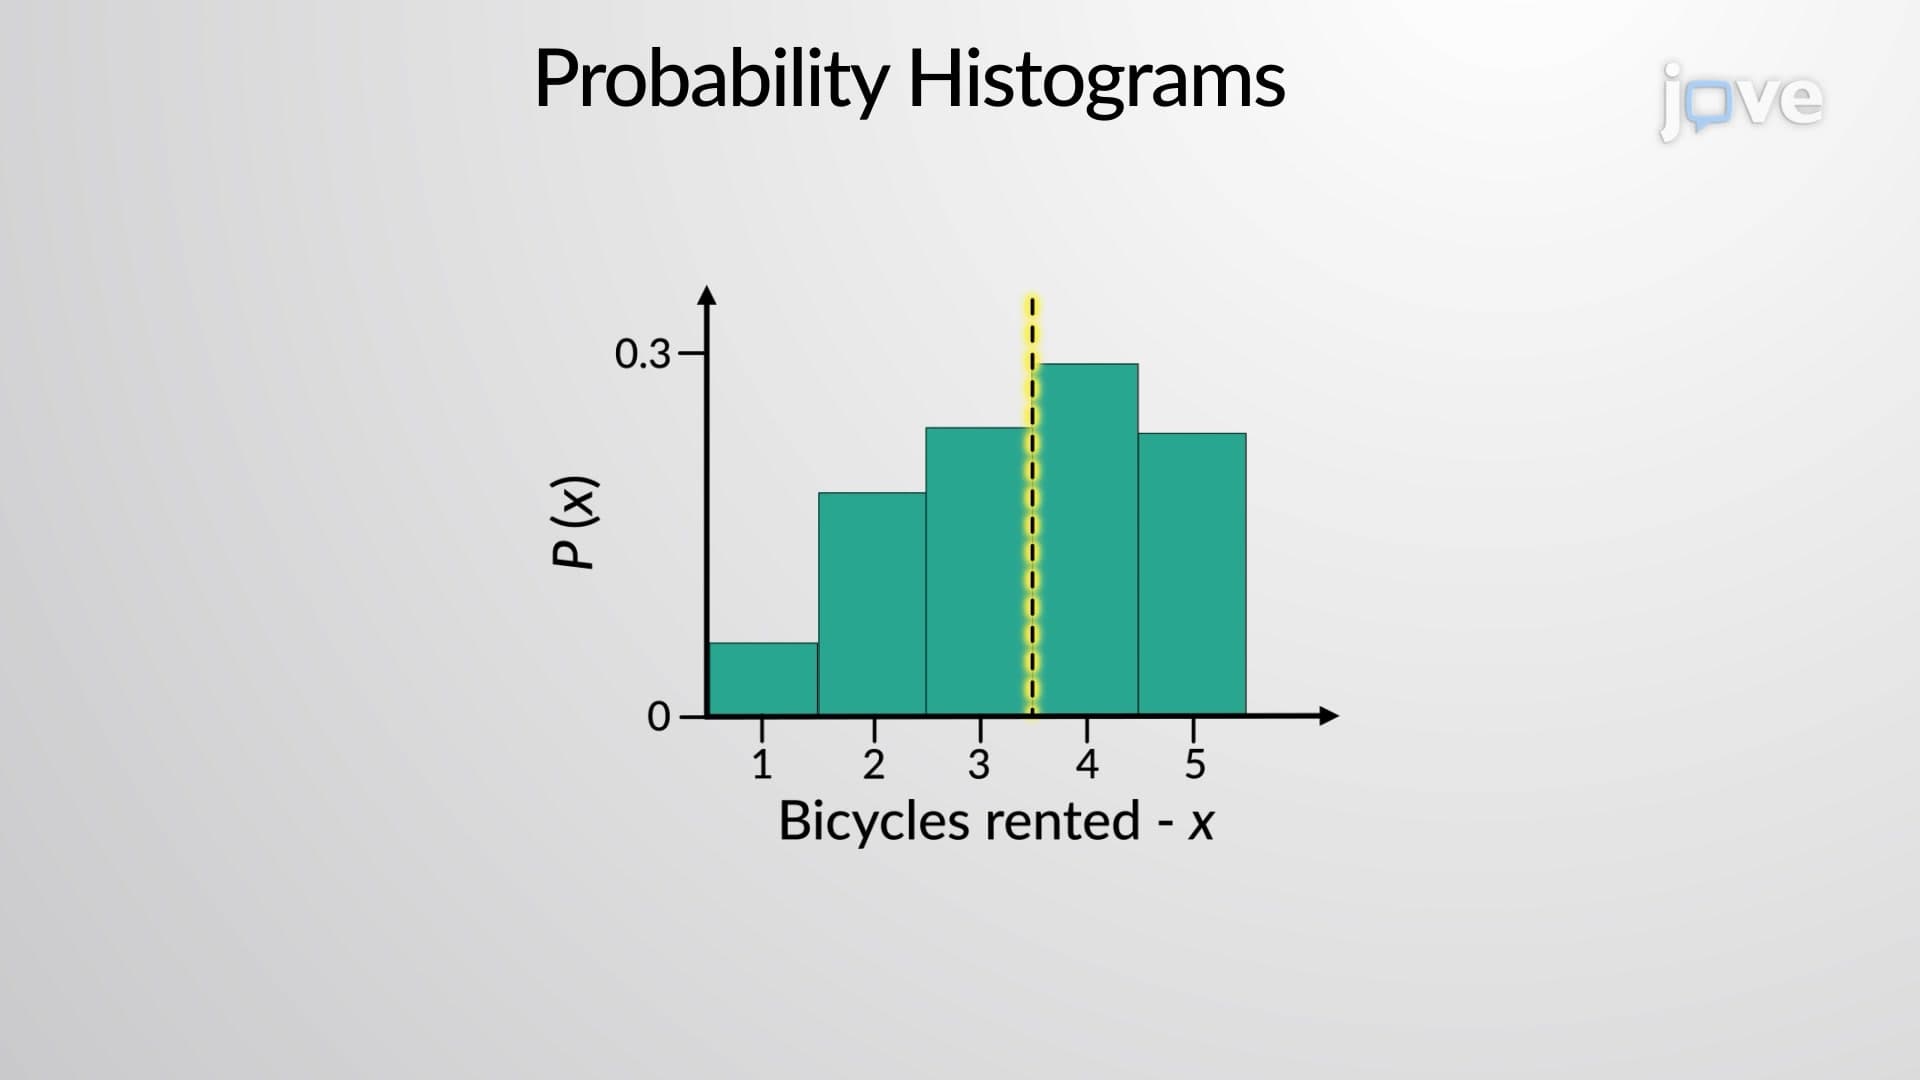
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
11.1K
 01:14
Probability in Statistics
12.4K
Probability is the likelihood of an event occurring. The term event is defined as a collection of results of a procedure. An event is a simple event when an outcome cannot be divided into simpler parts.
An example of a simple event is a coin toss. The result of a coin toss is either a head or a tail. Here, head and tail are two simple events. These two simple events make up the sample space. Further, the probability of an event occurring falls within the range of 0 to 1. The probability of an...
An example of a simple event is a coin toss. The result of a coin toss is either a head or a tail. Here, head and tail are two simple events. These two simple events make up the sample space. Further, the probability of an event occurring falls within the range of 0 to 1. The probability of an...
12.4K
 01:32
Probability Distributions
6.8K
The probability of a random variable x is the likelihood of its occurrence. A probability distribution represents the probabilities of a random variable using a formula, graph, or table. There are two types of probability distribution– discrete probability distribution and continuous probability distribution.
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
6.8K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:04
Random Error
843
Random or indeterminate errors originate from various uncontrollable variables, such as variations in environmental conditions, instrument imperfections, or the inherent variability of the phenomena being measured. Usually, these errors cannot be predicted, estimated, or characterized because their direction and magnitude often vary in magnitude and direction even during consecutive measurements. As a result, they are difficult to eliminate. However, the aggregate effect of these errors can be...
843