

概括
本研究开发了用于估计贝叶斯网络中规范精度矩阵自身值的方法. 偏差校正和收缩估计器提高了准确性,特别是对于极端的固有值.
科学领域:
- 统计 统计 统计 统计
- 机器学习 机器学习
- 贝叶斯网络 贝叶斯网络 贝叶斯网络
背景情况:
- 贝叶斯网络的光谱理论需要对规范精度矩阵进行强大的估计方法.
- 现有的自值估计方法可能会受到偏差的影响,特别是在某些数据条件下.
研究的目的:
- 为了推导异面分布的样本固有值的规范精度矩阵.
- 为这些固有值开发一个二阶偏差校正公式.
- 提出一个斯坦式收缩估计器,以改进自身值估计.
主要方法:
- 对于样本固有值的多变量正常异常分布的推导.
- 开发一个二级偏差校正公式.
- 施工一个斯坦式收缩估计器.
- 数字模拟用于比较估计技术.
主要成果:
- 在一般和正常人口条件下,为样本固有值提供了非对称分布.
- 建立了第二级偏差校正公式.
- 建议使用斯坦式收缩估计器.
- 模拟表明基于自身值大小的不同方法的有效性.
结论:
- 第二阶偏差校正自值估计器在最大自值很小时显著减少偏差.
- 对于最小的自值,样本自值或收缩估计器显示的偏差较小.
- 这项研究为贝叶斯网络的统计推理提供了有价值的工具.
相关概念视频
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
411
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
411
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:15
Chebyshev's Theorem to Interpret Standard Deviation
4.1K
Chebyshev’s theorem, also known as Chebyshev’s Inequality, states that the proportion of values of a dataset for K standard deviation is calculated using the equation:
4.1K
 01:24
Confidence Coefficient
7.5K
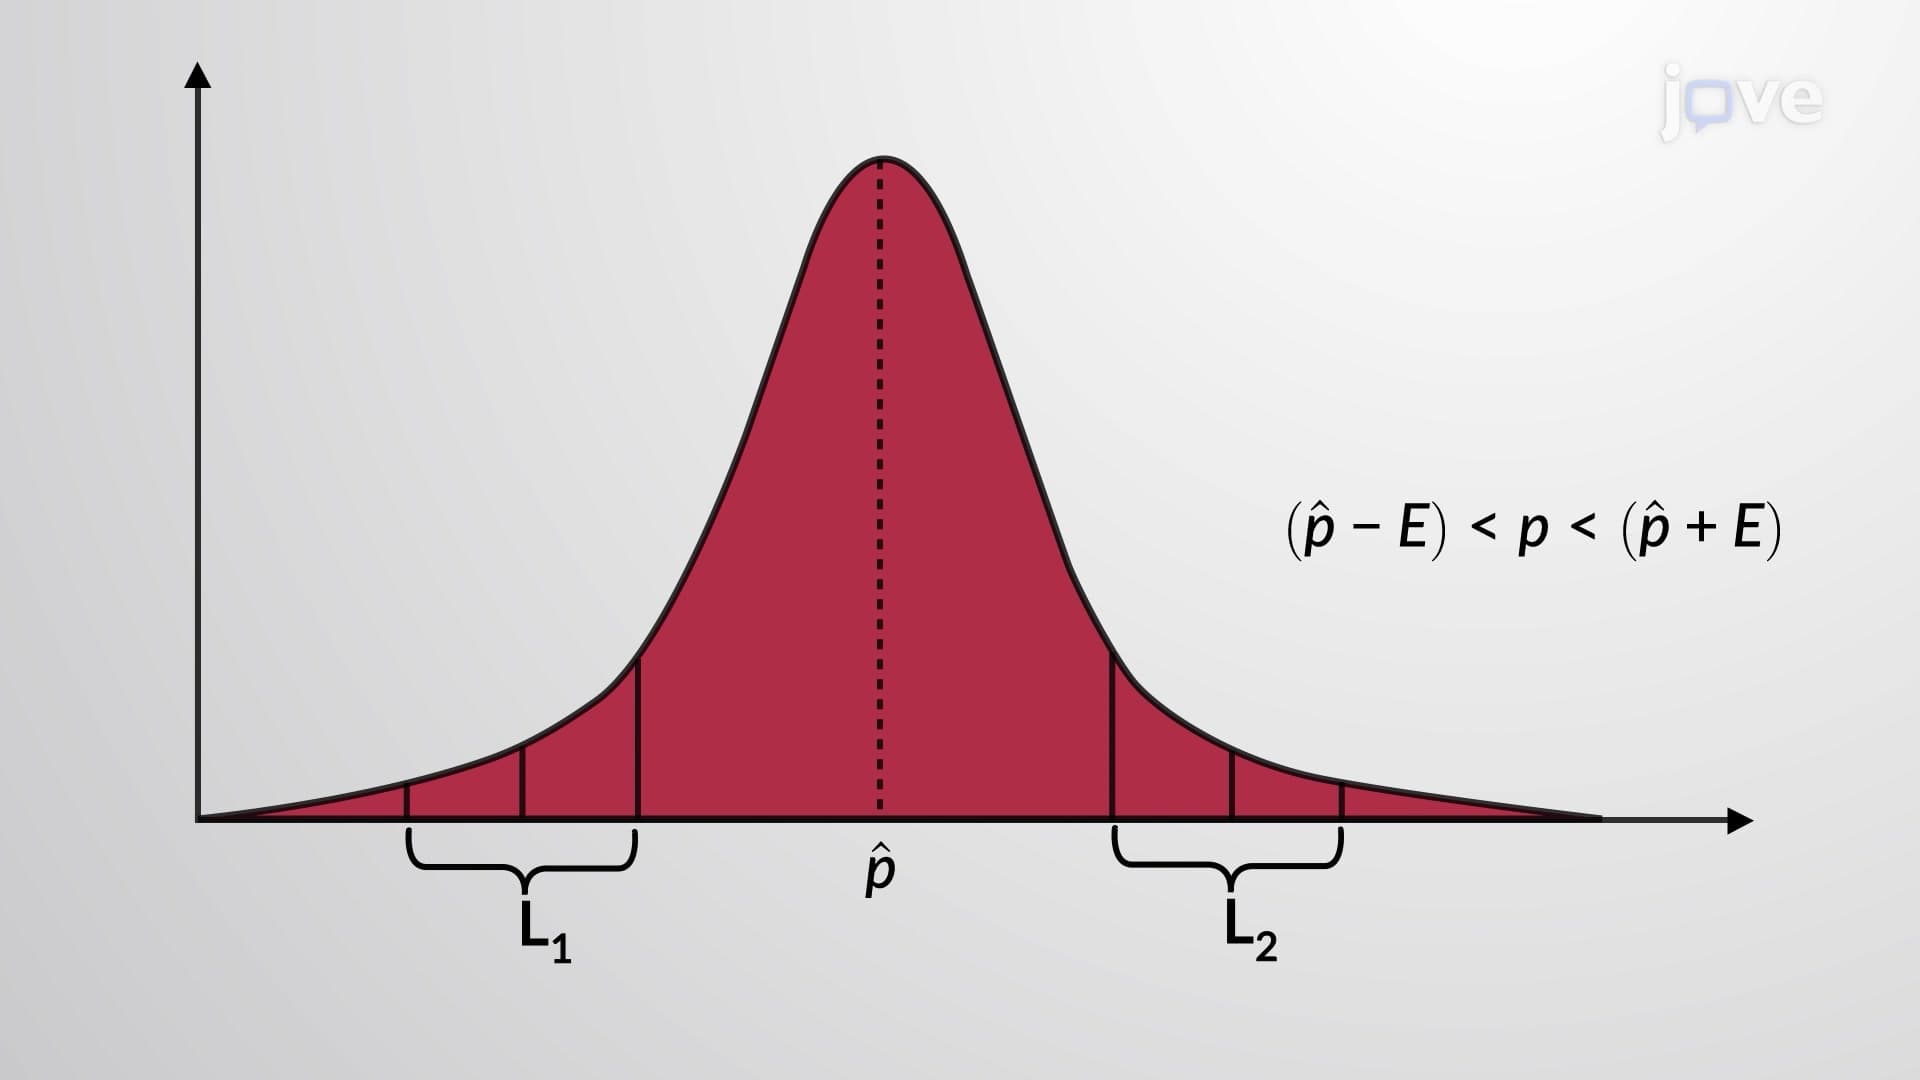
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.5K
 03:37
Uncertainty in Measurement: Accuracy and Precision
73.5K
Scientists typically make repeated measurements of a quantity to ensure the quality of their findings and to evaluate both the precision and the accuracy of their results. Measurements are said to be precise if they yield very similar results when repeated in the same manner. A measurement is considered accurate if it yields a result that is very close to the true or the accepted value. Precise values agree with each other; accurate values agree with a true value.
73.5K
 01:08
Vector Algebra: Method of Components
13.8K
It is cumbersome to find the magnitudes of vectors using the parallelogram rule or using the graphical method to perform mathematical operations like addition, subtraction, and multiplication. There are two ways to circumvent this algebraic complexity. One way is to draw the vectors to scale, as in navigation, and read approximate vector lengths and angles (directions) from the graphs. The other way is to use the method of components.
In many applications, the magnitudes and directions of...
In many applications, the magnitudes and directions of...
13.8K