

预测中国股票指数的波动性,基于实现的循环条件异构性
Gongtao Zhang1, Huanyu Zhao1, Rujie Fan1
1School of Finance, China Academy of Financial Research, Southwestern University of Finance and Economics, Chengdu, China.
PloS one
|October 18, 2024

概括
整合LSTM与RealGARCH的RealRECH模型显示,中国股票指数的样本适应性得到改善. 它可以更好地预测CSI500和CSI1000的波动性,但不能预测SSE50和CSI300.
科学领域:
- 金融计量经济学 金融计量经济学
- 机器学习在金融中的应用.
- 时间序列分析时间序列分析.
背景情况:
- 通过将长短期内存 (LSTM) 纳入RealGARCH模型,RealRECH模型提高了波动性预测.
- 现有的文献缺乏关于RealRECH模型在中国金融市场的表现的研究.
研究的目的:
- 评估RealRECH模型对中国股票指数 (SSE50,CSI300,CSI500,CSI1000) 的样本内可解释性和样本外预测准确性.
- 为了比较RealRECH模型与RealGARCH模型在中国市场的性能.
主要方法:
- 将RealRECH模型应用于SSE50,CSI300,CSI500和CSI1000指数的应用.
- 在样本中的适合性分析.
- 在样本之外的波动性预测评估.
主要成果:
- 在所有四个指数中,RealRECH模型表现出优异的样本内可解释性.
- RealRECH捕获了复杂的波动动力学,包括长期依赖性和非线性,而RealGARCH错过了这一点.
- 样本之外的结果表明,RealRECH在CSI500和CSI1000方面表现优于RealGARCH,但在SSE50和CSI300方面表现不佳.
结论:
- 该RealRECH模型提供了增强的样本内匹配,并捕捉了复杂的波动动态.
- 该模型的预测性能在中国股票指数之间有所不同,对于CSI500和CSI1000波动性预测是有效的.

相关概念视频
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:22
Estimating Population Mean with Unknown Standard Deviation
7.6K
In practice, we rarely know the population standard deviation. In the past, when the sample size was large, this did not present a problem to statisticians. They used the sample standard deviation s as an estimate for σ and proceeded as before to calculate a confidence interval with close enough results. However, statisticians ran into problems when the sample size was small. A small sample size caused inaccuracies in the confidence interval.
William S. Gosset (1876–1937) of the...
William S. Gosset (1876–1937) of the...
7.6K
 01:26
Estimating Population Standard Deviation
3.0K
When the population standard deviation is unknown and the sample size is large, the sample standard deviation s is commonly used as a point estimate of σ. However, it can sometimes under or overestimate the population standard deviation. To overcome this drawback, confidence intervals are determined to estimate population parameters and eliminate any calculation bias accurately. However, this only applies to random samples from normally distributed populations. Knowing the sample mean and...
3.0K
 01:09
Empirical Method to Interpret Standard Deviation
5.1K
The empirical rule, also known as the three-sigma rule, allows a statistician to interpret the standard deviation in a normally distributed dataset. The rule states that 68% of the data lies within one standard deviation from the mean, 95% lies within two standard deviations from the mean, and 99.7% lies within three standard deviations from the mean. Additionally, this rule is also called the 68-95-99.7 rule.
This rule is used widely in statistics to calculate the proportion of data values...
This rule is used widely in statistics to calculate the proportion of data values...
5.1K
 01:16
Estimating Population Mean with Known Standard Deviation
8.3K
To construct a confidence interval for a single unknown population mean μ, where the population standard deviation is known, we need sample mean as an estimate for μ and we need the margin of error. Here, the margin of error (EBM) is called the error bound for a population mean (abbreviated EBM). The sample mean is the point estimate of the unknown population mean μ.
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate +...
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate +...
8.3K
 01:19
Variation
6.7K
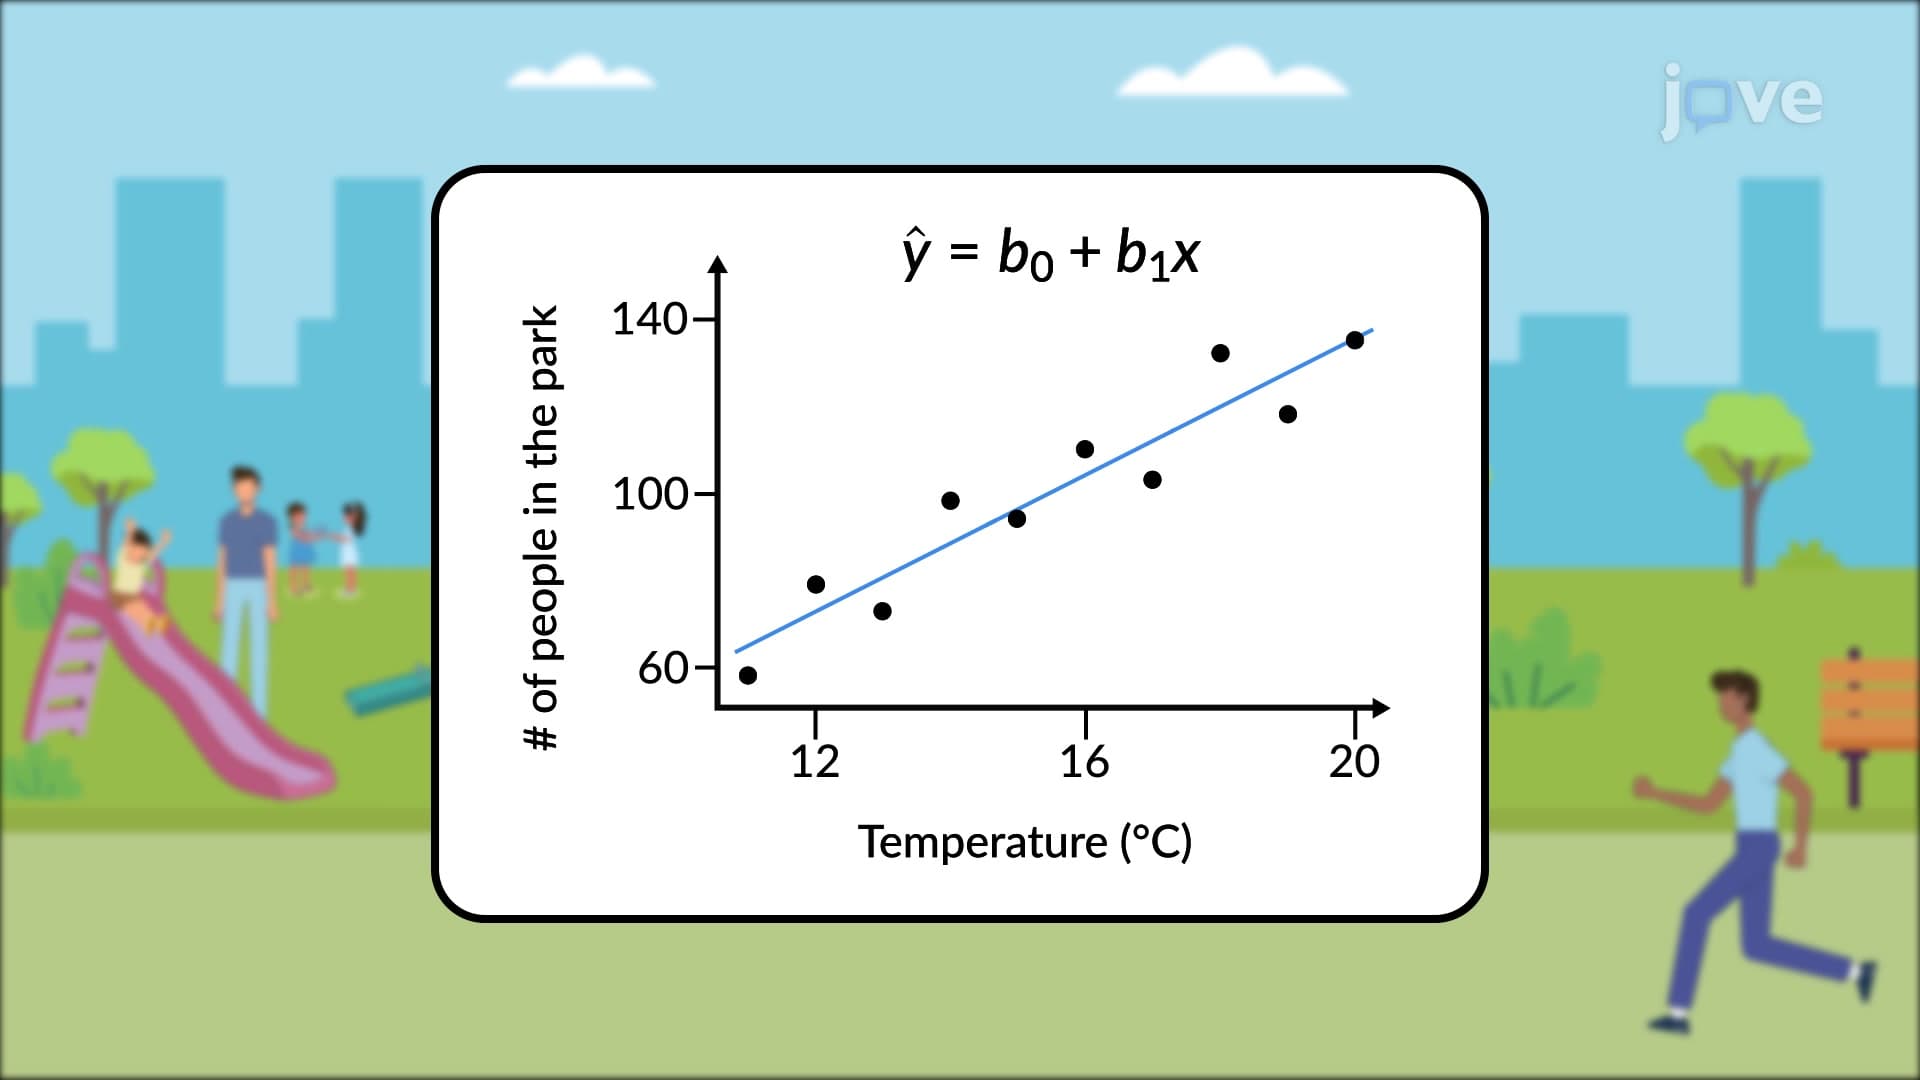
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.7K