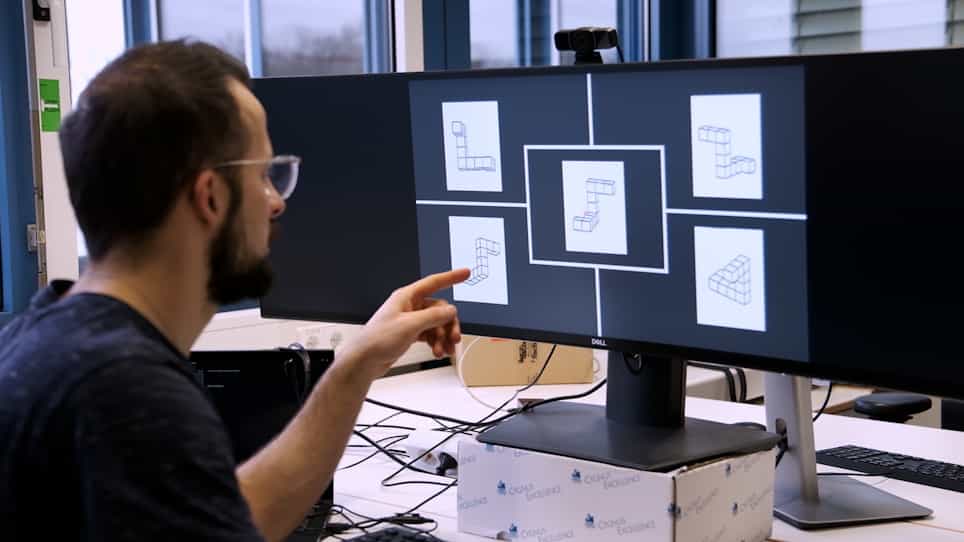
异常值和熟悉环境对趋势线估计在分散图中的影响
Başak Oral1, Aysecan Boduroglu2
1Department of Information and Computing Science, Utrecht University, Utrecht, Netherlands.
Memory & cognition
|October 21, 2024

概括
了解散射图涉及到视觉感知. 熟悉的背景和适合的异常值影响趋势线估计,显示先前的信念影响数据解释.
科学领域:
- 认知心理学 认知心理学
- 数据可视化 数据可视化
- 人与计算机的交互
背景情况:
- 研究将视觉感知原则与数据可视化技术相结合.
- 集体感知,即从视觉集合中快速掌握信息的能力,与散射图处理相关地进行了探索.
研究的目的:
- 调查分散图中的异常值如何影响趋势线估计.
- 检查熟悉度和异常趋势一致性对散点图中趋势线绘制的影响.
主要方法:
- 两项实验向参与者提供了时间有限的分散图,有和没有异常值.
- 参与者使用计算机鼠标估计了趋势线.
- 估计与潜在的趋势线解决方案进行了比较.
主要成果:
- 在没有上下文的情况下,异常值和数据点同样影响了趋势线估计.
- 熟悉的背景和趋势匹配的异常值导致参与者过度重视异常值对趋势线估计的影响.
结论:
- 预先的知识和信念可以显著影响个人如何感知和解释分散图中的数据.
- 异常值对趋势估计的影响取决于上下文,并受熟悉度的影响.
更多相关视频
 04:35
Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
3.3K
 07:59
Author Spotlight: Alignment of Synchronized Time-Series Data Using the Characterizing Loss of Cell Cycle Synchrony Model for Cross-Experiment Comparisons
Published on: June 9, 2023
1.3K
相关概念视频
 01:08
Outliers and Influential Points
4.0K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.0K
 01:12
What Are Outliers?
3.6K
Outliers are observed data points that are far from the least squares line. They have unusual values and need to be examined carefully. Though an outlier may result from erroneous data, at other times, it may hold valuable information about the population under study and should be included in the data. Hence, it is crucial to examine what causes a data point to be an outlier.
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
3.6K
 01:15
Scatter Plot
6.8K
The most common and easiest way to display the relationship between two variables, x and y, is a scatter plot. A scatter plot shows the direction of a relationship between the variables. A clear direction happens when there is either:
6.8K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.5K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.5K
 01:00
Detection of Gross Error: The Q Test
5.6K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
5.6K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K