
基于TabNet堆叠的信用违约预测模型的研究
Shijie Wang1,2, Xueyong Zhang1
1School of Finance, Central University of Finance and Economics, Beijing 102206, China.
Entropy (Basel, Switzerland)
|October 25, 2024

概括
本研究介绍了一种使用TabNeT-Stacking的高级信用违约预测模型. 这种新的方法比金融技术应用的传统方法提高了准确性和性能.
科学领域:
- 机器学习 机器学习
- 金融技术 金融技术
- 数据科学数据科学数据科学
背景情况:
- 传统的信用违约预测模型与金融技术的需求作斗争.
- 基于经验和单一网络的模型缺乏当前金融格局的复杂性.
研究的目的:
- 使用TabNeT-Stacking提出一个改进的信用违约预测模型.
- 提高金融技术中信用违约预测的准确性和性能.
主要方法:
- 使用PyTorch.开发了一个改进的TabNet结构.
- 通过多种群遗传算法优化特征选择,通过粒子群优化优化超参数.
- 雇员堆叠集体学习,使用改进的TabNet进行特征提取,XGBoost,LightGBM,CatBoost,KNN和SVM作为基础学习者,XGBoost作为meta-learner.
主要成果:
- 拟议的TabNeT-Stacking模型显著超过了原始模型的性能.
- 在准确性,精度,回忆,F1得分和曲线下面面积 (AUC) 中表现出卓越的性能.
结论:
- TabNeT-Stacking模型为信用违约预测提供了一个强大而有效的解决方案.
- 深度学习和整体方法的整合在金融风险评估方面取得了重大进展.
相关概念视频
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:19
Survival Tree
61
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
61
 01:07
End Point Prediction: Gran Plot
281
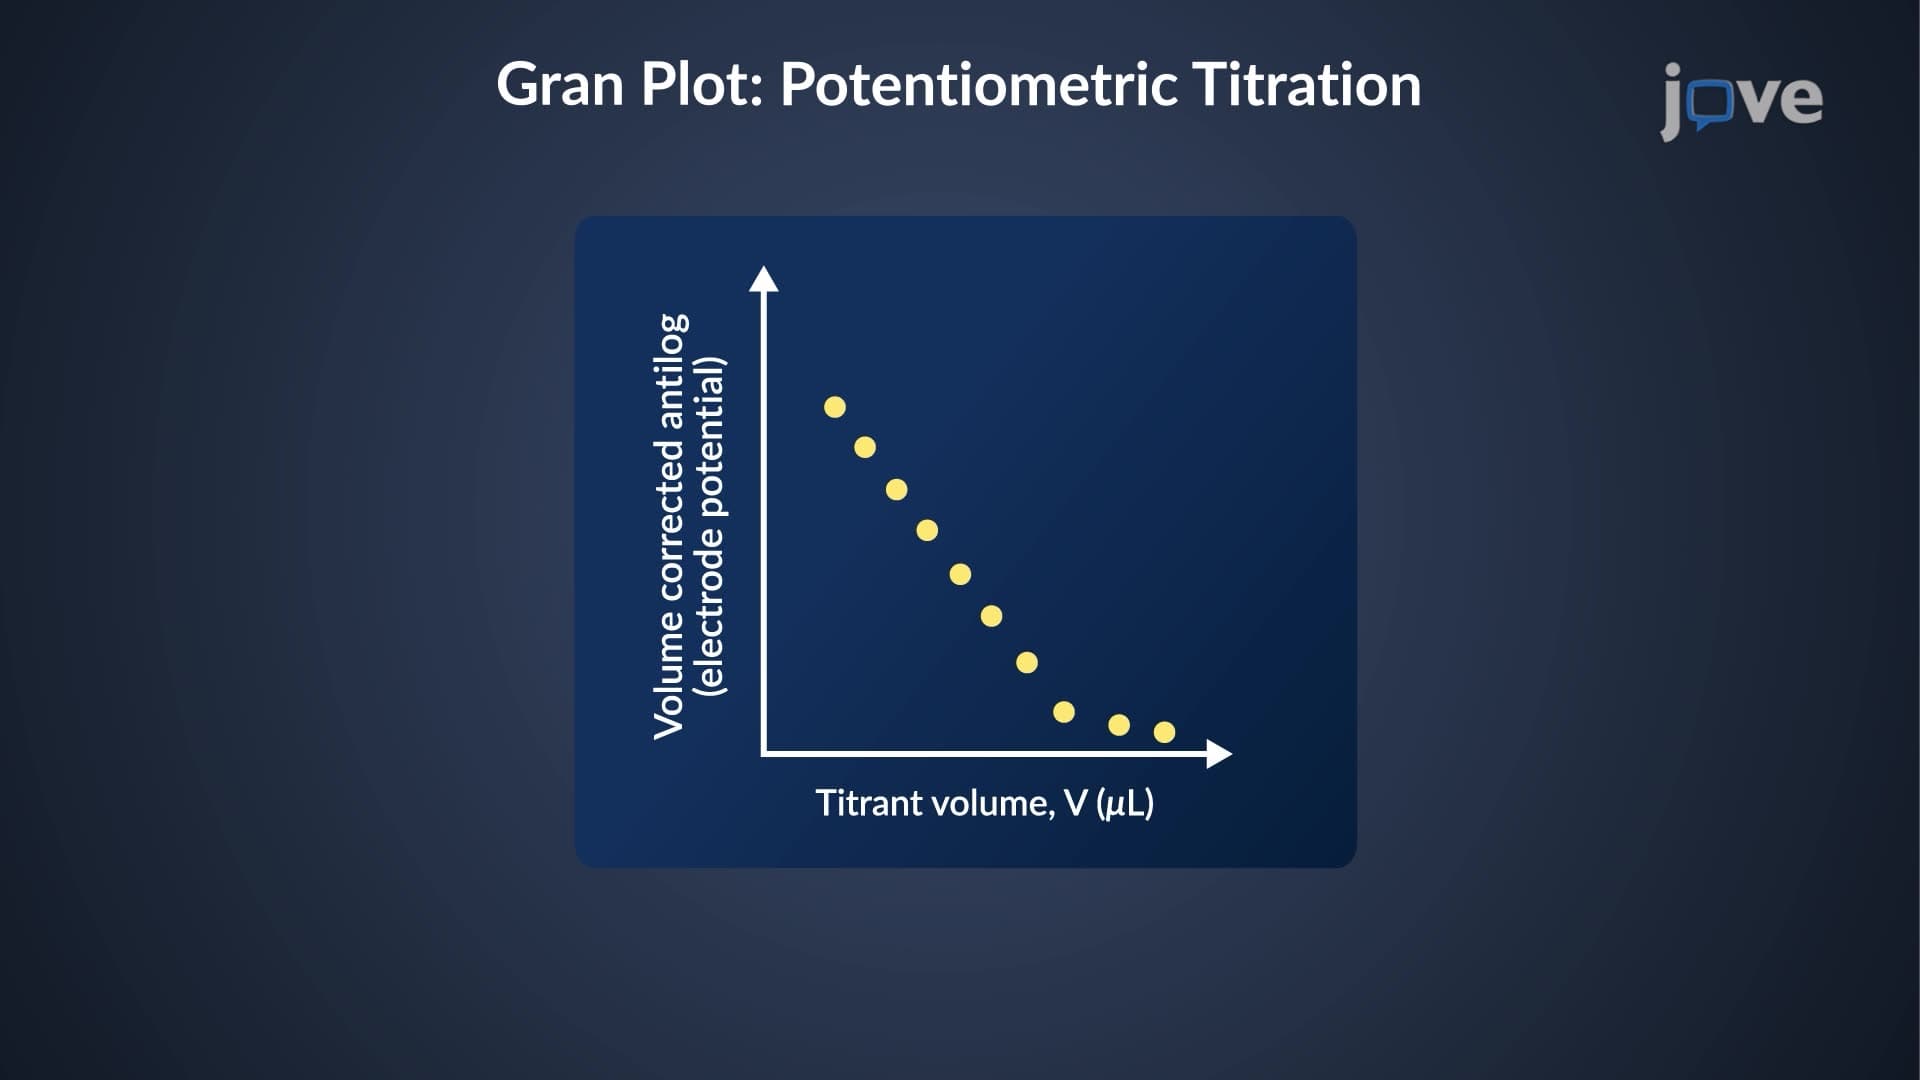
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
281
 01:29
Aggregates Classification
305
Aggregate classification is generally based on its size, petrographic characteristics, weight, and source. Size classification ranges from coarse to fine aggregates, defined by the size of the particles. Coarse aggregates are particles that do not pass through ASTM sieve No. 4, and aggregates that pass through the sieve are fine aggregates.
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
305
 01:25
Multiple Regression
2.9K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
2.9K
 01:11
Regression Analysis
5.6K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.6K