
关于SVM模型用于预测孟加拉国婴儿死亡率的解释性
Md Abu Sayeed1, Azizur Rahman2, Atikur Rahman2
1Department of Statistics and Data Science, Jahangirnagar University, Dhaka, Bangladesh. sayeed@juniv.edu.
Journal of health, population, and nutrition
|October 27, 2024

概括
这项研究使用可解释机器学习 (ML) 来分析孟加拉国的婴儿死亡率. 虽然逻辑回归 (LR) 预测得更好,但可解释支向量机 (SVM) 确定了婴儿死亡的特定风险因素.
科学领域:
- 公共卫生 公共卫生
- 机器学习 机器学习
- 数据科学数据科学数据科学
背景情况:
- 婴儿死亡率仍然是一个关键的全球公共卫生问题,影响社会和经济发展.
- 机器学习 (ML) 模型提供了高的预测性能,但往往缺乏可解释性,阻碍了信任和应用.
- 可解释的ML旨在弥合这一差距,将预测能力与复杂决策的透明解释相结合.
研究的目的:
- 应用先进的可解释机器学习技术来预测和理解影响孟加拉国婴儿死亡率的因素.
- 通过使用可解释支向量机 (SVM) 模型,克服传统的逻辑回归 (LR) 的局限性.
- 为公共卫生政策和家庭咨询服务提供可操作的见解.
主要方法:
- 利用了孟加拉国人口与健康调查 (BDHS) 2017-18年的数据.
- 使用可解释支向量机器 (SVM) 采用全球代用和本地个人条件预期 (ICE) 技术.
- 将SVM与后勤回归 (LR) 进行比较,通过ROC曲线,运行时间和混矩阵评估性能,超过100次排列.
主要成果:
- 后勤回归 (LR) 显示了更高的准确性 (0.9105),但无法预测阳性病例,并且运行时间较慢.
- 可解释的SVM确定了特定的风险因素:正常的BMI,短的分娩间隔,较少污染的燃料,工作的母亲和男婴与更高的婴儿死亡风险有关.
- 用SVM进行的全球代孕分析表明,使用污染燃料的工作母亲或分娩间隔较长的母亲的婴儿死亡风险更高;使用污染燃料的非工作母亲的分娩间隔较短也面临更高风险.
结论:
- 可解释的ML模型,特别是SVM,为婴儿死亡率决定因素提供全球和本地洞察力,有助于临床理解.
- 这些发现为决策者和利益相关者提供了关键信息,以制定有针对性的干预措施并改进家庭咨询策略.
- 可解释的ML增强了预测模型在解决诸如婴儿死亡率等关键公共卫生挑战中的实际应用.

相关概念视频
 01:15
Assumptions of Survival Analysis
97
Survival models analyze the time until one or more events occur, such as death in biological organisms or failure in mechanical systems. These models are widely used across fields like medicine, biology, engineering, and public health to study time-to-event phenomena. To ensure accurate results, survival analysis relies on key assumptions and careful study design.
97
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:19
Variation
6.7K
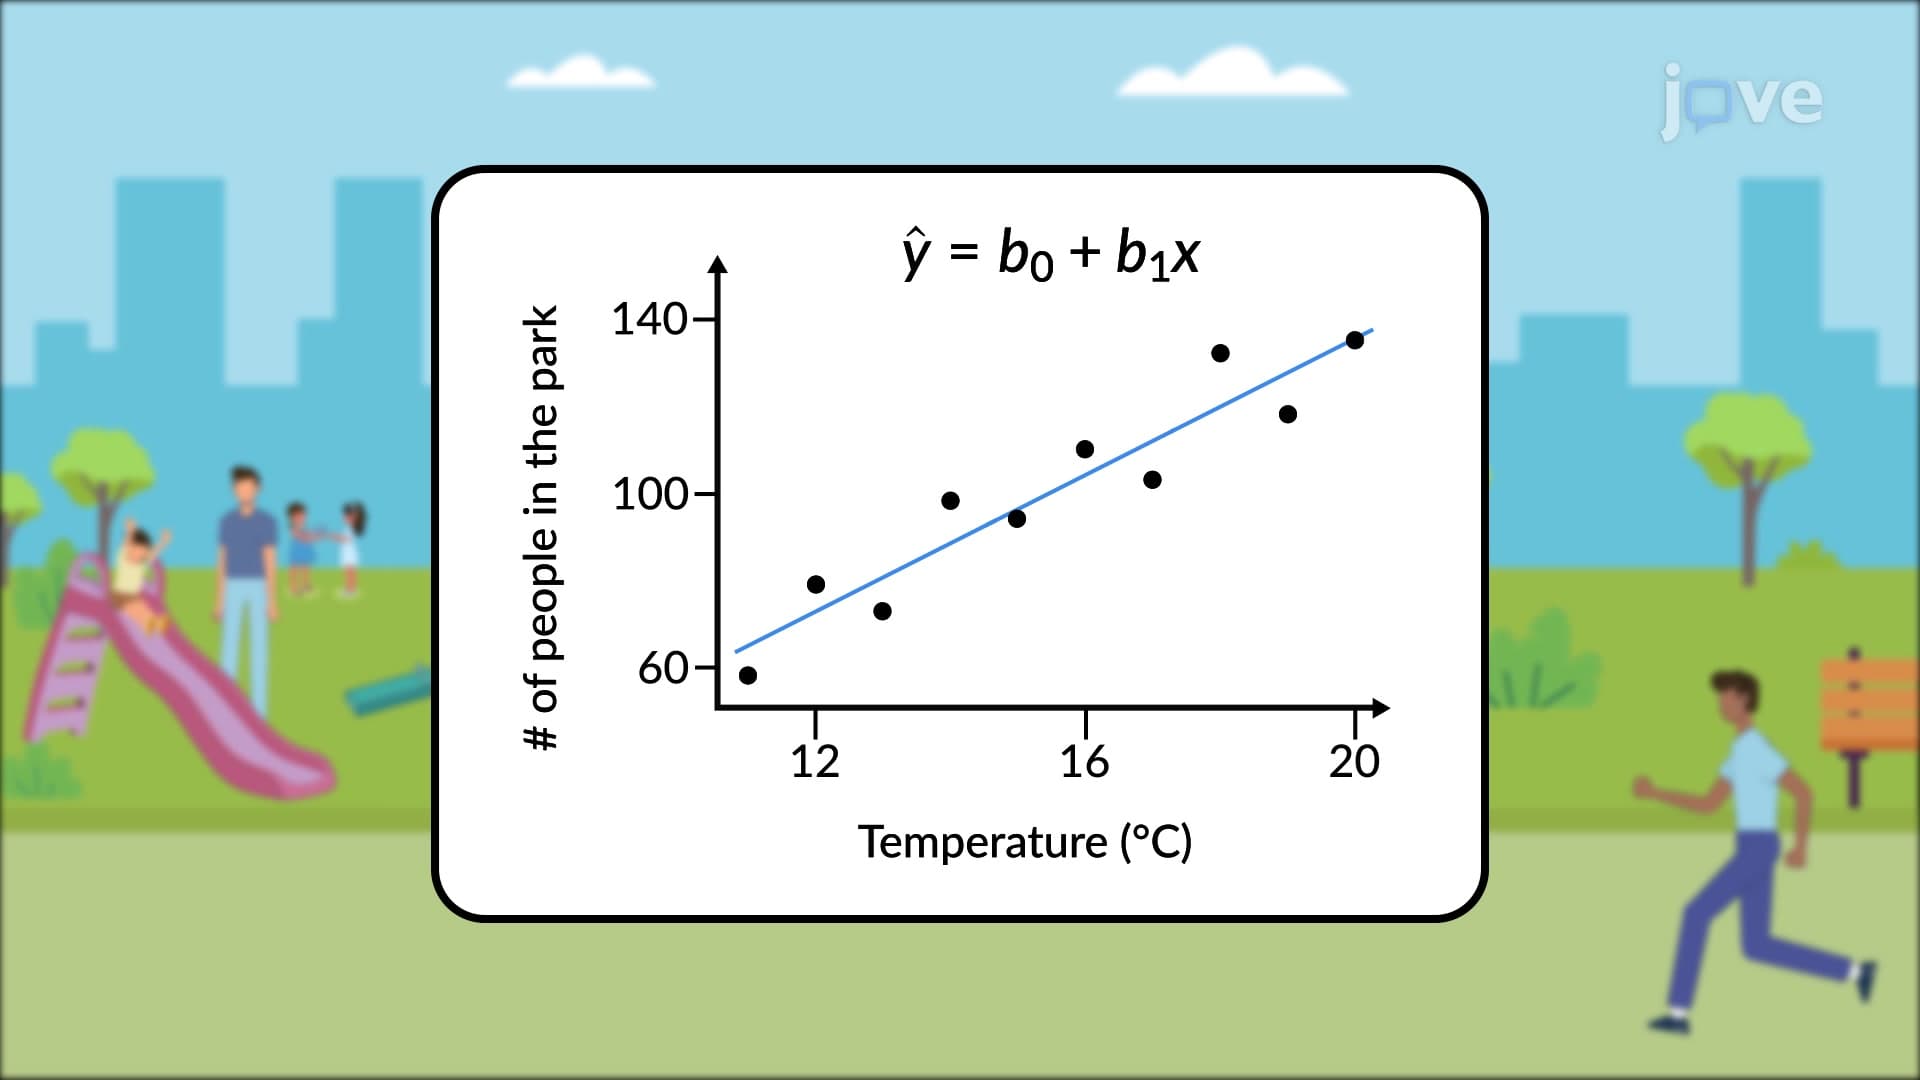
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.7K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
29
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
29
 01:11
Regression Analysis
5.6K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.6K