

一个内在可解释的深度学习模型,用于使用视觉概念进行局部解释
Mirza Ahsan Ullah1,2, Tehseen Zia1, Jungeun Kim3
1Department of Computer Science, COMSATS University Islamabad, Islamabad, Pakistan.
PloS one
|October 28, 2024

概括
本研究介绍了CA-SoftNet,这是一种新的深度学习模型,它使用基于概念的解释来解释可解释的人工智能. 它实现了高精度,同时为其决策提供了人类可以理解的推理.
科学领域:
- 计算机视觉 计算机视觉
- 人工智能的人工智能
- 可解释的人工智能 (XAI)
背景情况:
- 深度学习模型虽然强大,但往往缺乏透明度,引发了对公平性和可靠性的担忧.
- 现有的可解释方法与本地解释作斗争,并可能提取无关的概念.
- 人类的推理依赖于高层次的概念,这是目前可解释的方法无法完全弥合的差距.
研究的目的:
- 开发一种新的可解释的深度学习框架,与人类的概念推理保持一致.
- 解决现有的基于概念的可解释性方法的局限性,例如缺乏本地解释和不相关的概念提取.
- 通过透明的推理,提高深度学习模型的公平性,可靠性和可信度.
主要方法:
- 提出了跨注意力快速/缓慢思维网络 (CA-SoftNet),灵感来自于双流程理论.
- 集成一个浅卷积神经网络 (sCNN) 快速模式识别 (系统-I) 和一个交叉注意力概念记忆网络用于逻辑推理 (系统-II).
- 介绍了一种新的概念提取方法,用于识别突出概念并生成基于概念的本地解释.
主要成果:
- 在各种数据集中实现了具有竞争力的准确性:85.6% (CUB 200-2011),83.7% (斯坦福汽车),93.6% (ISIC 2016) 和90.3% (ISIC 2017).
- 超越现有的可解释模型,并证明性能与不可解释的对应模型相美.
- 成功生成基于概念的本地解释,与人类认知过程保持一致.
结论:
- CA-SoftNet通过弥合低级特征和高级人类概念之间的差距,为可解释的深度学习提供了一种有前途的方法.
- 该模型能够提取突出的概念并提供本地解释,提高了透明度和可信度.
- 跨班级的概念共享提高了可扩展性,并诱导了类似人类的认知,为更可靠的AI系统铺平了道路.

相关概念视频
 01:15
Depth Perception and Spatial Vision
600
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
600
 01:26
Visual System
552
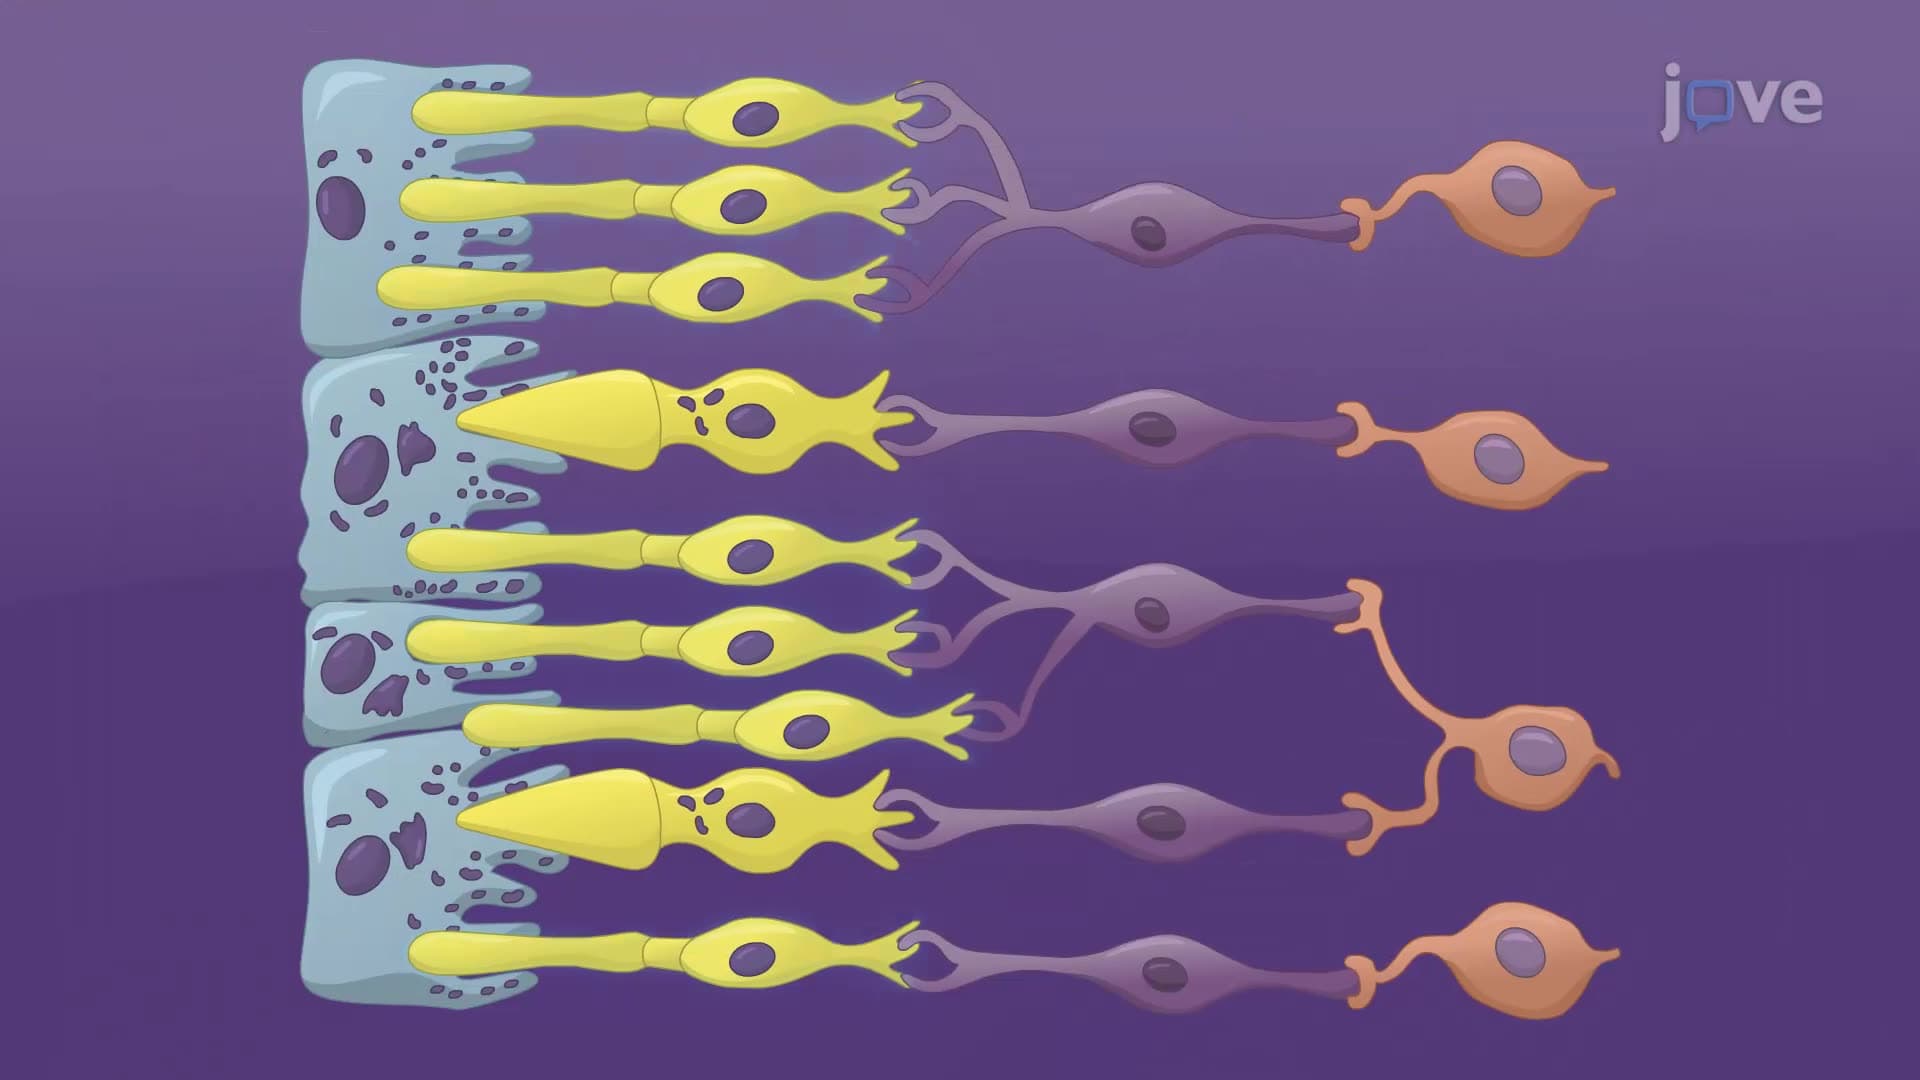
Light enters the eye through the cornea, a transparent, dome-shaped surface covering the surface of the eyeball that helps to direct and focus incoming light. This light is then channeled toward the pupil, an adjustable opening whose size is controlled by the iris. The iris, a pigmented muscle, regulates the amount of light entering the eye by contracting or dilating the pupil, thereby ensuring optimal light levels for clear vision.
Once through the pupil, the light passes through the lens, a...
Once through the pupil, the light passes through the lens, a...
552
 01:24
Vision
53.0K
Vision is the result of light being detected and transduced into neural signals by the retina of the eye. This information is then further analyzed and interpreted by the brain. First, light enters the front of the eye and is focused by the cornea and lens onto the retina—a thin sheet of neural tissue lining the back of the eye. Because of refraction through the convex lens of the eye, images are projected onto the retina upside-down and reversed.
53.0K
 01:20
Deconvolution
137
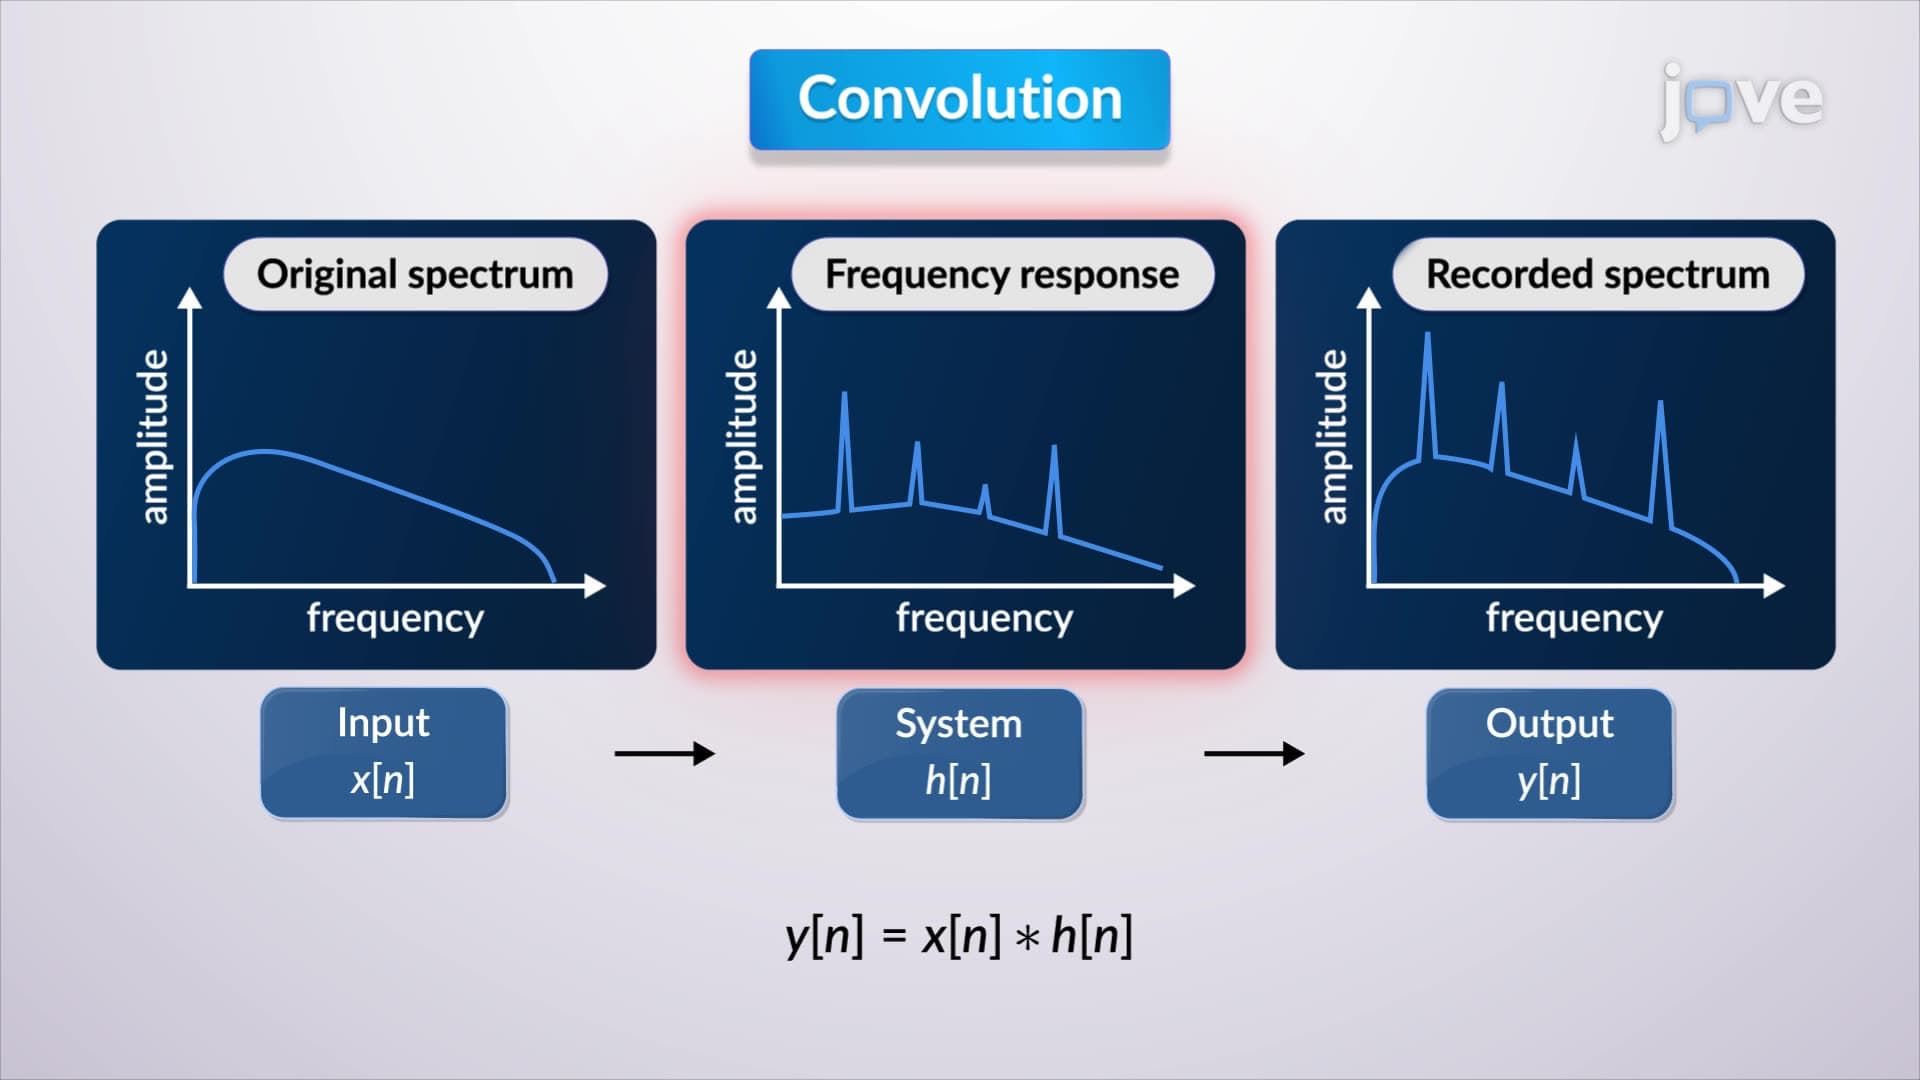
Deconvolution, also known as inverse filtering, is the process of extracting the impulse response from known input and output signals. This technique is vital in scenarios where the system's characteristics are unknown, and they must be inferred from the observable signals.
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
137
 01:27
Associative Learning
300
Associative learning is a fundamental concept in behavioral psychology, wherein a connection is established between two stimuli or events, leading to a learned response. This process is critical in understanding how behaviors are acquired and modified. Conditioning, the mechanism through which associations are formed, can be divided into two main types: classical conditioning and operant conditioning, each elucidating different aspects of associative learning.
Classical conditioning, also known...
Classical conditioning, also known...
300
 01:12
Perceptual Constancy
357
Perceptual constancy is the ability to recognize that objects remain consistent and unchanged even when their appearance varies due to changes in sensory input. There are four main types of perceptual constancy: size constancy, shape constancy, color constancy, and brightness constancy.
Size constancy is the recognition that an object remains the same size, even when its image on the retina changes. For instance, a bus is perceived to be large enough to carry people, even if it looks tiny from...
Size constancy is the recognition that an object remains the same size, even when its image on the retina changes. For instance, a bus is perceived to be large enough to carry people, even if it looks tiny from...
357