

计算预测误差差差异和预测准确度的方法 对于受限制的最好的线性不偏预测育种值的预测
1Graduate School of Agricultural Science, Tohoku University, Sendai, Miyagi, Japan.

概括
新的公式澄清了预测误差差 (PEV) 和预测准确性 (PA) 对于繁殖值 (BV) 的限制性最好的线性无偏预测 (RBLUP). 这简化了计算,并改善了育种计划中的选择反应预测.
科学领域:
- 动物育种与遗传学
- 量化遗传学 量化遗传学
- 统计基因组学 统计基因组学
背景情况:
- 精确预测繁殖值 (BVs) 对于有效的动物繁殖计划至关重要.
- 限制最佳线性无偏预测 (RBLUP) 方法被广泛使用,但缺乏预测误差差 (PEV) 和预测精度 (PA) 的明确公式.
- 这种模糊性阻碍了精确制定育种计划和预测选择反应.
研究的目的:
- 在RBLUP框架内推导和澄清PEV和PA的公式.
- 开发一种用于计算RBLUP的PEV和PA的实用方法.
- 阐明 RBLUP 和普通最好的线性无偏预测 (BLUP) 之间的关系.
主要方法:
- 从受限制的混合模型方程中推导PEV和PA公式.
- 开发一种计算方法,以便在RBLUP下轻松计算PEV和PA.
- 数学推导RBLUP与普通BLUP之间的关系.
主要成果:
- 证明了RBLUP对BVs的独特性.
- 在RBLUP中成功推导出PEV和PA的新型公式.
- 建立了一个有效的方法来计算基于RBLUP的PEV和PA.
- 在数学上定义了RBLUP和普通BLUP之间的关系.
结论:
- 由此得出的公式和计算方法大大简化了RBLUP中的PEV和PA评估.
- 这种进步有助于更准确地预测选择反应,特别是当目标是同时改善特征时.
- 这些发现增强了RBLUP方法在实际育种应用中的实用性.

相关概念视频
 01:19
Variation
6.8K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
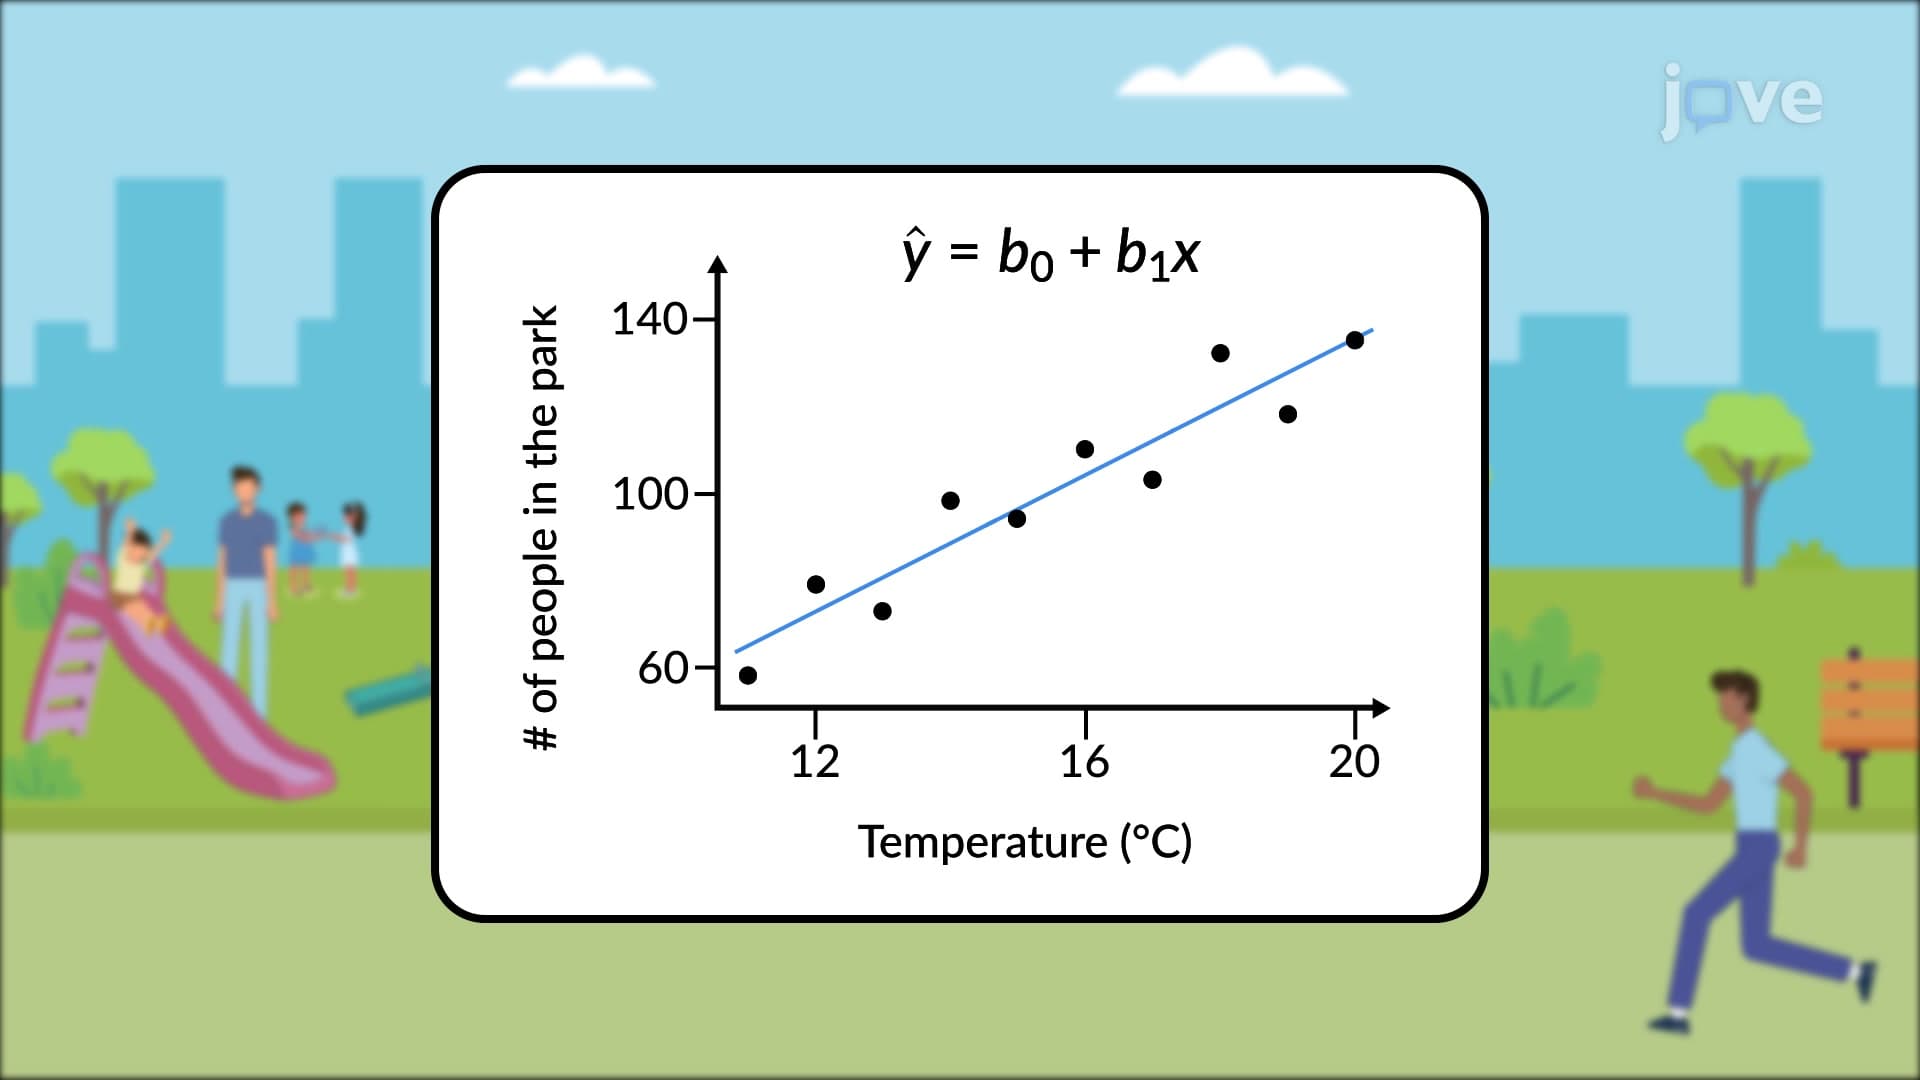
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.8K
 01:11
Residuals and Least-Squares Property
7.3K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.3K
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:13
Accuracy and Errors in Hypothesis Testing
183
Hypothesis testing is a fundamental statistical tool that begins with the assumption that the null hypothesis H0 is true. During this process, two types of errors can occur: Type I and Type II. A Type I error refers to the incorrect rejection of a true null hypothesis, while a Type II error involves the failure to reject a false null hypothesis.
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
183
 03:37
Uncertainty in Measurement: Accuracy and Precision
73.5K
Scientists typically make repeated measurements of a quantity to ensure the quality of their findings and to evaluate both the precision and the accuracy of their results. Measurements are said to be precise if they yield very similar results when repeated in the same manner. A measurement is considered accurate if it yields a result that is very close to the true or the accepted value. Precise values agree with each other; accurate values agree with a true value.
73.5K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K