

预测足球运动员在比赛中的表现的极端情况
Michał Nowak1,2, Bartosz Bok3, Artur Wilczek3
1Faculty of Physical Culture Sciences, Jan Dlugosz University in Czestochowa, Collegium Medicum. Dr. Wladyslaw Bieganski, 42-200, Czestochowa, Poland. michal.nowak@rakow.com.
Scientific reports
|November 8, 2024

概括
简单的线性模型使用历史训练和比赛数据准确地预测足球运动员的表现指标. 这些模型为日常培训规划和工作负载管理提供了宝贵的见解,帮助教练在战术决策中.
科学领域:
- 运动科学 运动科学 运动科学
- 数据分析数据分析数据分析.
- 业绩预测的性能预测.
背景情况:
- 足球表现依赖于复杂的生理和战术因素.
- 准确预测球员指标对于优化训练和比赛策略至关重要.
- 现有的预测模型可能缺乏针对单个球员表现的特异性.
研究的目的:
- 评价足球表现的简单线性和零碎线性预测模型的有效性.
- 通过使用历史训练和匹配数据来评估这些模型的准确性.
- 确定预测模型在日常训练规划和战术决策中的有用性.
主要方法:
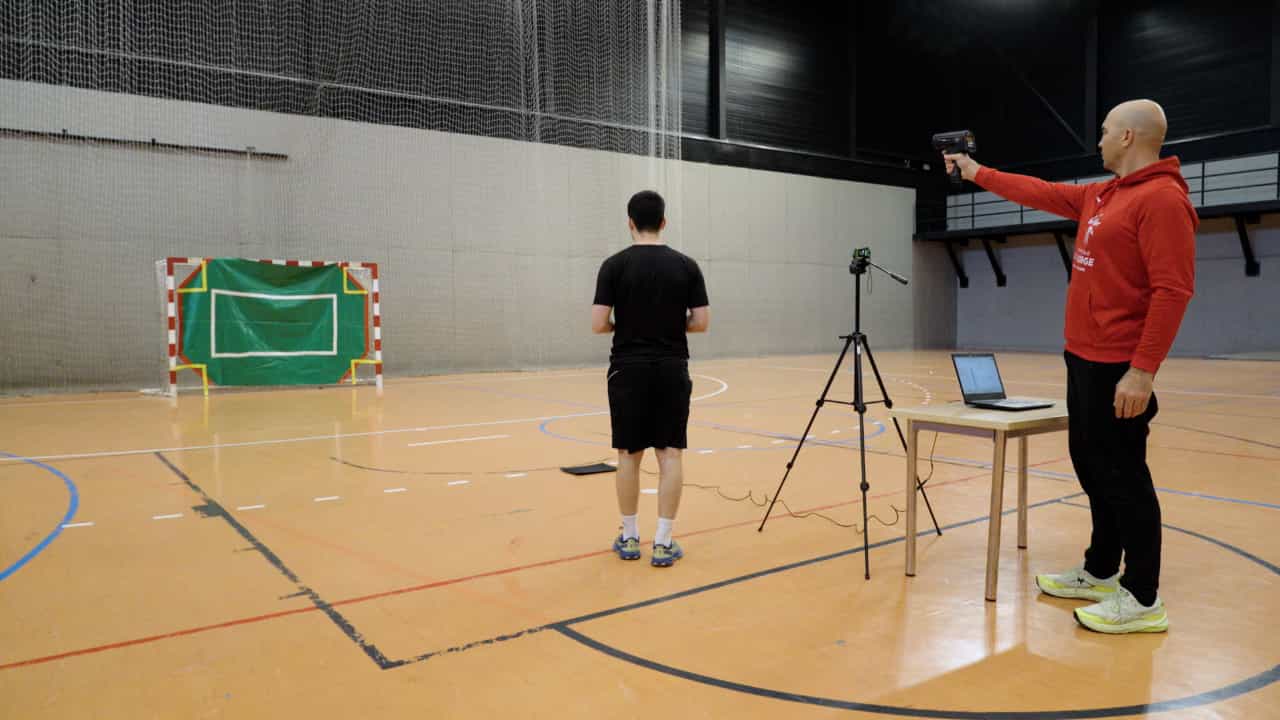
- 利用RKS Raków Częstochowa足球俱乐部 (2023年1月至6月) 的历史训练和比赛数据.
- 开发并测试了简单的线性和零碎的线性预测模型.
- 分析了性能指标,例如"代谢时间区5和6每距离"和"声明在区域5和6每距离的总距离",使用滑动窗口方法.
- 个人玩家模型与聚合 (玩家位置) 模型进行比较.
主要成果:
- 最好的单个模型在预测关键绩效指标时实现了2.3%的低相对误差.
- 基于APEX-PRO系统的聚合性能指标的模型显示了可接受的性能.
- 个人玩家模型通常表现优于聚合模型,尽管存在例外.
- 使用上一场比赛数据的模型也在预测极端运动性能方面表现出有效性.
结论:
- 简单的线性和片式线性模型可以有效地预测极端足球表现指标,并具有高准确性.
- 这些预测模型,尽管绝对可靠性的局限性,但对于日常训练管理和战术规划来说是有价值的工具.
- 个人玩家数据是准确预测的关键,突出了个性化分析的必要性.
- 需要进一步的研究来完善这些模型,并探索它们在足球分析中的全部潜力.
相关概念视频
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:04
Social Facilitation
31.8K
Not all intergroup interactions lead to negative outcomes. Sometimes, being in a group situation can improve performance. Social facilitation occurs when an individual performs better when an audience is watching than when the individual performs the behavior alone. This typically occurs when people are performing a task for which they are skilled.
31.8K
 01:10
Standard Deviation
15.9K
The most commonly used measure of variation is the standard deviation. It is a numerical value measuring how far data values are from their mean. The standard deviation value is small when the data are concentrated close to the mean, exhibiting slight variation or spread. The standard deviation value is never negative, it is either positive or zero. The standard deviation is larger when the data values are more spread out from the mean, which means the data values are exhibiting more variation.
15.9K
 01:16
Unusual Results
3.1K
Unusual results are those that have a very low chance of occurring. Unusual results can be identified using probabilities and the range rule of thumb. In problems involving probability, unusual results can be observed in 2 instances – an unusually high number of successes or an unusually low number of successes.
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
3.1K
 01:08
Determination of Expected Frequency
2.1K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.1K
 01:05
Estimation of the Physical Quantities
4.2K
On many occasions, physicists, other scientists, and engineers need to make estimates of a particular quantity. These are sometimes referred to as guesstimates, order-of-magnitude approximations, back-of-the-envelope calculations, or Fermi calculations. The physicist Enrico Fermi was famous for his ability to estimate various kinds of data with surprising precision. Estimating does not mean guessing a number or a formula at random. Instead, estimation means using prior experience and sound...
4.2K